内容提要
TL;DR
Agent 需要上下文来执行任务。上下文工程是一门艺术,也是一门科学:在 Agent 执行轨迹的每一步,将恰到好处的信息填入上下文窗口。本文通过考察多种流行 Agent 和论文,梳理上下文工程的四类常见策略:写入、选择、压缩与隔离。随后,我们将解释 LangGraph 在设计上如何支持这些策略!
Agents need context to perform tasks. Context engineering is the art and science of filling the context window with just the right information at each step of an agent’s trajectory. In this post, we break down some common strategies — write, select, compress, and isolate — for context engineering by reviewing various popular agents and papers. We then explain how LangGraph is designed to support them!
也欢迎观看我们关于上下文工程的视频。
Also, see our video on context engineering here.
上下文工程
Context Engineering
正如 Andrej Karpathy 所说,大语言模型就像一种新型操作系统。大语言模型好比 CPU,其上下文窗口好比 RAM,充当模型的工作记忆。与 RAM 一样,上下文窗口用于处理各种上下文来源的容量是有限的。正如操作系统会安排哪些内容进入 CPU 使用的 RAM,我们也可以认为“上下文工程”扮演着类似的角色。Karpathy 对此有一个很好的概括:
As Andrej Karpathy puts it, LLMs are like a new kind of operating system. The LLM is like the CPU and its context window is like the RAM, serving as the model’s working memory. Just like RAM, the LLM context window has limited capacity to handle various sources of context. And just as an operating system curates what fits into a CPU’s RAM, we can think about “context engineering” playing a similar role. Karpathy summarizes this well:
[上下文工程是]“……为下一步向上下文窗口填入恰到好处的信息,这门精细的艺术与科学。”
[Context engineering is the] ”…delicate art and science of filling the context window with just the right information for the next step.”
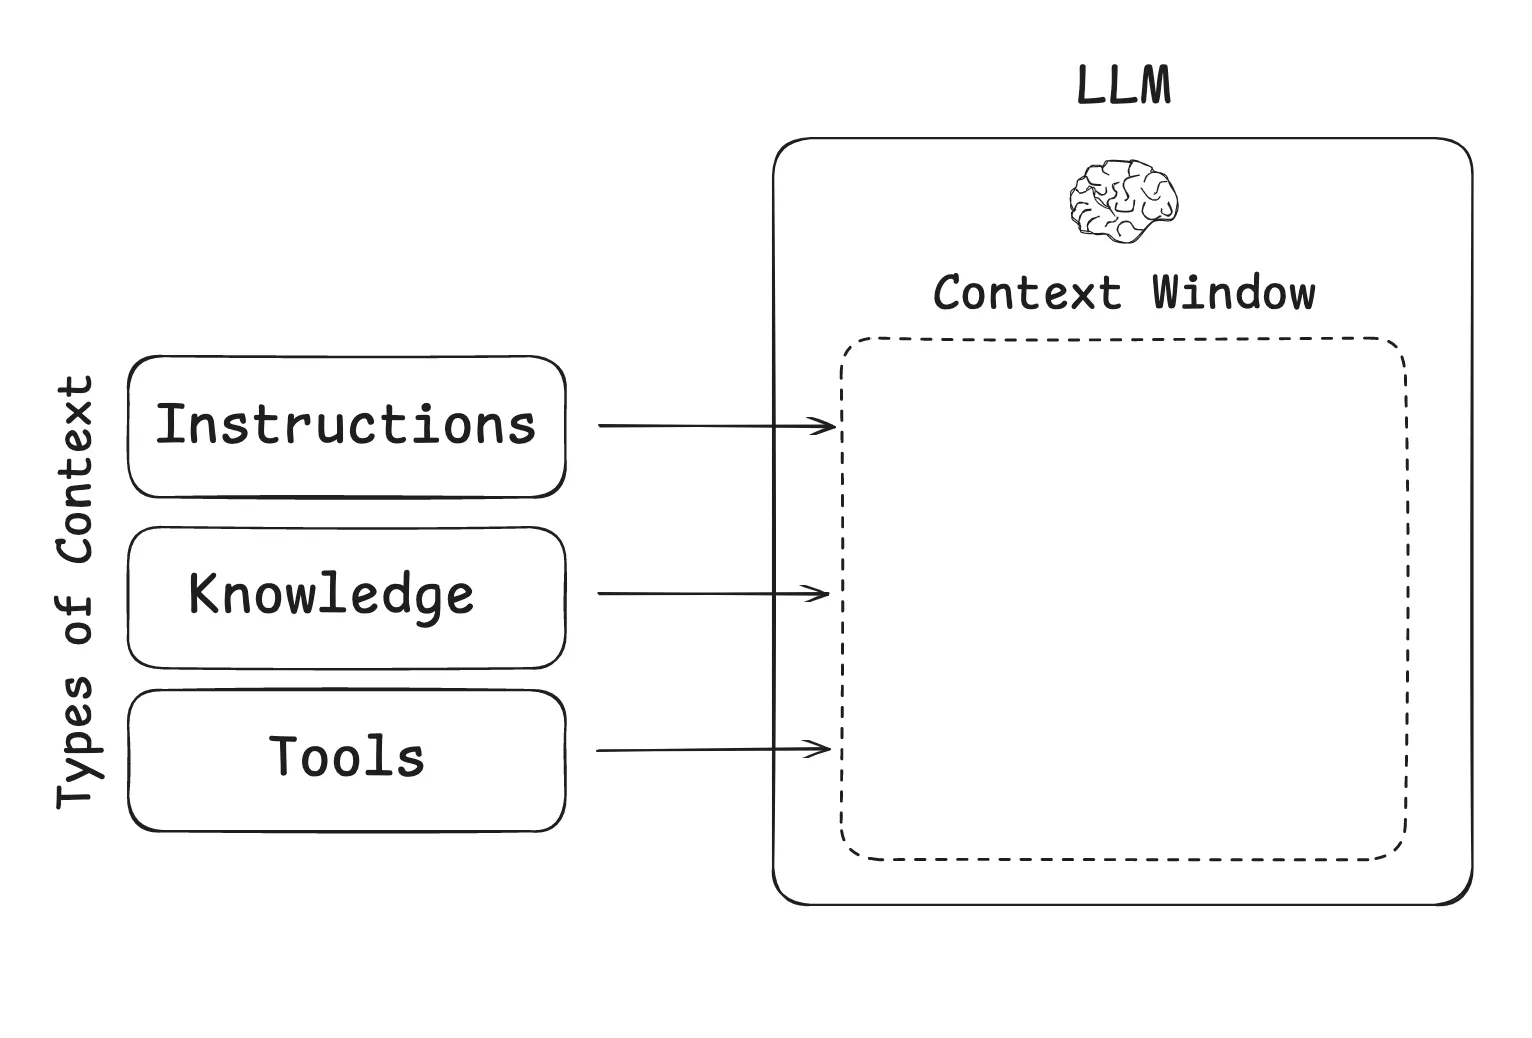
构建大语言模型应用时,我们需要管理哪些类型的上下文?上下文工程是一个统括性概念,涵盖几种不同的上下文类型:
What are the types of context that we need to manage when building LLM applications? Context engineering as an umbrella that applies across a few different context types:
- 指令:提示词、记忆、少样本示例、工具描述等。
- 知识:事实、记忆等。
- 工具:工具调用返回的反馈。
- Instructions – prompts, memories, few‑shot examples, tool descriptions, etc
- Knowledge – facts, memories, etc
- Tools – feedback from tool calls
面向 Agent 的上下文工程
Context Engineering for Agents
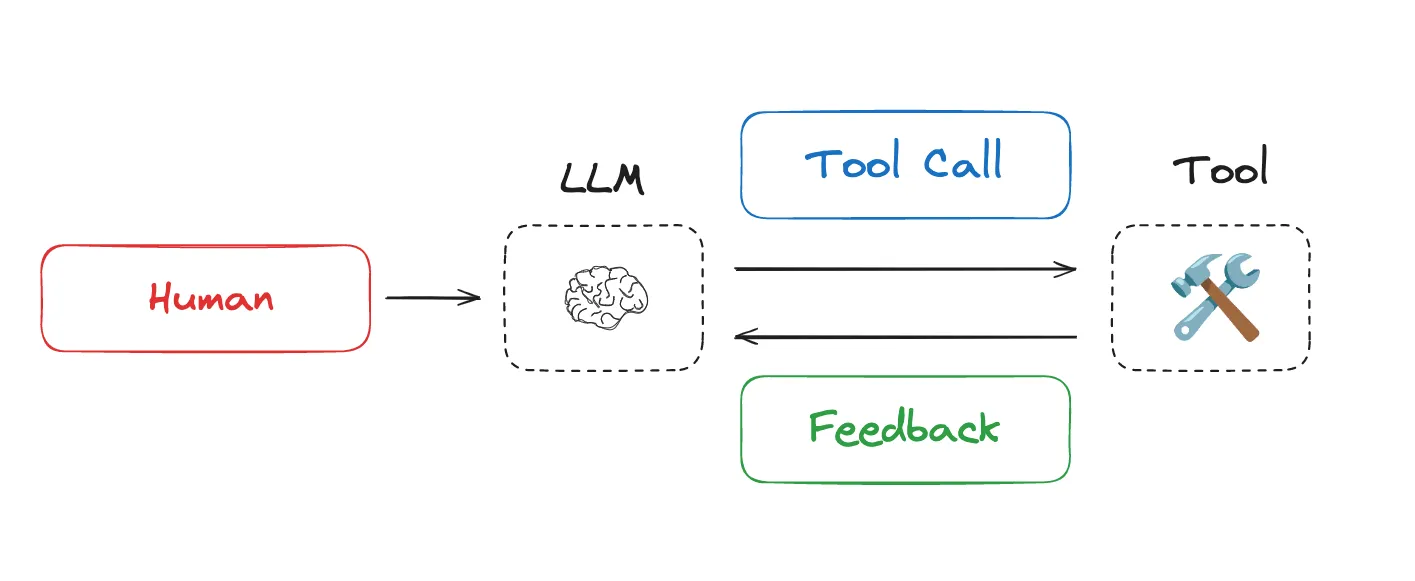
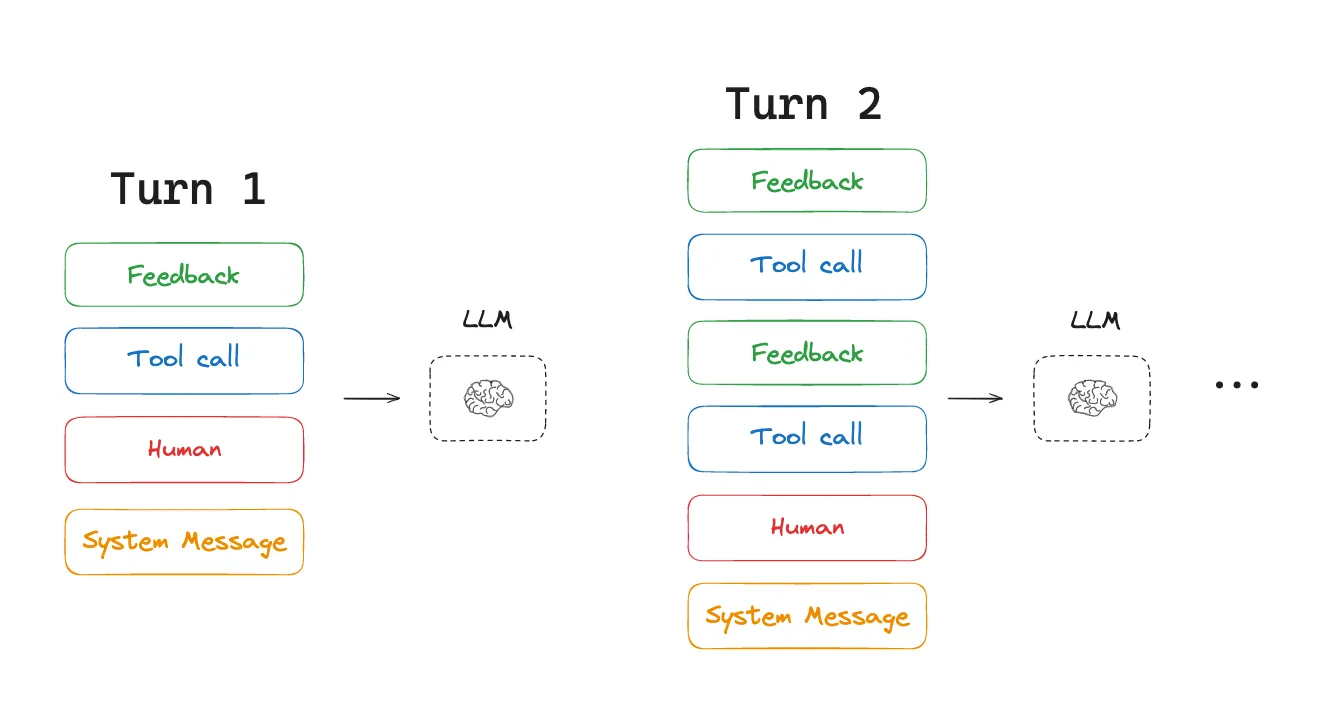
随着大语言模型越来越擅长推理和工具调用,今年人们对 Agent 的兴趣大幅增长。Agent 交替进行大语言模型调用与工具调用,通常用于长时间运行的任务。Agent 交替执行模型调用与工具调用,利用工具反馈决定下一步。
This year, interest in agents has grown tremendously as LLMs get better at reasoning and tool calling. Agents interleave LLM invocations and tool calls, often for long-running tasks. Agents interleave LLM calls and tool calls, using tool feedback to decide the next step.
然而,长时间运行的任务和不断累积的工具调用反馈,意味着 Agent 往往会使用大量 token。这会带来许多问题:超出上下文窗口容量,使成本和时延急剧增加,或降低 Agent 表现。Drew Breunig 清晰地梳理了长上下文导致性能问题的几种具体方式,包括:
However, long-running tasks and accumulating feedback from tool calls mean that agents often utilize a large number of tokens. This can cause numerous problems: it can exceed the size of the context window, balloon cost / latency, or degrade agent performance. Drew Breunig nicely outlined a number of specific ways that longer context can cause perform problems, including:
考虑到这些问题,Cognition 强调了上下文工程的重要性:
With this in mind, Cognition called out the importance of context engineering:
“上下文工程”……实际上是构建 AI Agent 的工程师最重要的工作。
“Context engineering” … is effectively the #1 job of engineers building AI agents.
Anthropic 也说得很清楚:
Anthropic also laid it out clearly:
Agent 经常参与长达数百轮的对话,需要周密的上下文管理策略。
Agents often engage in conversations spanning hundreds of turns, requiring careful context management strategies.
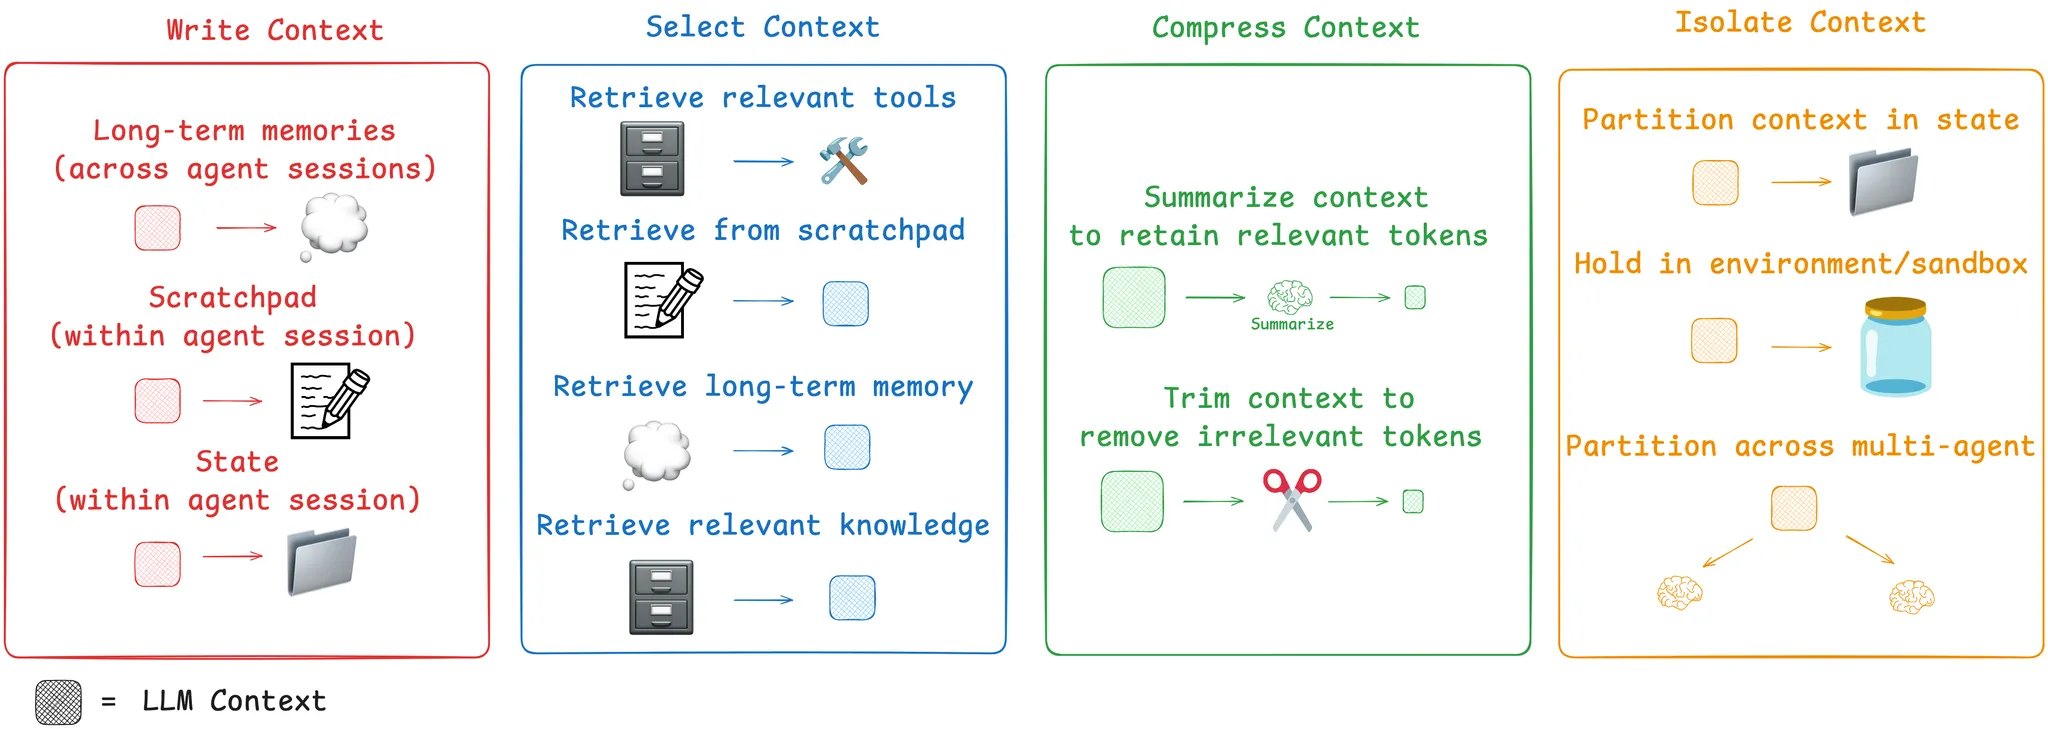
那么,现在大家如何应对这个挑战?我们将 Agent 上下文工程的常见策略分成四类:写入、选择、压缩与隔离。通过考察一些流行的 Agent 产品和论文,我们为每一类提供实例,然后解释 LangGraph 在设计上如何支持它们!
So, how are people tackling this challenge today? We group common strategies for agent context engineering into four buckets — write, select, compress, and isolate — and give examples of each from review of some popular agent products and papers. We then explain how LangGraph is designed to support them!
写入上下文
Write Context
写入上下文,是将信息保存在上下文窗口之外,帮助 Agent 执行任务。
Writing context means saving it outside the context window to help an agent perform a task.
草稿板
Scratchpads
人类解决任务时,会记笔记、记住一些事情,以便日后处理相关任务。Agent 也正在获得这些能力!通过“草稿板”记笔记,是 Agent 执行任务时持久保存信息的一种方法。其思路是将信息保存在上下文窗口之外,供 Agent 使用。Anthropic 的多 Agent 研究系统提供了一个清晰的例子:
When humans solve tasks, we take notes and remember things for future, related tasks. Agents are also gaining these capabilities! Note-taking via a “scratchpad” is one approach to persist information while an agent is performing a task. The idea is to save information outside of the context window so that it’s available to the agent. Anthropic’s multi-agent researcher illustrates a clear example of this:
LeadResearcher 首先思考研究方法,并将计划保存到 Memory 中,让上下文持久化;因为上下文窗口一旦超过 200,000 个 token,就会被截断,而保留计划十分重要。
The LeadResearcher begins by thinking through the approach and saving its plan to Memory to persist the context, since if the context window exceeds 200,000 tokens it will be truncated and it is important to retain the plan.
草稿板可以有几种不同的实现方式。它可以是一个简单地写入文件的工具调用,也可以是运行时状态对象中的某个字段,在整个会话中持续存在。无论哪种方式,草稿板都让 Agent 能够保存有用信息,帮助其完成任务。
Scratchpads can be implemented in a few different ways. They can be a tool call that simply writes to a file. They can also be a field in a runtime state object that persists during the session. In either case, scratchpads let agents save useful information to help them accomplish a task.
记忆
Memories
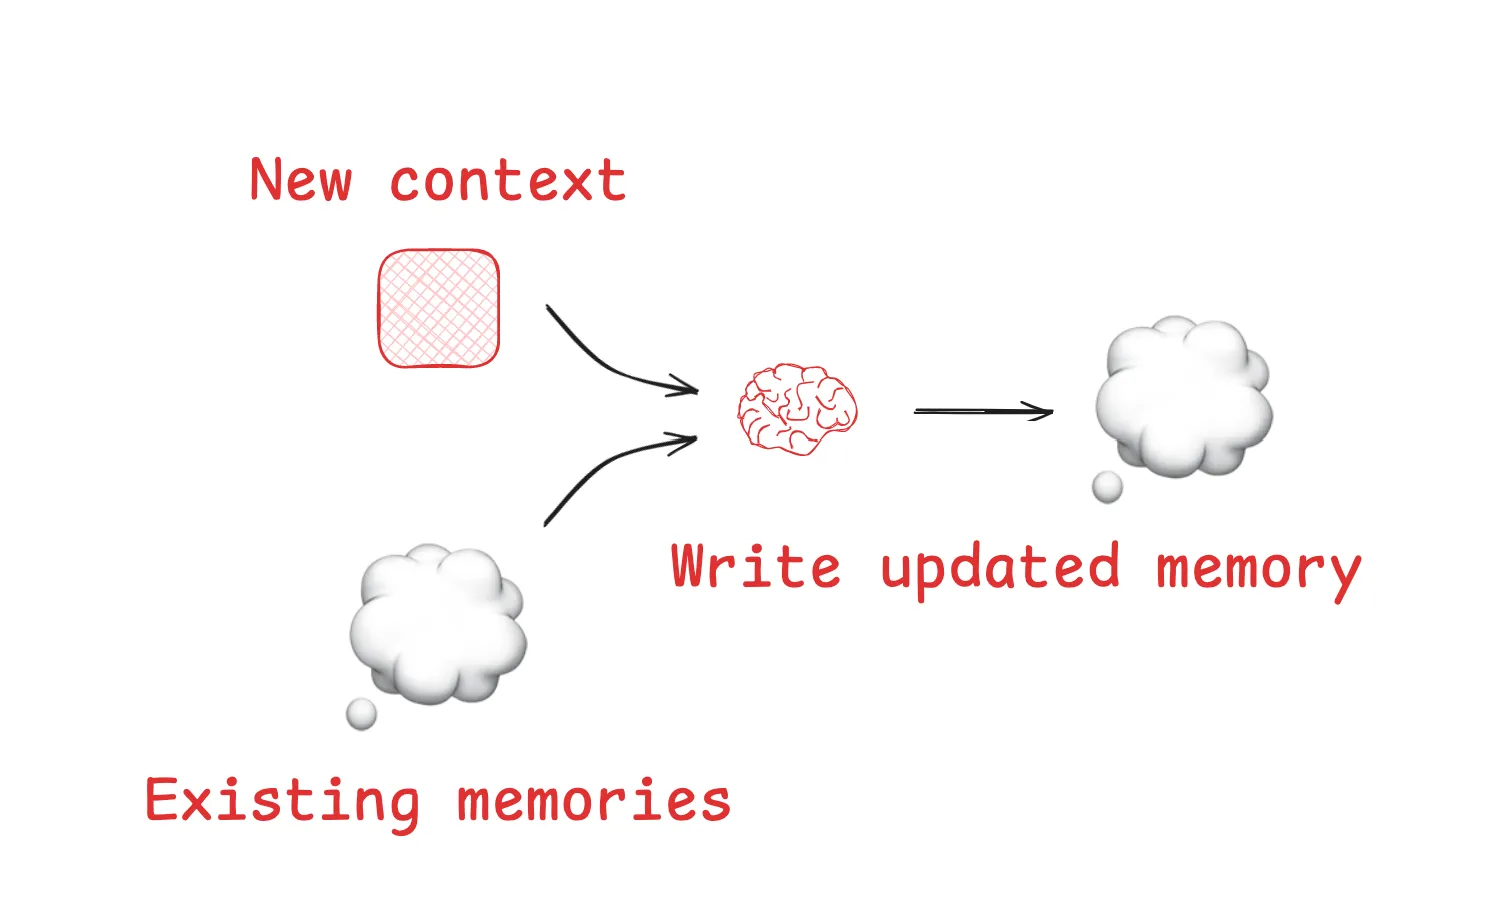
草稿板帮助 Agent 在给定会话或线程中解决任务,但有时,跨越许多会话记住信息也很有帮助!Reflexion 提出了在每轮 Agent 交互后进行反思,并复用这些自行生成的记忆。Generative Agents 则定期汇总以往 Agent 的反馈集合,生成记忆。
Scratchpads help agents solve a task within a given session (or thread), but sometimes agents benefit from remembering things across many sessions! Reflexion introduced the idea of reflection following each agent turn and re-using these self-generated memories. Generative Agents created memories synthesized periodically from collections of past agent feedback.
选择上下文
Select Context
选择上下文,是将信息取入上下文窗口,帮助 Agent 执行任务。
Selecting context means pulling it into the context window to help an agent perform a task.
草稿板
Scratchpad
从草稿板中选择上下文的机制,取决于草稿板的实现方式。如果它是一个工具,Agent 只需调用工具就能读取。如果它属于 Agent 的运行时状态,开发者就可以决定每一步向 Agent 暴露哪些状态内容。这让开发者能够细粒度控制,在后续轮次中向大语言模型提供哪些草稿板上下文。
The mechanism for selecting context from a scratchpad depends upon how the scratchpad is implemented. If it’s a tool, then an agent can simply read it by making a tool call. If it’s part of the agent’s runtime state, then the developer can choose what parts of state to expose to an agent each step. This provides a fine-grained level of control for exposing scratchpad context to the LLM at later turns.
记忆
Memories
如果 Agent 能够保存记忆,也就需要能够选择与当前任务相关的记忆。这有几方面用途:Agent 可以选择少样本示例,作为预期行为的范例,即情景记忆;选择指令来引导行为,即程序性记忆;或选择事实来提供任务相关上下文,即语义记忆。
If agents have the ability to save memories, they also need the ability to select memories relevant to the task they are performing. This can be useful for a few reasons. Agents might select few-shot examples (episodic memories) for examples of desired behavior, instructions (procedural memories) to steer behavior, or facts (semantic memories) for task-relevant context.
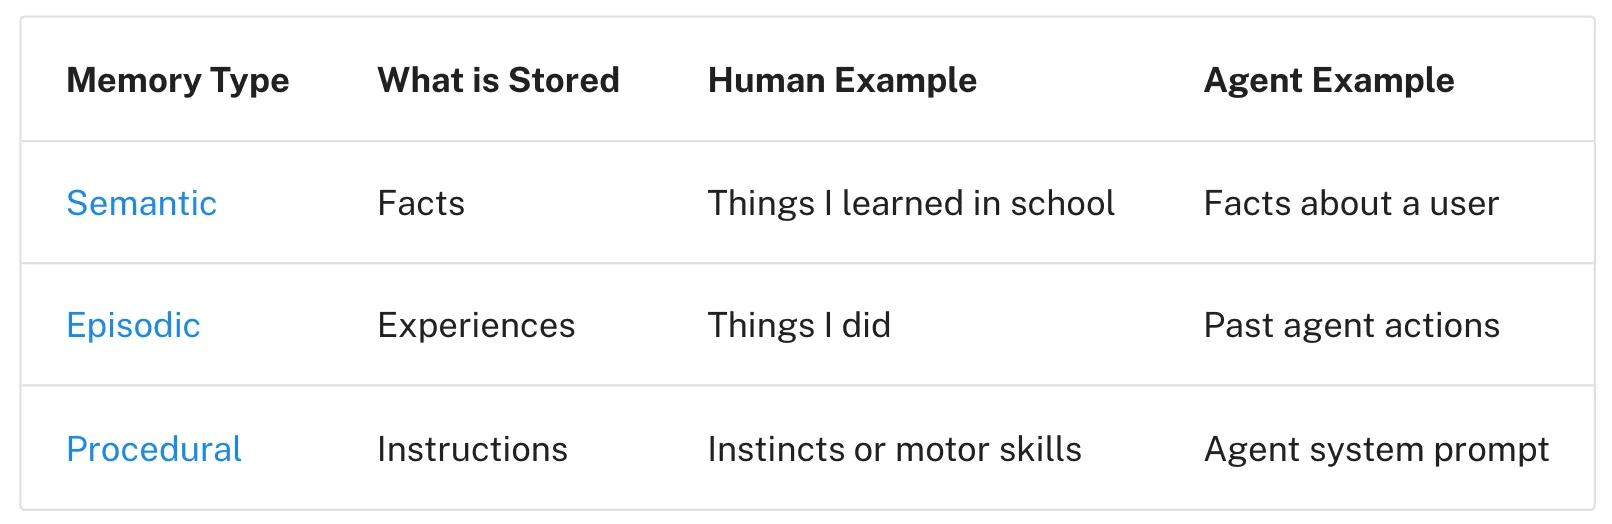
其中一个挑战,是确保选中的记忆确实相关。一些流行 Agent 只是使用一小组文件,并始终将它们放入上下文。例如,许多编程 Agent 使用特定文件保存指令,也就是“程序性”记忆;有时也保存示例,也就是“情景”记忆。Claude Code 使用 CLAUDE.md。Cursor 和 Windsurf 则使用规则文件。
One challenge is ensuring that relevant memories are selected. Some popular agents simply use a narrow set of files that are always pulled into context. For example, many code agent use specific files to save instructions (”procedural” memories) or, in some cases, examples (”episodic” memories). Claude Code uses CLAUDE.md. Cursor and Windsurf use rules files.
But, if an agent is storing a larger collection of facts and / or relationships (e.g., semantic memories), selection is harder. ChatGPT is a good example of a popular product that stores and selects from a large collection of user-specific memories.
人们常用嵌入向量或知识图谱为记忆建立索引,帮助进行选择。但记忆选择仍然很有挑战。在 AIEngineer World’s Fair 上,Simon Willison 分享过一个选择出错的例子:ChatGPT 从记忆中取出了他的位置信息,意外地把它加入了他请求生成的图片。这种出乎意料或不受欢迎的记忆检索,可能让一些用户觉得,上下文窗口“已经不再属于自己”!
Embeddings and / or knowledge graphs for memory indexing are commonly used to assist with selection. Still, memory selection is challenging. At the AIEngineer World’s Fair, Simon Willison shared an example of selection gone wrong: ChatGPT fetched his location from memories and unexpectedly injected it into a requested image. This type of unexpected or undesired memory retrieval can make some users feel like the context window “no longer belongs to them”!
工具
Tools
Agent 会使用工具,但如果提供的工具太多,也可能不堪重负。这通常是因为工具描述相互重叠,让模型难以判断应该使用哪个工具。一种方法是对工具描述应用 RAG(检索增强生成),只获取与任务最相关的工具。一些近期论文表明,这种方法能让工具选择准确率达到原来的 3 倍。
Agents use tools, but can become overloaded if they are provided with too many. This is often because the tool descriptions overlap, causing model confusion about which tool to use. One approach is to apply RAG (retrieval augmented generation) to tool descriptions in order to fetch only the most relevant tools for a task. Some recent papers have shown that this improve tool selection accuracy by 3-fold.
知识
Knowledge
RAG 是一个内容丰富的主题,也可能是上下文工程的核心挑战。编程 Agent 是 RAG 在大规模生产环境中应用的典型案例。Windsurf 的 Varun 很好地概括了其中一些挑战:
RAG is a rich topic and it can be a central context engineering challenge. Code agents are some of the best examples of RAG in large-scale production. Varun from Windsurf captures some of these challenges well:
代码索引 ≠ 上下文检索……[我们正在进行索引与嵌入搜索……[通过]AST 解析代码,并沿着具有语义意义的边界分块……随着代码库规模增长,嵌入搜索作为检索启发式方法会变得不可靠……我们必须结合 grep/文件搜索、基于知识图谱的检索等多种技术,以及……一个按相关性对[上下文]排序的重排序步骤。
Indexing code ≠ context retrieval … [We are doing indexing & embedding search … [with] AST parsing code and chunking along semantically meaningful boundaries … embedding search becomes unreliable as a retrieval heuristic as the size of the codebase grows … we must rely on a combination of techniques like grep/file search, knowledge graph based retrieval, and … a re-ranking step where [context] is ranked in order of relevance.
压缩上下文
Compressing Context
压缩上下文,是仅保留执行任务所需的 token。
Compressing context involves retaining only the tokens required to perform a task.
上下文摘要
Context Summarization
Agent 交互可能长达数百轮,还会包含 token 用量很大的工具调用。生成摘要,是应对这些挑战的常见方法。如果使用过 Claude Code,你就见过这个过程。上下文窗口的使用量超过 95% 后,Claude Code 会运行“自动压缩”,总结用户与 Agent 交互的完整轨迹。对Agent 执行轨迹进行这种压缩,可以采用递归摘要或分层摘要等不同策略。
Agent interactions can span hundreds of turns and use token-heavy tool calls. Summarization is one common way to manage these challenges. If you’ve used Claude Code, you’ve seen this in action. Claude Code runs “auto-compact” after you exceed 95% of the context window and it will summarize the full trajectory of user-agent interactions. This type of compression across an agent trajectory can use various strategies such as recursive or hierarchical summarization.
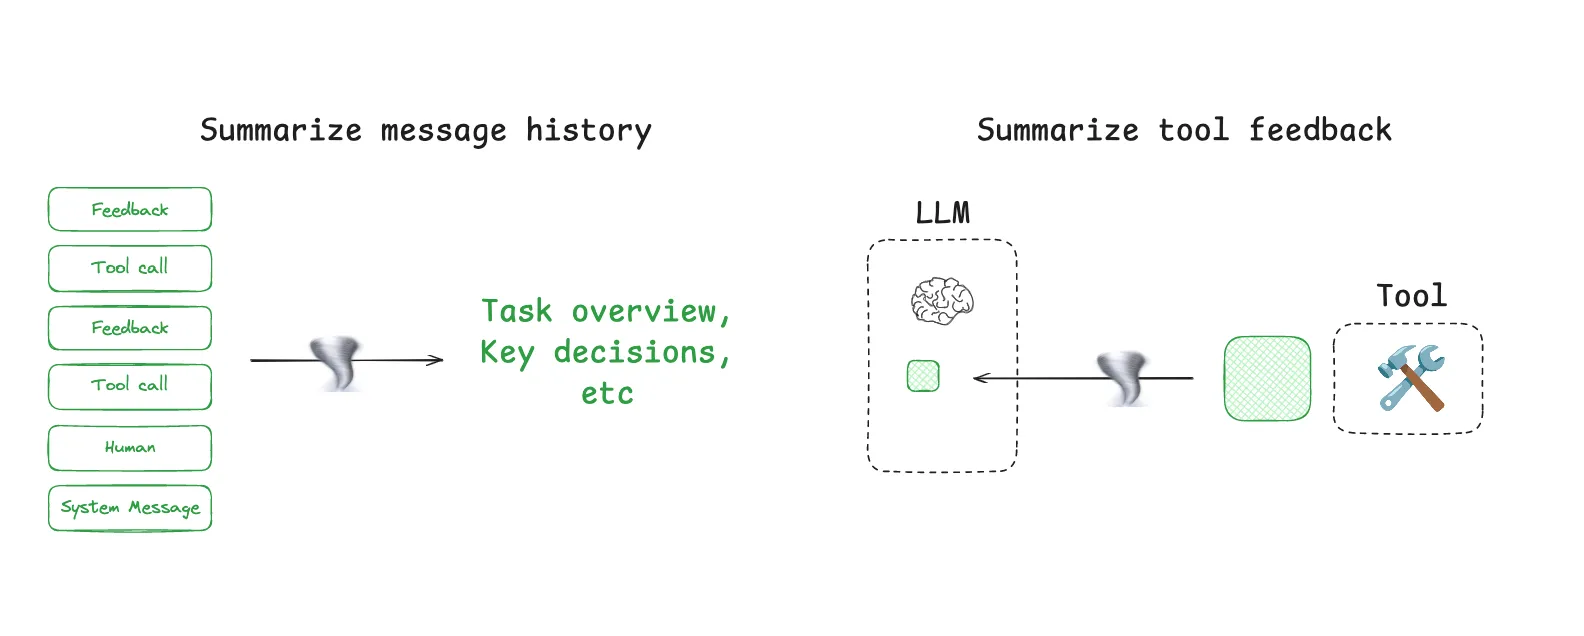
在 Agent 设计的特定位置加入摘要处理也很有帮助。例如,可以对某些工具调用进行后处理,如 token 用量很大的搜索工具。另一个例子是,Cognition 提到,可以在 Agent 之间的交接边界生成摘要,减少知识交接时的 token 用量。如果必须保留特定事件或决策,摘要就可能很有挑战。Cognition 为此使用了微调模型,这也说明了这个步骤可能需要投入多少工作。
It can also be useful to add summarization at specific points in an agent’s design. For example, it can be used to post-process certain tool calls (e.g., token-heavy search tools). As a second example, Cognition mentioned summarization at agent-agent boundaries to reduce tokens during knowledge hand-off. Summarization can be a challenge if specific events or decisions need to be captured. Cognition uses a fine-tuned model for this, which underscores how much work can go into this step.
上下文裁剪
Context Trimming
摘要通常使用大语言模型提炼上下文中最相关的内容,而裁剪通常可以直接过滤上下文,或如 Drew Breunig 所说,对其进行“剪枝”。它可以使用硬编码的启发式规则,例如从列表中删除较早的消息。Drew 还提到了 Provence,这是一个针对问答任务训练的上下文剪枝模型。
Whereas summarization typically uses an LLM to distill the most relevant pieces of context, trimming can often filter or, as Drew Breunig points out, “prune” context. This can use hard-coded heuristics like removing older messages from a list. Drew also mentions Provence, a trained context pruner for Question-Answering.
隔离上下文
Isolating Context
隔离上下文,是将上下文拆开,帮助 Agent 执行任务。
Isolating context involves splitting it up to help an agent perform a task.
多 Agent
Multi-agent
隔离上下文最常见的方法之一,是将其分配给不同子 Agent。OpenAI Swarm 库的一个设计动机就是关注点分离,让一组 Agent 分别处理特定子任务。每个 Agent 都有特定的工具集、指令,以及自己的上下文窗口。
One of the most popular ways to isolate context is to split it across sub-agents. A motivation for the OpenAI Swarm library was separation of concerns, where a team of agents can handle specific sub-tasks. Each agent has a specific set of tools, instructions, and its own context window.
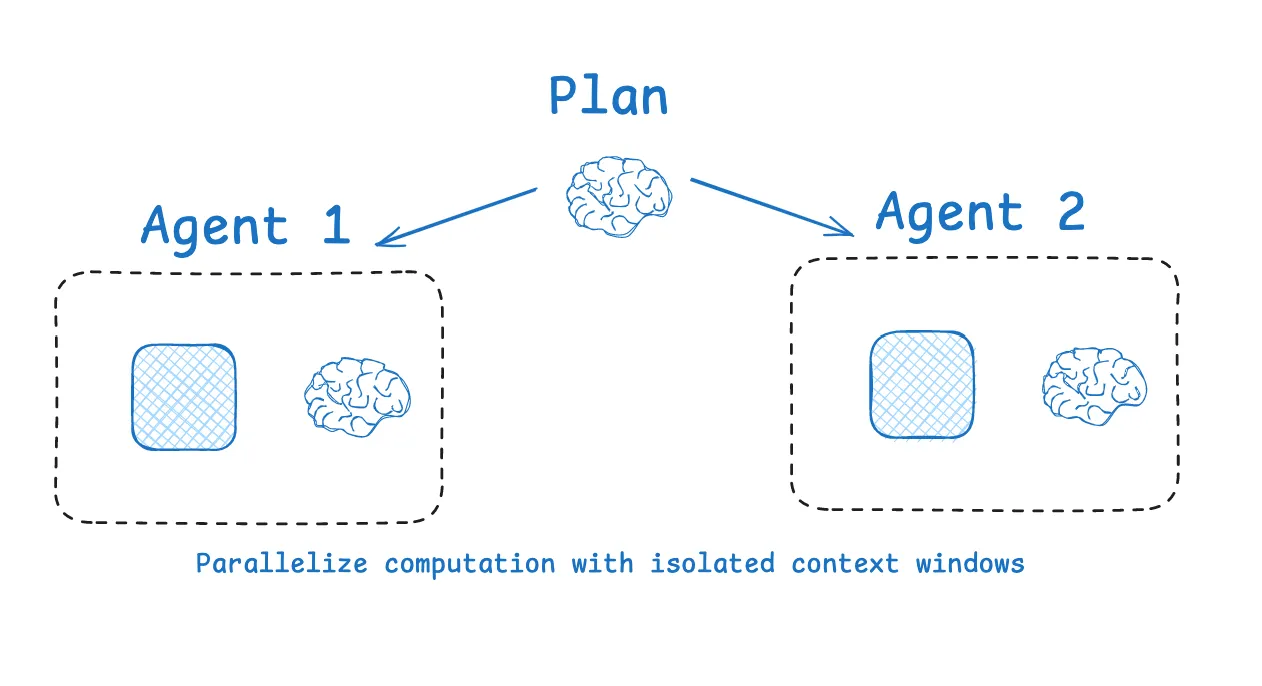
Anthropic 的多 Agent 研究系统说明了这种方式的价值:多个上下文相互隔离的 Agent 胜过单个 Agent,很大程度上是因为每个子 Agent 的上下文窗口可以专门用于范围更窄的子任务。正如其博客所说:
Anthropic’s multi-agent researcher makes a case for this: many agents with isolated contexts outperformed single-agent, largely because each subagent context window can be allocated to a more narrow sub-task. As the blog said:
[子 Agent]使用各自的上下文窗口并行运行,同时探索问题的不同方面。
[Subagents operate] in parallel with their own context windows, exploring different aspects of the question simultaneously.
Of course, the challenges with multi-agent include token use (e.g., up to 15× more tokens than chat as reported by Anthropic), the need for careful prompt engineering to plan sub-agent work, and coordination of sub-agents.
通过环境隔离上下文
Context Isolation with Environments
HuggingFace 的深度研究 Agent展示了另一种有趣的上下文隔离方式。大多数 Agent 使用工具调用 API,返回 JSON 对象作为工具参数,再将其传给工具,例如搜索 API,以获得工具反馈,例如搜索结果。HuggingFace 使用 CodeAgent,输出包含所需工具调用的代码,然后在沙箱中运行代码。最后,只将工具调用中选定的上下文,例如返回值,传回大语言模型。
HuggingFace’s deep researcher shows another interesting example of context isolation. Most agents use tool calling APIs, which return JSON objects (tool arguments) that can be passed to tools (e.g., a search API) to get tool feedback (e.g., search results). HuggingFace uses a CodeAgent, which outputs that contains the desired tool calls. The code then runs in a sandbox. Selected context (e.g., return values) from the tool calls is then passed back to the LLM.
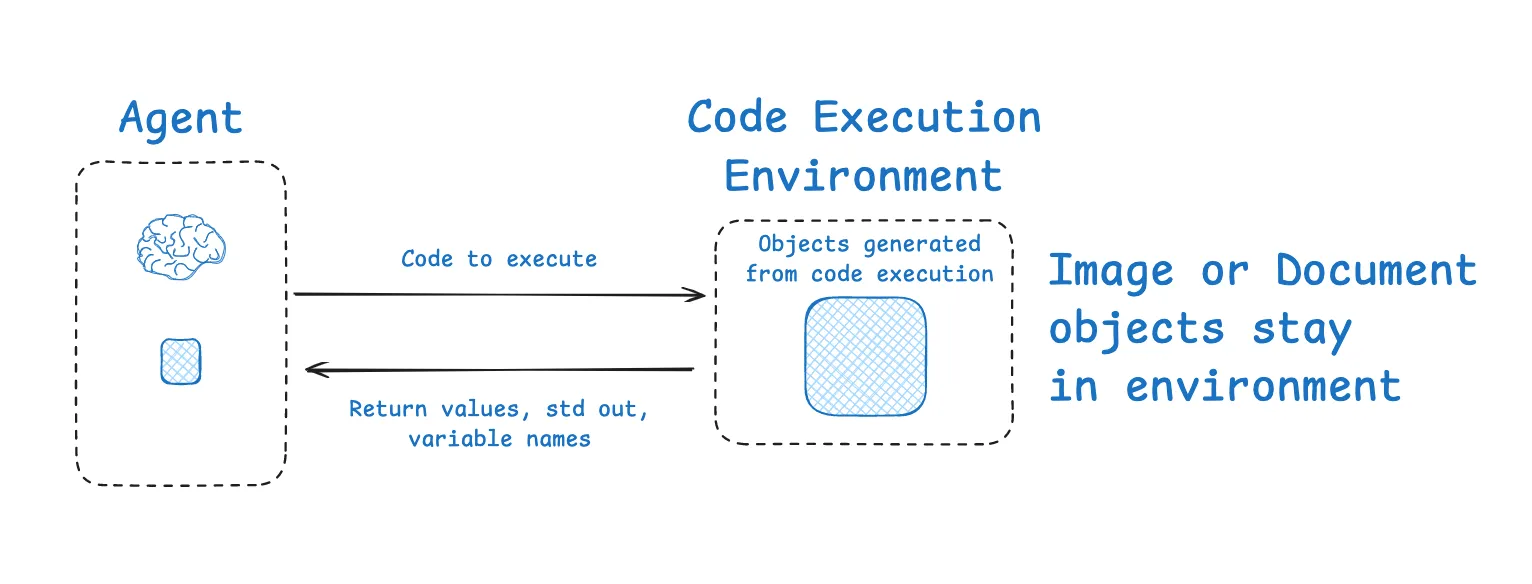
这样,上下文可以保留在环境中,与大语言模型隔离。Hugging Face 指出,这尤其适合隔离 token 占用量大的对象:
This allows context to be isolated from the LLM in the environment. Hugging Face noted that this is a great way to isolate token-heavy objects in particular:
[代码 Agent 能够]更好地处理状态……需要保存这张图片、这段音频或其他内容,以供日后使用?没问题,只需把它作为变量赋值到状态中,就可以[以后再用]。
[Code Agents allow for] a better handling of state … Need to store this image / audio / other for later use? No problem, just assign it as a variable in your state and you [use it later].
状态
State
Agent 的运行时状态对象,也是隔离上下文的好方法,可以起到与沙箱类似的作用。你可以为状态对象设计一个 schema,其中包含用于写入上下文的字段。schema 中的某个字段,例如 messages,可以在 Agent 的每一轮中提供给大语言模型;其他字段则可以将信息隔离起来,只在需要时有选择地使用。
It’s worth calling out that an agent’s runtime state object can also be a great way to isolate context. This can serve the same purpose as sandboxing. A state object can be designed with a schema that has fields that context can be written to. One field of the schema (e.g., messages) can be exposed to the LLM at each turn of the agent, but the schema can isolate information in other fields for more selective use.
使用 LangSmith 与 LangGraph 开展上下文工程
Context Engineering with LangSmith / LangGraph
那么,如何应用这些想法?开始之前,有两项有用的基础工作。首先,确保有办法查看你的数据,并跟踪整个 Agent 的 token 用量。这有助于判断最值得在哪些地方投入上下文工程。LangSmith 很适合 Agent 的执行轨迹记录与可观测性,为此提供了很好的方式。其次,确保能方便地测试上下文工程究竟损害了还是改善了 Agent 的表现。LangSmith 支持 Agent 评测,用于检验任何上下文工程工作的影响。
So, how can you apply these ideas? Before you start, there are two foundational pieces that are helpful. First, ensure that you have a way to look at your data and track token-usage across your agent. This helps inform where best to apply effort context engineering. LangSmith is well-suited for agent tracing / observability, and offers a great way to do this. Second, be sure you have a simple way to test whether context engineering hurts or improve agent performance. LangSmith enables agent evaluation to test the impact of any context engineering effort.
写入上下文
Write context
LangGraph 在设计上同时支持限定于会话的短期记忆和长期记忆。短期记忆使用检查点机制,在 Agent 的所有步骤之间持久保存 Agent 状态。它非常适合充当“草稿板”:你可以将信息写入状态,并在 Agent 执行轨迹的任意步骤取回。
LangGraph was designed with both thread-scoped (short-term) and long-term memory. Short-term memory uses checkpointing to persist agent state across all steps of an agent. This is extremely useful as a “scratchpad”, allowing you to write information to state and fetch it at any step in your agent trajectory.
LangGraph 的长期记忆让你可以在与 Agent 的多次会话之间持久保存上下文。它很灵活,既能保存少量文件,例如用户档案或规则,也能保存规模更大的记忆集合。此外,LangMem 提供了丰富而实用的抽象,帮助管理 LangGraph 记忆。
LangGraph’s long-term memory lets you to persist context across many sessions with your agent. It is flexible, allowing you to save small sets of files (e.g., a user profile or rules) or larger collections of memories. In addition, LangMem provides a broad set of useful abstractions to aid with LangGraph memory management.
选择上下文
Select context
在 LangGraph Agent 的每个节点,也就是每一步中,你都可以获取状态。因此,可以细粒度控制每一步向大语言模型提供哪些上下文。
Within each node (step) of a LangGraph agent, you can fetch state. This give you fine-grained control over what context you present to the LLM at each agent step.
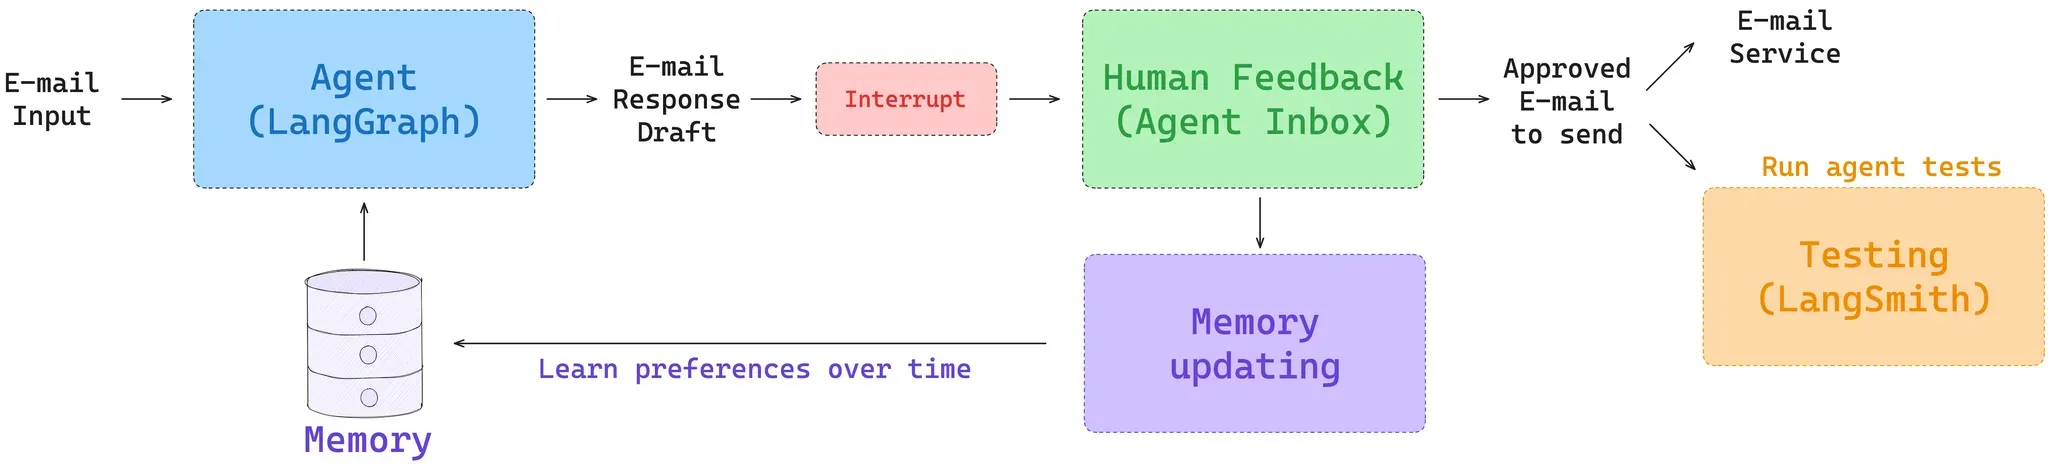
此外,每个节点都能访问 LangGraph 的长期记忆,它支持多种检索方式,例如获取文件,以及对记忆集合进行基于嵌入的检索。关于长期记忆的概览,请参阅我们在 Deeplearning.ai 的课程。如果希望从一个具体 Agent 入手学习记忆的应用,请参阅 Ambient Agents 课程。它展示了如何在一个长时间运行的 Agent 中使用 LangGraph 记忆,让 Agent 管理电子邮件,并从你的反馈中学习。
In addition, LangGraph’s long-term memory is accessible within each node and supports various types of retrieval (e.g., fetching files as well as embedding-based retrieval on a memory collection). For an overview of long-term memory, see our Deeplearning.ai course. And for an entry point to memory applied to a specific agent, see our Ambient Agents course. This shows how to use LangGraph memory in a long-running agent that can manage your email and learn from your feedback.
在工具选择方面,LangGraph Bigtool 库很适合对工具描述进行语义搜索。当工具集合很大时,这有助于选出与任务最相关的工具。最后,我们还提供了多份教程和视频,展示如何将各种 RAG 方法与 LangGraph 结合使用。
For tool selection, the LangGraph Bigtool library is a great way to apply semantic search over tool descriptions. This helps select the most relevant tools for a task when working with a large collection of tools. Finally, we have several tutorials and videos that show how to use various types of RAG with LangGraph.
压缩上下文
Compressing context
因为 LangGraph 是一个底层编排框架,你可以把 Agent 组织成一组节点,定义每个节点内部的逻辑,再定义一个在节点之间传递的状态对象。这种控制能力提供了多种压缩上下文的方式。
Because LangGraph is a low-level orchestration framework, you lay out your agent as a set of nodes, define the logic within each one, and define an state object that is passed between them. This control offers several ways to compress context.
一种常见方法,是将消息列表作为 Agent 状态,并使用一些内置工具函数,定期对其生成摘要或进行裁剪。不过,你也可以用几种不同方式加入逻辑,对 Agent 的工具调用或工作阶段进行后处理。你可以在特定位置加入摘要节点,也可以在工具调用节点中加入摘要逻辑,压缩特定工具调用的输出。
One common approach is to use a message list as your agent state and summarize or trim it periodically using a few built-in utilities. However, you can also add logic to post-process tool calls or work phases of your agent in a few different ways. You can add summarization nodes at specific points or also add summarization logic to your tool calling node in order to compress the output of specific tool calls.
隔离上下文
Isolating context
LangGraph 围绕状态对象设计,允许你指定状态 schema,并在 Agent 的每一步访问状态。例如,可以把工具调用产生的上下文存入状态中的某些字段,在需要这些上下文之前,始终将其与大语言模型隔离。除了状态,LangGraph 也支持使用沙箱隔离上下文。这个代码仓库展示了一个使用 E2B 沙箱执行工具调用的 LangGraph Agent。这个视频则展示了使用 Pyodide 进行沙箱隔离并持久保存状态的例子。LangGraph 也为多 Agent 架构提供了大量支持,例如 supervisor 和 swarm 库。关于在 LangGraph 中使用多 Agent 的更多细节,可以观看这个、这个和这个视频。
LangGraph is designed around a state object, allowing you to specify a state schema and access state at each agent step. For example, you can store context from tool calls in certain fields in state, isolating them from the LLM until that context is required. In addition to state, LangGraph supports use of sandboxes for context isolation. See this repo for an example LangGraph agent that uses an E2B sandbox for tool calls. See this video for an example of sandboxing using Pyodide where state can be persisted. LangGraph also has a lot of support for building multi-agent architecture, such as the supervisor and swarm libraries. You can see these videos for more detail on using multi-agent with LangGraph.
结语
Conclusion
上下文工程正在成为 Agent 开发者应当努力掌握的一门技艺。本文介绍了当前许多流行 Agent 中常见的几种模式:
Context engineering is becoming a craft that agents builders should aim to master. Here, we covered a few common patterns seen across many popular agents today:
- 写入上下文:将信息保存在上下文窗口之外,帮助 Agent 执行任务。
- 选择上下文:将信息取入上下文窗口,帮助 Agent 执行任务。
- 压缩上下文:仅保留执行任务所需的 token。
- 隔离上下文:将上下文拆开,帮助 Agent 执行任务。
- Writing context - saving it outside the context window to help an agent perform a task.
- Selecting context - pulling it into the context window to help an agent perform a task.
- Compressing context - retaining only the tokens required to perform a task.
- Isolating context - splitting it up to help an agent perform a task.
LangGraph 让这些模式都容易实现,LangSmith 则提供了便捷的 Agent 测试与上下文用量跟踪方式。LangGraph 与 LangGraph 共同形成了一个良性的反馈循环:找出最值得应用上下文工程的地方,实施、测试,然后重复这一过程。
LangGraph makes it easy to implement each of them and LangSmith provides an easy way to test your agent and track context usage. Together, LangGraph and LangGraph enable a virtuous feedback loop for identifying the best opportunity to apply context engineering, implementing it, testing it, and repeating.
— 全文完 —
原文来自 LangChain,中文为非官方学习译文。
查看原始出处 ↗