我们构建 Cursor Agent 运行框架的方式,与打造任何有雄心的软件产品相同。许多工作由愿景驱动:我们首先对理想的 Agent 体验应当是什么样,形成自己的判断。
We approach building the Cursor agent harness the way we'd approach any ambitious software product. Much of the work is vision-driven, where we start with an opinion about what the ideal agent experience should look like.
然后,我们针对如何接近这一愿景提出假设,通过实验检验,再结合评测和真实使用中的定量、定性信号不断迭代。这一过程依赖恰当的线上与离线观测机制,让我们判断一次改动是否确实改善了运行框架。
From there, we form hypotheses about how to get closer to that vision, run experiments to test them, and iterate using quantitative and qualitative signals from evals and real usage. That process depends on having the right online and offline instrumentation, so we can tell when a change actually makes the harness better.
当我们提前获得新模型的访问权限时,这些方法就会汇聚在一起。我们会花数周时间,针对模型的优势和特有行为定制运行框架,直到同一个模型在专门调优后的框架中,表现得明显更快、更聪明,也更高效。
When we get early access to new models, all of these approaches converge. We spend weeks customizing our harness to a model's strengths and quirks until the same model inside our specially tuned harness is noticeably faster, smarter, and more efficient.
偶尔,我们会发现带来跨越式提升的改进。但更多时候,改善运行框架需要近乎执着地积累细小优化,让它们共同提高 Agent 构建软件的能力。
Occasionally we discover step-change improvements. More often, though, improving the harness is a matter of obsessively stacking small optimizations that together make agents better at building software.
上下文窗口的演进
Evolving the context window
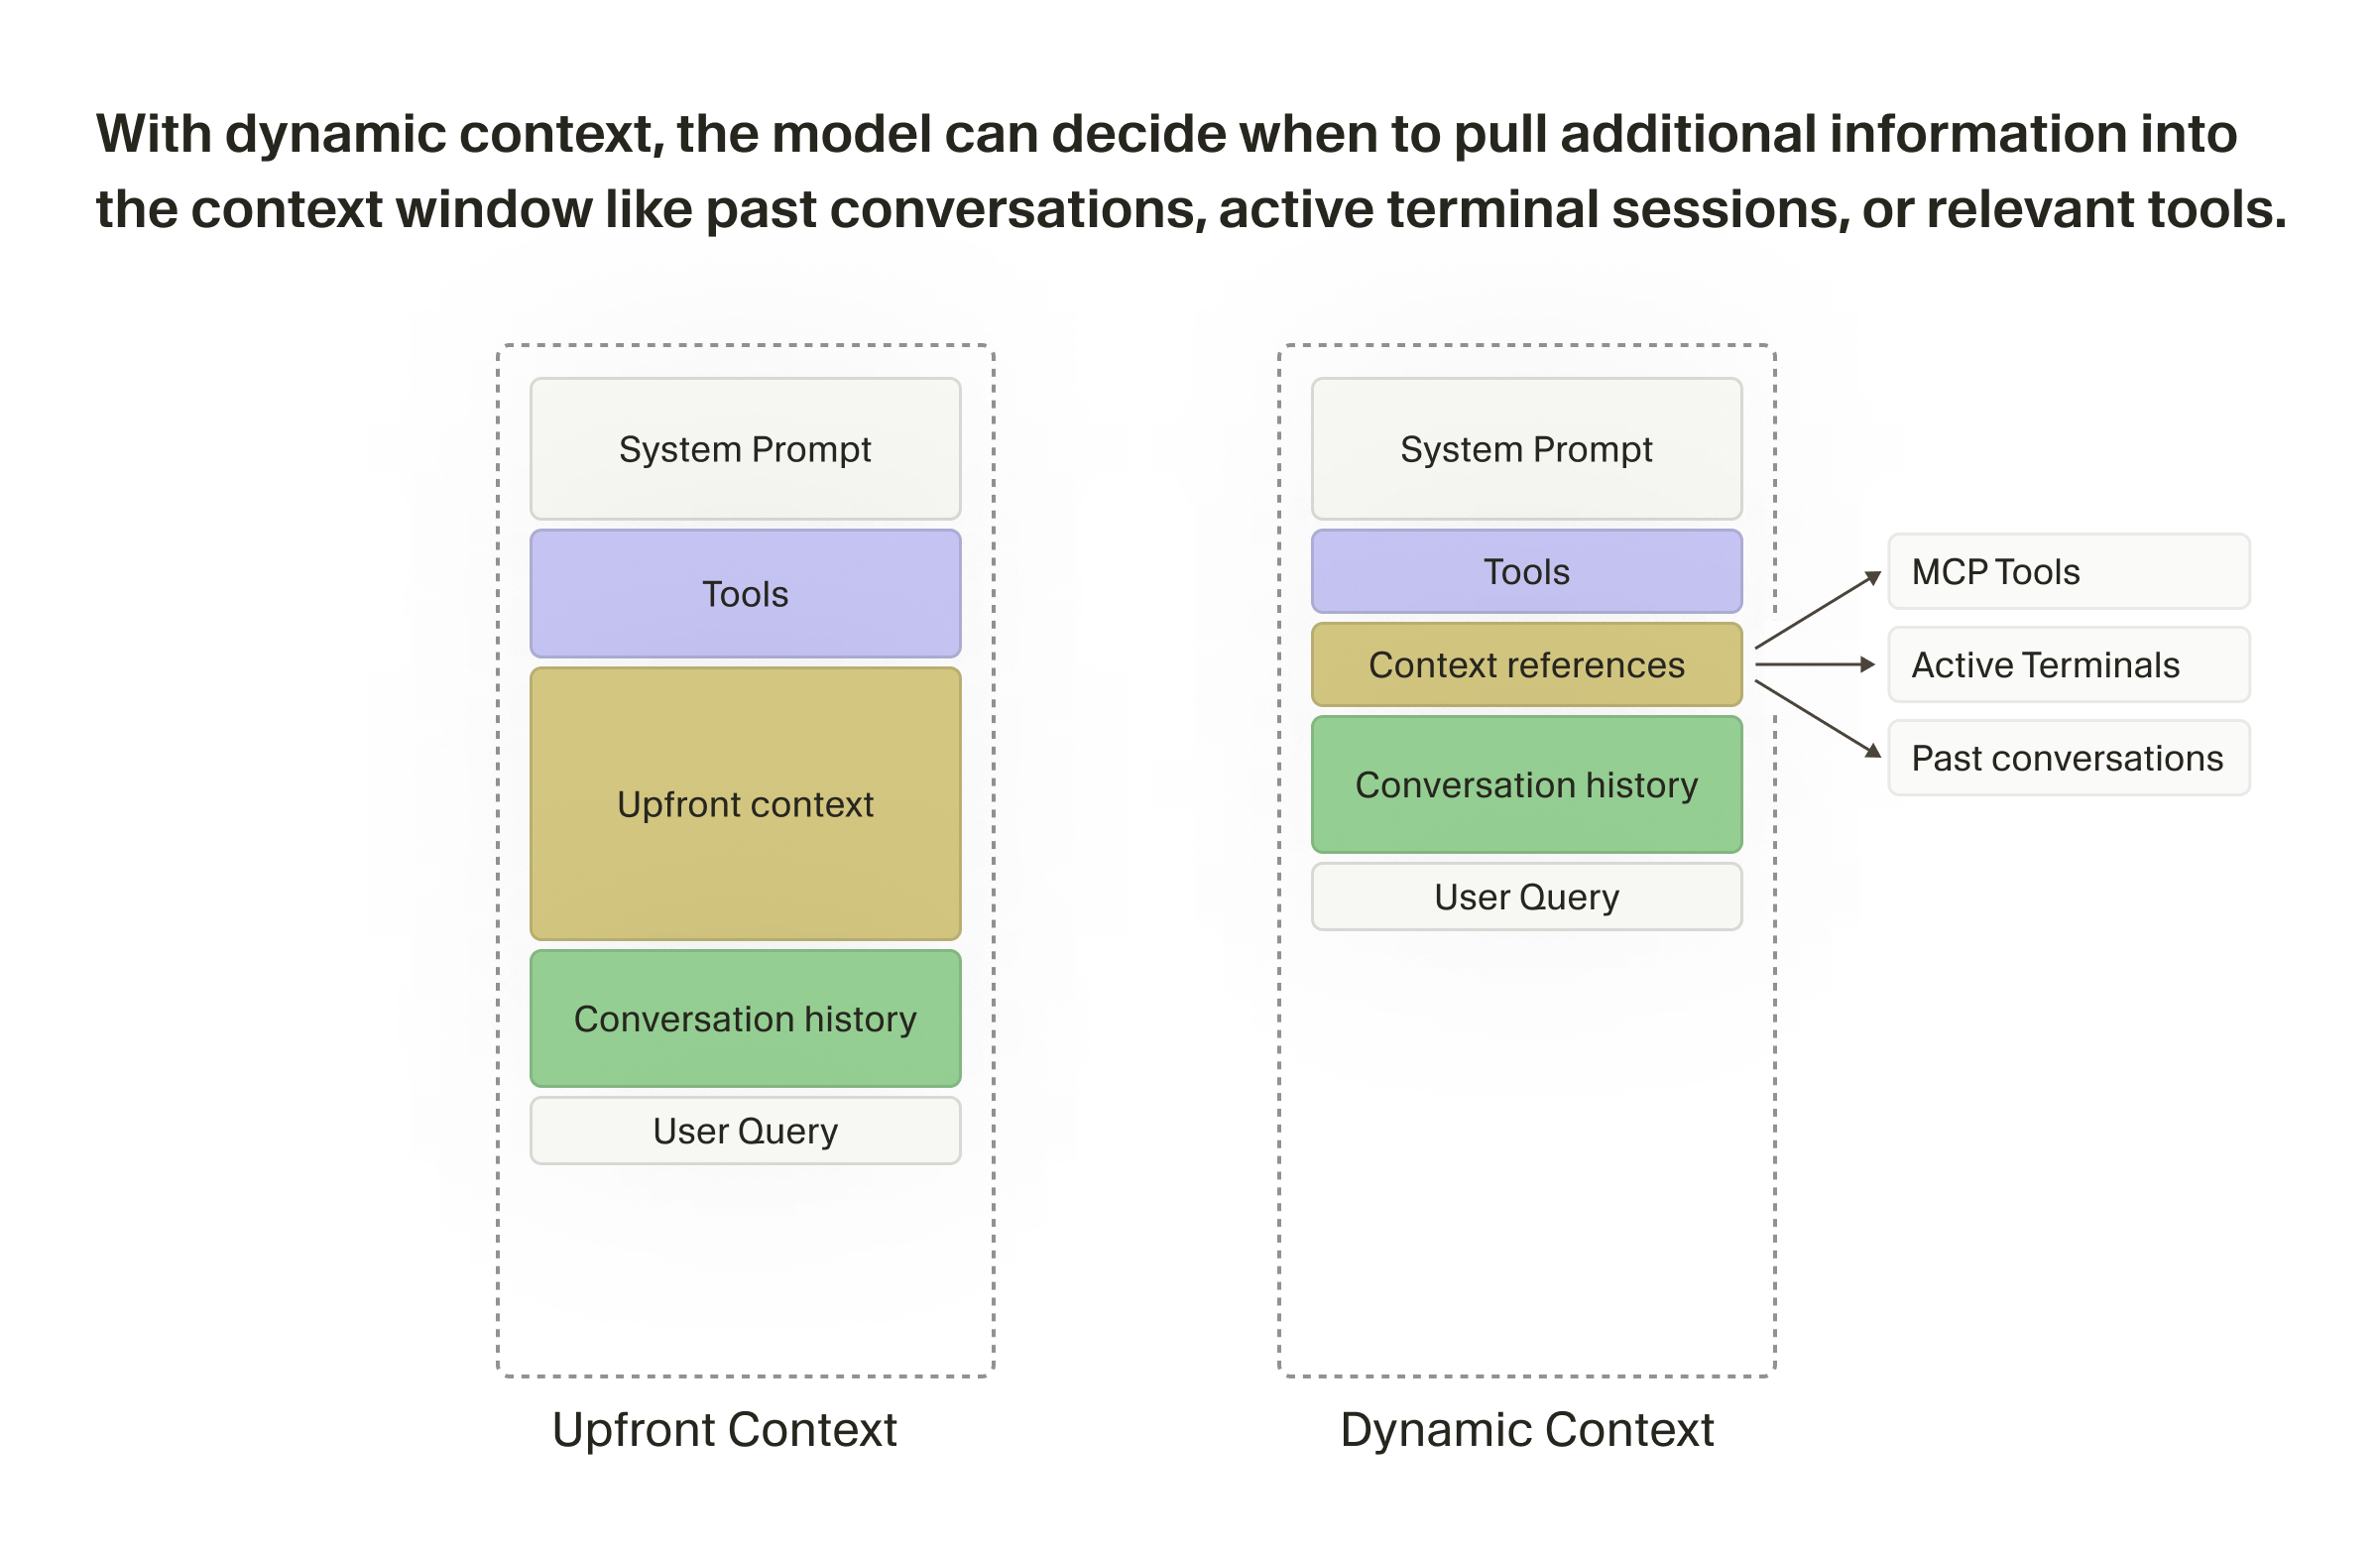
与大语言模型交互的核心,是上下文窗口。当你要求 Agent 构建某个东西时,上下文窗口先放入系统提示词和工具描述,然后是当前对话状态,最后是用户请求。
At the heart of interacting with large language models is the context window. When asking the agent to build something, the context window starts with the system prompt and tool descriptions, followed by the current state of the conversation, and finally the user's request.
在 Cursor 的发展过程中,我们填充和管理这个窗口的方式已经发生了很大变化。
The way we populate and manage that window has evolved significantly over the history of Cursor.
2024 年底,我们最初开发编程 Agent时,模型自行选择上下文的能力要差得多。因此,我们投入了大量上下文工程工作来构建护栏:例如,每次编辑后向 Agent 展示 lint 和类型错误;当它请求读取的行数太少时,改写其文件读取操作;甚至限制它一轮最多能调用多少个工具。
When we first developed our coding agent in late 2024, models were much worse at choosing their own context and we invested lots of context engineering work into creating guardrails—for example, surfacing lint and type errors to the agent after every edit, rewriting its file reads when it requested too few lines, and even limiting the maximum number of tools it could call in one turn.
我们还提供了大量静态上下文,确保 Agent 在每次会话开始时始终能够使用。在不同阶段,这些内容包括代码库的文件夹结构、与查询语义匹配的代码片段,以及用户手动附加文件的压缩版本。
We also provided substantial amounts of static context that was always available to the agent at the start of each session. At various points, that included the folder layout of the codebase, code snippets that semantically matched the query, and compressed versions of files that the user manually attached.
这些做法大多早已退出历史舞台。
That is mostly long gone.
我们仍然保留一些有用的静态上下文,例如操作系统、git 状态、当前及最近查看的文件。但随着模型能力增强,我们移除了许多护栏,并提供更多可由 Agent 在工作时自行获取的动态上下文。此前一篇文章曾深入介绍我们动态上下文背后的一些技术,其中许多后来也被其他编程 Agent 采用。现在,我们的大量工作都围绕着为 Agent 提供更多动态获取上下文、与外部世界交互的方式。
We still include some useful static context (e.g., operating system, git status, current and recently viewed files). But we’ve adapted to increasing model capability by knocking down guardrails and providing more dynamic context, which can be fetched by the agent while it works. In an earlier post, we did a deep dive into some of our techniques behind dynamic context, many of which have since been adopted by other coding agents. Much of our work now focuses on providing more ways for the agent to dynamically pull context and interact with the world.
评估运行框架改动的两种方式
Two ways of assessing harness changes
运行框架与模型共同决定 Agent 有多好,但“好”很难准确定义。为此,我们建立了多个层次的衡量机制。
The harness and the model together determine how good the agent is, but "good" is hard to pin down. To locate it, we've built several layers of measurement.
我们同时维护公开基准和自己的评测套件 CursorBench,让我们能够快速、标准化地了解质量,并比较不同时间的表现。但即便最好的基准,也只是对真实使用的近似;如果完全依赖它们,就会错过重要信号。
We maintain public benchmarks alongside our own eval suite, CursorBench, which gives us a fast, standardized read on quality and lets us compare across time. But even the best benchmarks only approximate real usage, meaning we’d miss important signals if we relied on them entirely.
因此,我们也开展线上实验,同时部署两个或更多运行框架变体,在真实使用中进行 A/B 测试。我们通过多种指标衡量这些测试中的 Agent 质量。一些指标比较直接,例如延迟、token 效率、工具调用次数和缓存命中率。它们能提供方向性参考,但仍无法回答更模糊、也更重要的问题:Agent 究竟有没有把工作做好。对此,我们采用两种衡量方式。
So we also run online experiments where we deploy two or more harness variants side by side and A/B test them on real usage. We measure agent quality in these tests through a variety of metrics. Some are straightforward like latency, token efficiency, tool call count, and cache hit rate. Those are directionally useful but still don’t get at fuzzier and more important questions of whether the agent actually did a good job. We measure those in two ways.
第一种是 Agent 生成代码的“保留率”(Keep Rate)。对于 Agent 提出的一组代码改动,我们跟踪在若干固定时间间隔之后,还有多大比例留在用户的代码库中。这让我们了解用户何时需要手动调整 Agent 的输出,或需要继续迭代,让 Agent 修复问题;这些情况表明 Agent 的初始回答质量较低。
The first is the “Keep Rate” of agent-generated code. For a given set of code changes that the agent proposed, we track what fraction of those remain in the user’s codebase after fixed intervals of time. This allows us to understand when users have to manually adjust the agent's output, or need to iterate and have the agent fix things, indicating the agent’s initial response was of lower quality.
第二种是使用语言模型读取用户对 Agent 初次输出的回应,从语义上判断用户是否满意。用户继续推进下一个功能,是 Agent 完成了工作的强烈信号;而用户粘贴堆栈跟踪,则可靠地表明它没有完成好。
Second, we use a language model to read the user's responses to the agent’s initial output in order to capture semantically whether the user was satisfied or not. A user moving on to the next feature is a strong signal the agent did its job, while a user pasting a stack trace is a reliable signal that it didn't.
有时,这些线上测试会让我们搁置看似有希望的想法。在一项实验中,我们尝试用更昂贵的模型总结上下文,却发现它对 Agent 质量的改善微乎其微,不值得承担更高成本。
Sometimes these online tests tell us to shelve an idea that seems promising. In one experiment, we tried a more expensive model for context summarization and observed it made a negligible difference in agent quality that wasn’t worth the higher cost.
跟踪并修复能力退化
Tracking and repairing degradations
随着我们加入更多模型与能力,运行框架会像任何软件一样,变得更加复杂,可能出现的状态也更多。这带来了更大的缺陷发生空间,其中许多问题只有在大规模使用时才能发现。
As we add more models and capabilities, the harness gets more complex with more potential states, just like any piece of software. With this comes more surface area for bugs to crop up, many of which we can only detect at scale.
Agent 的工具是最容易出现各种缺陷的部分之一,而工具调用错误可能对 Cursor 中的一个会话造成严重影响。虽然 Agent 往往能够自行纠正,但错误仍会留在上下文中,浪费 token,并造成“上下文腐化”:累积的错误会降低模型后续决策的质量。
The agent’s tools are one of the broadest surfaces for bugs, and tool call errors can be extremely harmful to a session in Cursor. While the agent can often self-correct, errors remain in context, wasting tokens and causing “context rot,” where accumulated mistakes degrade the quality of the model's subsequent decisions.
有时,一次工具调用失败,就可能让 Agent 陷入阻塞或彻底偏离方向。工具调用量、错误率等指标虽然无法直接衡量 Agent 是否做好了工作,却可以充当指示信号,揭示更广泛的问题。
Sometimes, the agent can be blocked or go off the rails completely after a failed tool call. Though metrics like tool call volume and error rate don’t directly measure whether the agent did a good job, they act as indicators that can point to a broader issue.
任何未知错误都代表运行框架中的缺陷,我们会据此处理。但许多错误是“预期内”的,例如模型偶尔提出不正确的编辑,或尝试读取不存在的文件。我们按原因对这些预期错误分类。InvalidArguments 和 UnexpectedEnvironment 对应模型失误和上下文窗口中的矛盾;ProviderError 则对应 GenerateImage、WebSearch 等工具的服务商故障。
Any unknown error represents a bug in the harness, and we treat it accordingly. But many errors are “expected,” for example the model occasionally proposing an incorrect edit or trying to read a file that doesn't exist. We classify these expected errors by cause. InvalidArguments and UnexpectedEnvironment capture model mistakes and contradictions in the context window, while ProviderError captures vendor outages from tools like GenerateImage or WebSearch.
我们还有 UserAborted、Timeout 等其他分类,它们共同覆盖了大多数预期错误。
We have several other classifications like UserAborted and Timeout which altogether encompass most expected errors.
我们基于这些指标定义告警,以发现已经进入生产环境的严重回归问题。由于未知错误一定是缺陷,只要任何工具的未知错误率超过固定阈值,我们就会告警。但要判断预期错误究竟是运行框架中的缺陷,还是正常的预期行为,则可能很棘手。
We define alerts based on these metrics to catch significant regressions that make it into production. Since unknown errors are always bugs, we alert whenever the unknown error rate for any tool exceeds a fixed threshold. But it can be tricky to tell whether expected errors represent a bug in the harness or expected behavior.
例如,grep 搜索超时可能是工具的性能问题,也可能只是代码库特别大,而模型构造了一个低效查询。为应对这一点,我们设置了异常检测告警,当预期错误显著超过基线时触发。我们按工具、按模型分别计算基线,因为不同模型在工具调用上犯错的频率可能不同。
For example, a grep search timeout might be because of a performance issue with the tool, or the codebase might just be huge and the model formed an inefficient query. To deal with this, we have anomaly detection alerts which fire when expected errors significantly exceed the baseline. We compute baselines per-tool and per-model, because different models may mess up tool calls at different rates.
我们还每周运行一次自动化任务,为其配备一项技能,教模型如何搜索我们的日志,发现新出现或近期激增的问题,并根据调查结果在待办列表中创建或更新工单。我们大量依赖云端 Agent 同时启动多个问题的修复工作,甚至可以直接从 Linear 触发它们。
We also run a weekly Automation equipped with a skill that teaches the model how to search through our logs, surface issues that are new or recently spiked, and create or update tickets in a backlog with an investigation. We lean heavily on Cloud Agents to kick off fixes for many issues at once, and can even trigger them directly from Linear.
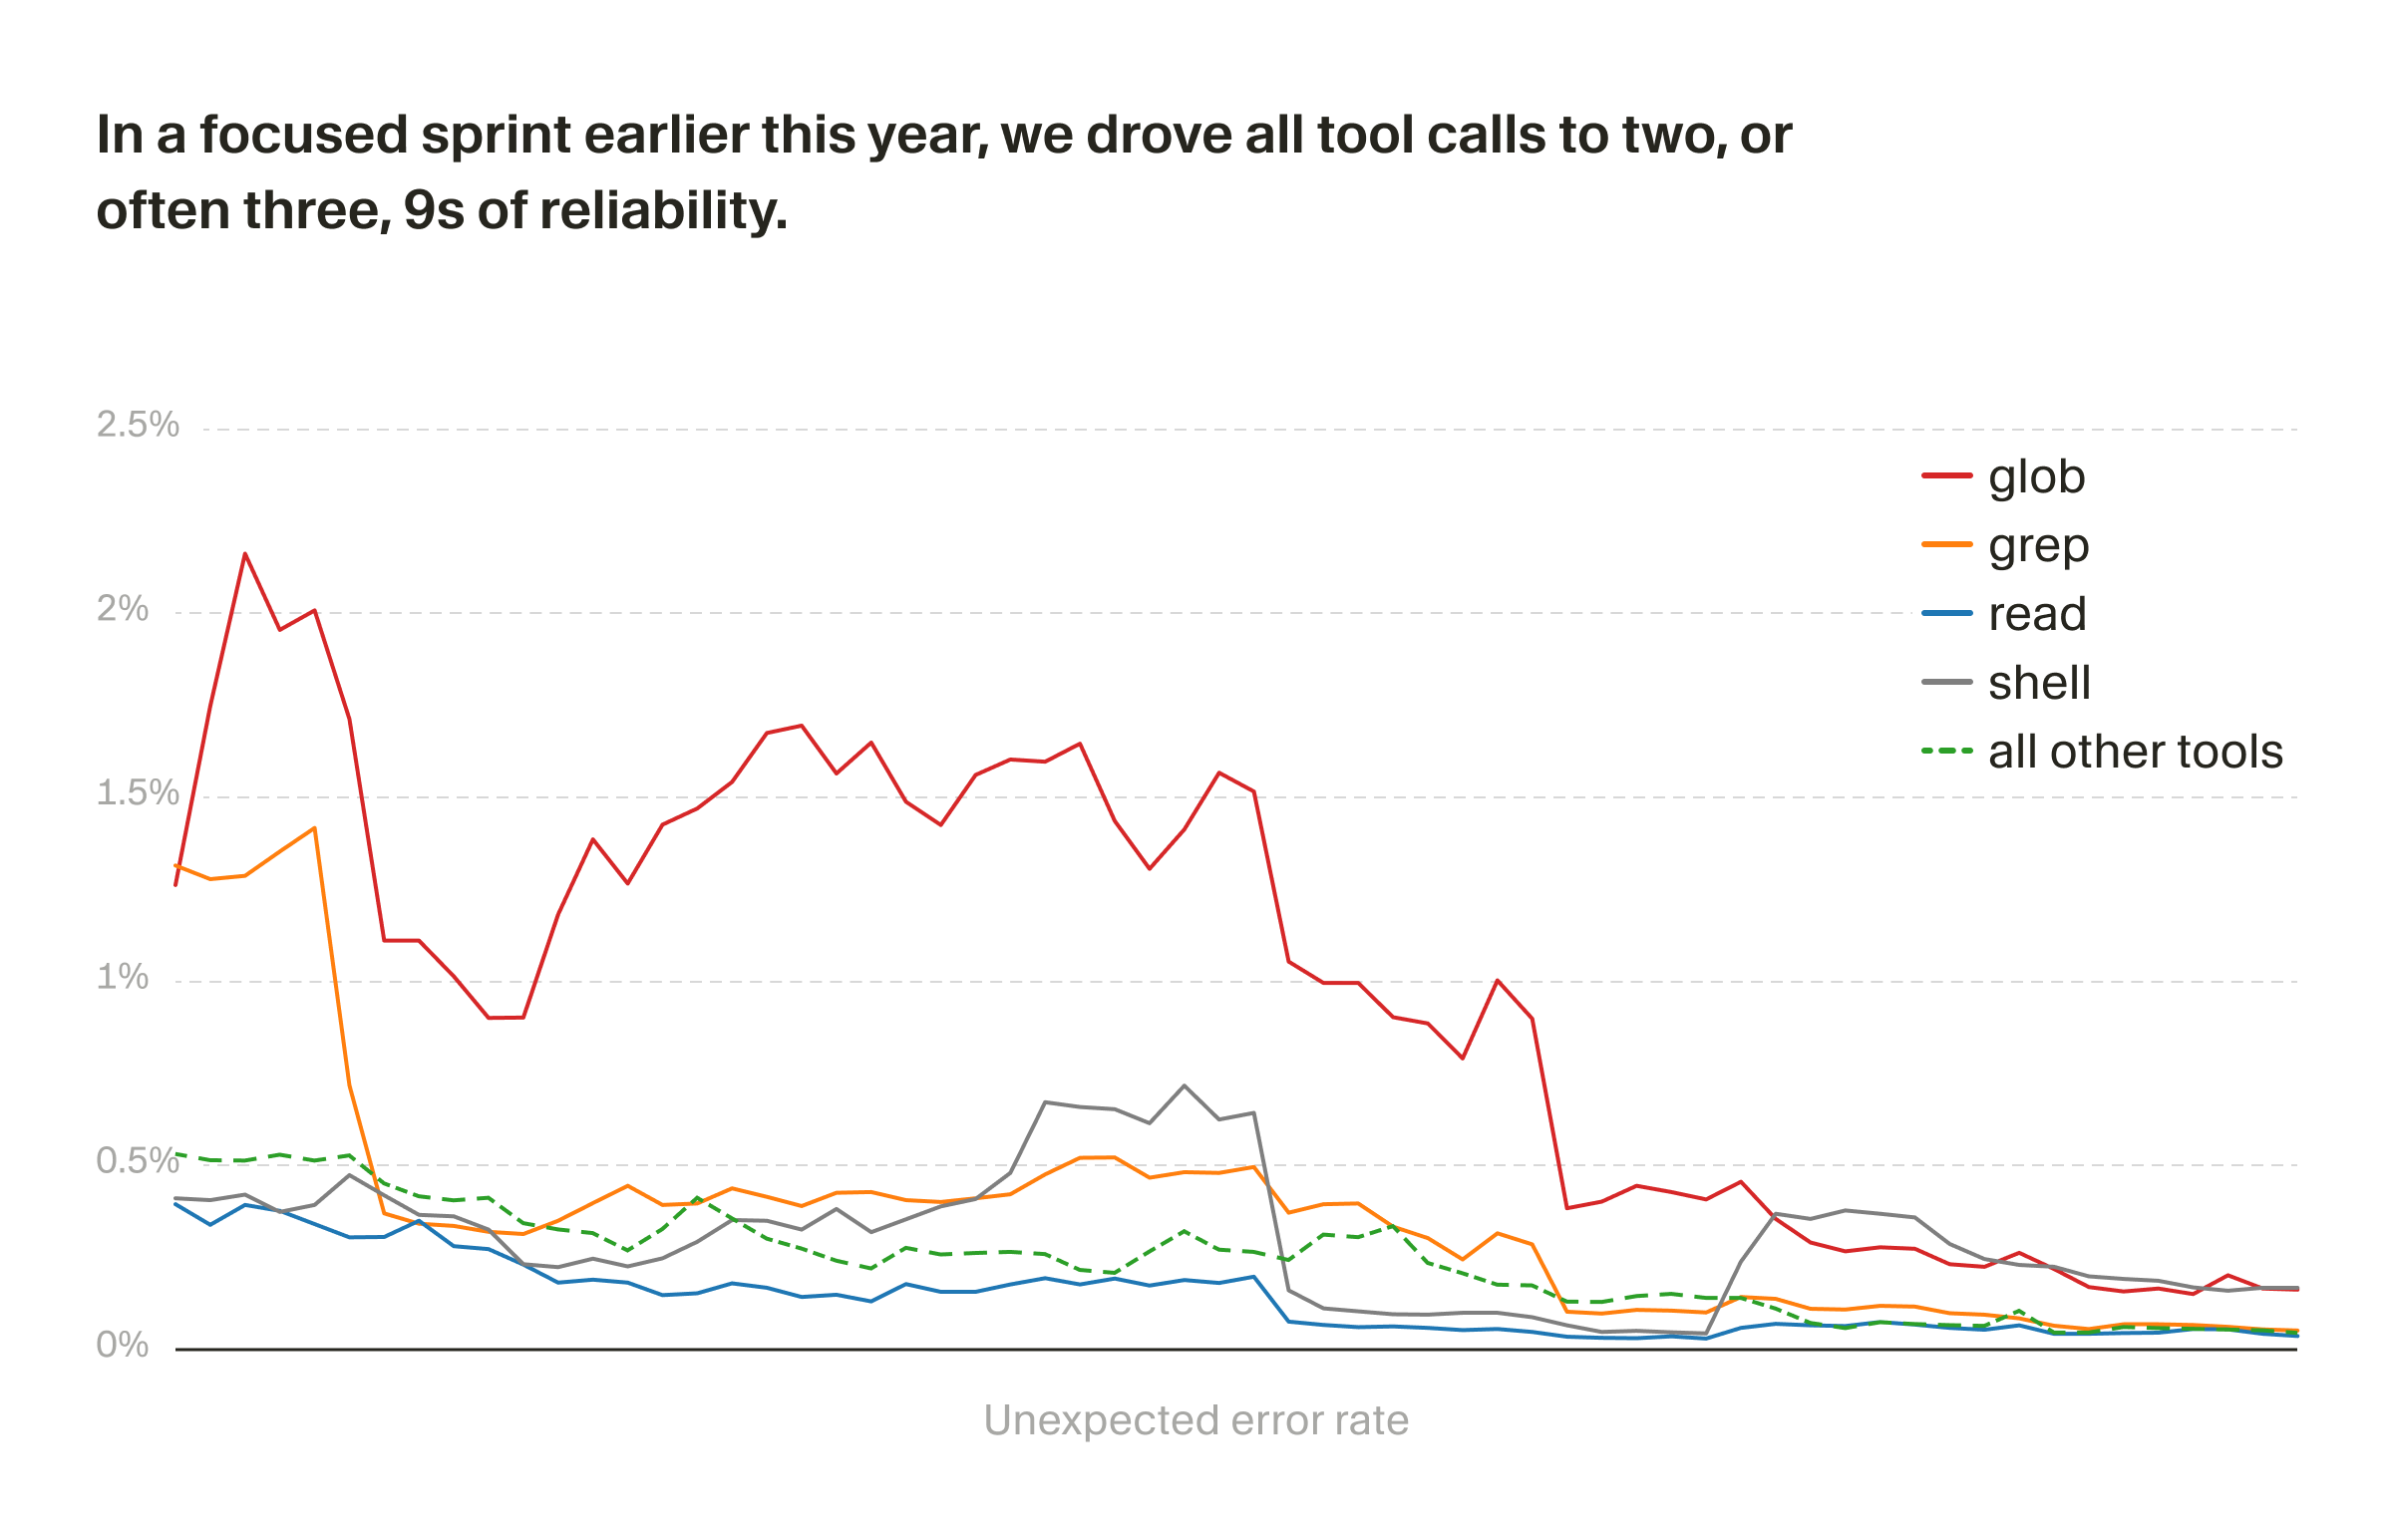
这一流程,是我们为 Agent 运行框架打造自动化“软件工厂”的一部分。在今年早些时候的一轮集中迭代中,我们将非预期工具调用错误降低了一个数量级。
This process is part of the way we’re instantiating an automated “software factory” for our agent harness. Over the course of a focused sprint earlier this year, we drove unexpected tool call errors down by an order of magnitude.
为不同模型定制运行框架
Customizing the harness for different models
我们的全部运行框架抽象都与具体模型无关,并且可以针对每个支持的模型深度定制。例如,OpenAI 模型训练时使用基于补丁的格式编辑文件,而 Anthropic 模型训练时使用字符串替换。两种模型都能使用任一种工具,但给它不熟悉的那一种,会消耗额外推理 token,也会产生更多错误。因此,我们在框架中为每个模型提供它训练时使用的工具格式。
All of our harness abstractions are model agnostic and can be heavily customized for every model we support. For instance, OpenAI's models are trained to edit files using a patch-based format, while Anthropic's models are trained on string replacement. Either model could use either tool, but giving it the unfamiliar one costs extra reasoning tokens and produces more mistakes. So in our harness, we provision each model with the tool format it had during training.
这种定制深入到很多层面,包括为不同服务商、甚至不同模型版本编写专门的提示词。OpenAI 模型在遵循指令时往往更按字面理解、更精确;Claude 则更依赖直觉,对不够精确的指令也更宽容。
This customization goes very deep, and includes custom prompting for different providers and even for different model versions. OpenAI’s models tend to be more literal and precise in their instruction following, whereas Claude is a bit more intuitive and more tolerant to imprecise instructions.
如果我们在新模型发布前提前获得访问权限,就从现有模型中最接近它的运行框架开始迭代。我们运行离线评测,找出模型在哪些地方感到困惑,让团队成员实际使用并暴露问题,再作相应调整。我们不断重复这一过程,直到模型与框架的组合达到我们愿意发布的水平。
When we get early access to a new model ahead of launch, we start from the closest existing model's harness and begin iterating. We run offline evals to find where the model gets confused, have people on our team use it and surface problems, and tweak the harness in response. We iterate like this until we have a model-harness combination we feel good about shipping.
这个调优过程大多是在为新模型的优势定制框架,但有时我们也会碰到模型特有的异常行为,可以通过框架加以缓解。例如,我们观察到某个模型出现了后来被我们称为“上下文焦虑”的行为:随着上下文窗口逐渐填满,它开始拒绝工作,推托说任务似乎太大。我们通过调整提示词减少了这种行为。
Much of this tuning process is about customizing the harness to a new model’s strengths, but sometimes we encounter genuine model quirks that we can mitigate with the harness. For example, we observed one model develop what we came to call context anxiety: As its context window filled up, it would start refusing work, hedging that the task seemed too big. We were able to reduce the behavior through prompt adjustments.
支持对话中途切换模型
Facilitating mid-chat model switching
设计运行框架来支持用户在对话中途切换模型,尤其棘手,因为不同模型具有不同的行为、提示词和工具形式。
It’s especially tricky to design the harness to support users switching models mid conversation, because different models have different behaviors, prompts, and tool shapes.
用户切换模型时,Cursor 会自动切换到相应运行框架,使用为该模型定制的提示词和工具。然而,模型仍然必须将这些工具用于另一模型生成的对话历史;相对于它的训练数据,这些历史属于分布外输入。
When a user switches models, Cursor automatically switches to the appropriate harness, with that model’s customized set of prompts and tools. However, the model still has to apply those tools to a conversation history that was produced by a different model and is out of distribution from what it was trained on.
为解决这一点,我们加入了专门指令,告诉模型它何时正在对话中途接替另一个模型。这些指令也会引导它避免调用对话历史中出现、却不属于自身工具集的工具。
To address this, we add custom instructions that tell the model when it's taking over mid-chat from another model. These instructions also steer it away from calling tools that appear in the conversation history but aren't part of its own tool set.
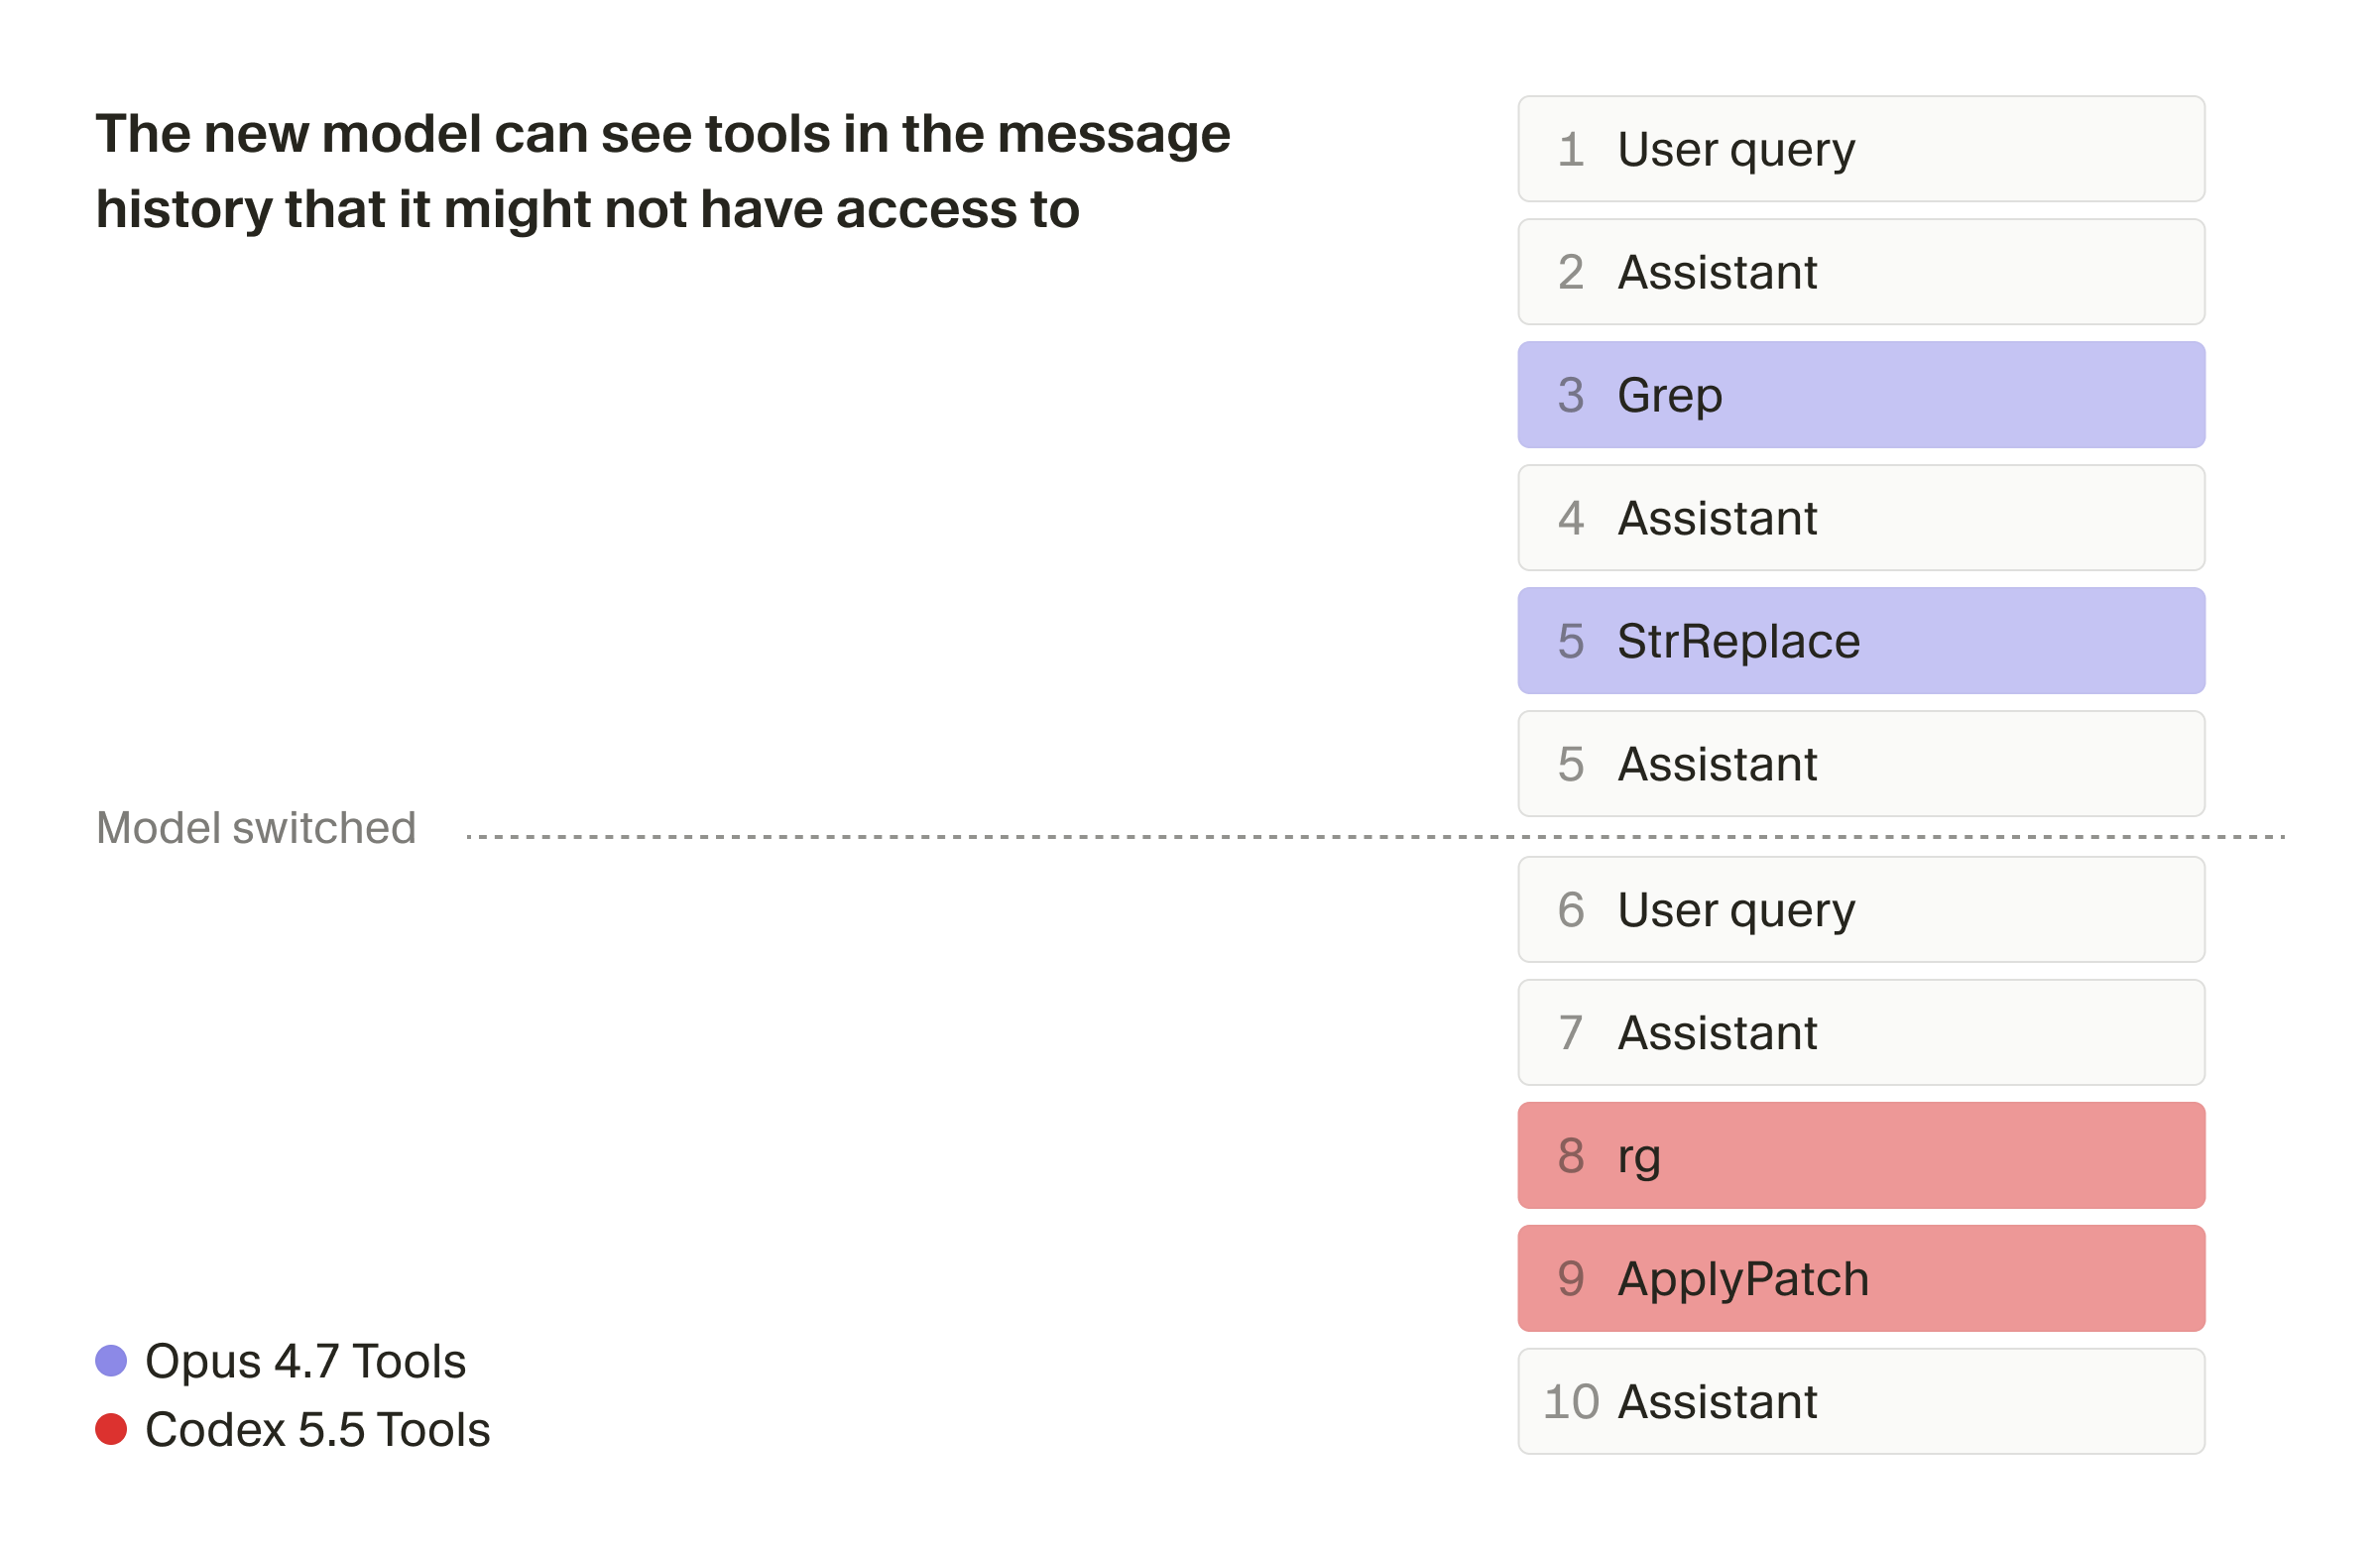
第二个挑战是缓存与具体服务商、具体模型绑定,因此切换模型意味着缓存未命中,切换后的第一轮也会更慢、更昂贵。我们曾尝试在切换时总结对话,向模型提供一份简洁摘要,以减轻缓存未命中的代价。但如果用户已经深入一个复杂任务,摘要可能丢失重要细节。除非有理由切换,否则我们通常建议在同一段对话中始终使用同一个模型。
A second challenge is that caches are provider- and model-specific, so switching means a cache miss and a slower, more expensive first turn. We have experimented with mitigating this by summarizing the conversation at switch time, which provides the model with a clean summary that reduces the cache penalty. But if the user is deep into a complex task, the summary can lose important details. We generally recommend staying with one model for the duration of a conversation unless you have a reason to switch.
另一种避开对话中途切换模型难题的方式,是使用从全新上下文窗口开始的子 Agent。最近,我们为运行框架增加了一项能力:用户可以直接要求使用特定模型运行某个子 Agent。
Another way to sidestep the challenges of mid-conversation model switching is to instead use a subagent, which starts from a fresh context window. We recently added to the harness the ability for users to directly ask for a subagent to be run with a particular model.
运行框架与软件开发的未来
The harness and the future of software development
AI 辅助软件工程的未来将是多 Agent 的。系统不会把每个子任务都交给同一个 Agent,而是会学习如何在专门的 Agent 与子 Agent 之间委派工作:一个负责规划,一个负责快速编辑,另一个负责调试,各自在最擅长的范围内工作。
The future of AI-assisted software engineering will be multi-agent. Instead of running every subtask through a single agent, the system will learn to delegate across specialized agents and subagents: one for planning, another for fast edits, and a third for debugging, each scoped to what it does best.
要让这一切良好运转,根本上是运行框架的挑战。系统需要知道派出哪个 Agent,如何针对它的优势描述任务,以及如何将结果串成连贯的工作流。编排这种协作的能力,将存在于运行框架中,而不是任何单个 Agent 内部。这意味着,虽然运行框架工程一直是 Agent 成功的重要条件,但未来它只会更加关键。
Making that work well is fundamentally a harness challenge. The system needs to know which agent to dispatch, how to frame the task for that agent's strengths, and how to stitch the results into a coherent workflow. The ability to orchestrate that kind of coordination will live in the harness rather than any single agent. This means that, while harness engineering has always been important for agent success, it's only going to be more critical going forward.
— 全文完 —
原文来自 Cursor,中文为非官方学习译文。
查看原始出处 ↗