运行框架(harness)中包含着一些假设,而随着模型能力提升,这些假设会过时。Managed Agents 是我们用于长程 Agent 任务的托管服务,它围绕一组接口构建;即使运行框架不断变化,这些接口也能保持稳定。
Harnesses encode assumptions that go stale as models improve. Managed Agents—our hosted service for long-horizon agent work—is built around interfaces that stay stable as harnesses change.
请按照我们的文档,开始使用 Claude Managed Agents。
如何构建有效的 Agent,以及如何为长时间运行的任务设计运行框架,一直是本工程博客持续探讨的话题。这些工作有一个共同点:运行框架中包含着对 Claude 无法独立完成哪些事情的假设。然而,我们需要经常重新审视这些假设,因为随着模型能力提升,它们可能会过时。
Get started with Claude Managed Agents by following our docs.
A running topic on the Engineering Blog is how to build effective agents and design harnesses for long-running work. A common thread across this work is that harnesses encode assumptions about what Claude can’t do on its own. However, those assumptions need to be frequently questioned because they can go stale as models improve.
举一个例子:在此前的工作中,我们发现,当 Claude Sonnet 4.5 察觉自己正在接近上下文上限时,会过早地结束任务——这种行为有时被称为“上下文焦虑”。我们通过在运行框架中加入上下文重置机制来解决这个问题。但当我们将同一运行框架用于 Claude Opus 4.5 时,却发现这种行为已经消失。重置机制成了多余的负担。
As just one example, in prior work we found that Claude Sonnet 4.5 would wrap up tasks prematurely as it sensed its context limit approaching—a behavior sometimes called “context anxiety.” We addressed this by adding context resets to the harness. But when we used the same harness on Claude Opus 4.5, we found that the behavior was gone. The resets had become dead weight.
我们预计运行框架会继续演进。因此,我们构建了 Managed Agents:这是 Claude Platform 中的一项托管服务,通过一小组接口代你运行长程 Agent。我们希望这些接口能够比任何一种具体实现都更长久,包括我们今天正在运行的实现。
We expect harnesses to continue evolving. So we built Managed Agents: a hosted service in the Claude Platform that runs long-horizon agents on your behalf through a small set of interfaces meant to outlast any particular implementation—including the ones we run today.
构建 Managed Agents 意味着要解决计算领域的一个老问题:如何为“尚未被构想出来的程序”设计系统。几十年前,操作系统通过将硬件虚拟化为足够通用的抽象——进程、文件——解决了这一问题,使之能够适用于当时尚不存在的程序。这些抽象的寿命比硬件更长。read() 命令不关心自己访问的是 20 世纪 70 年代的磁盘组,还是现代 SSD。上层抽象保持稳定,而底层实现可以自由变化。
Building Managed Agents meant solving an old problem in computing: how to design a system for “programs as yet unthought of.” Decades ago, operating systems solved this problem by virtualizing hardware into abstractions—process, file—general enough for programs that didn't exist yet. The abstractions outlasted the hardware. The read() command is agnostic as to whether it’s accessing a disk pack from the 1970s or a modern SSD. The abstractions on top stayed stable while the implementations underneath changed freely.
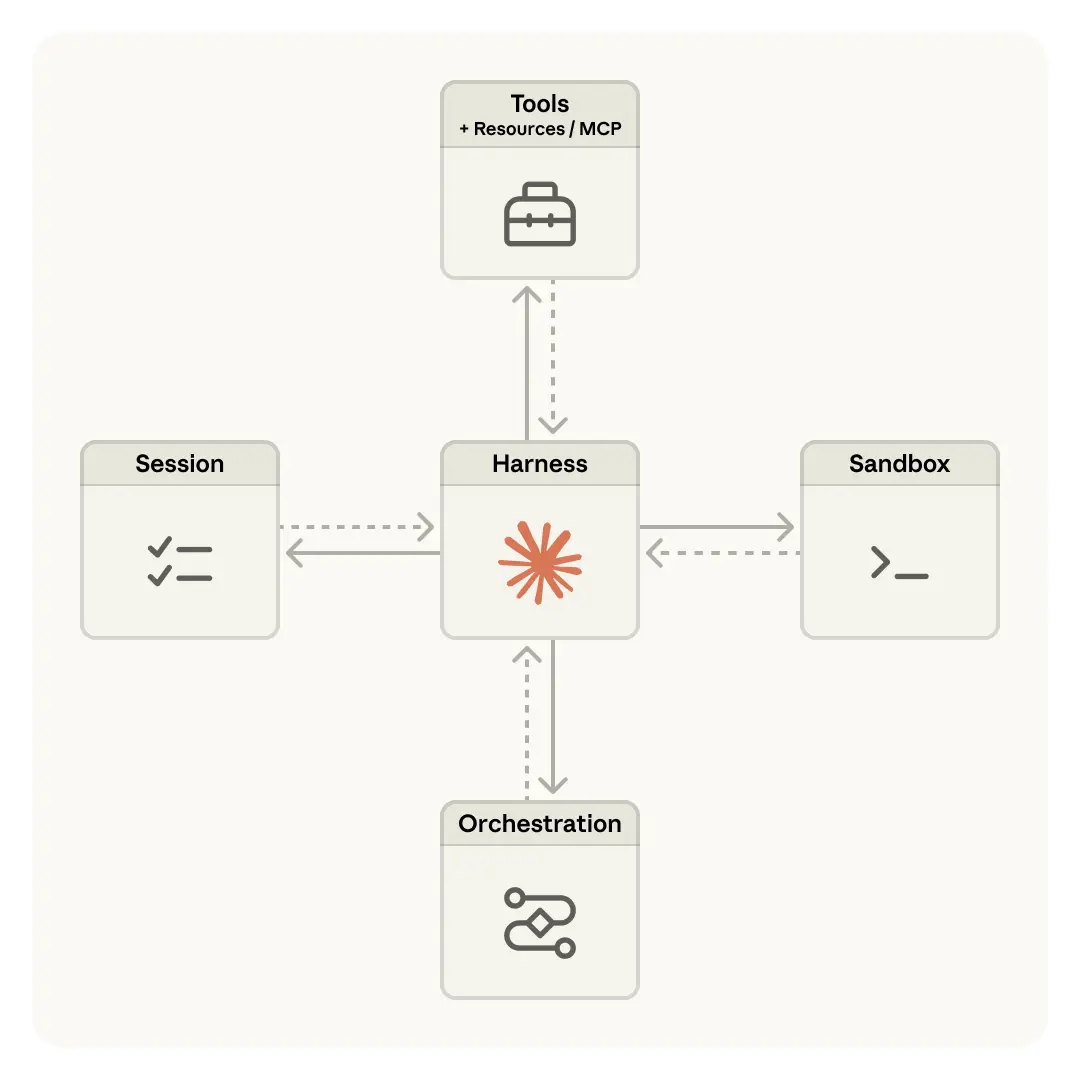
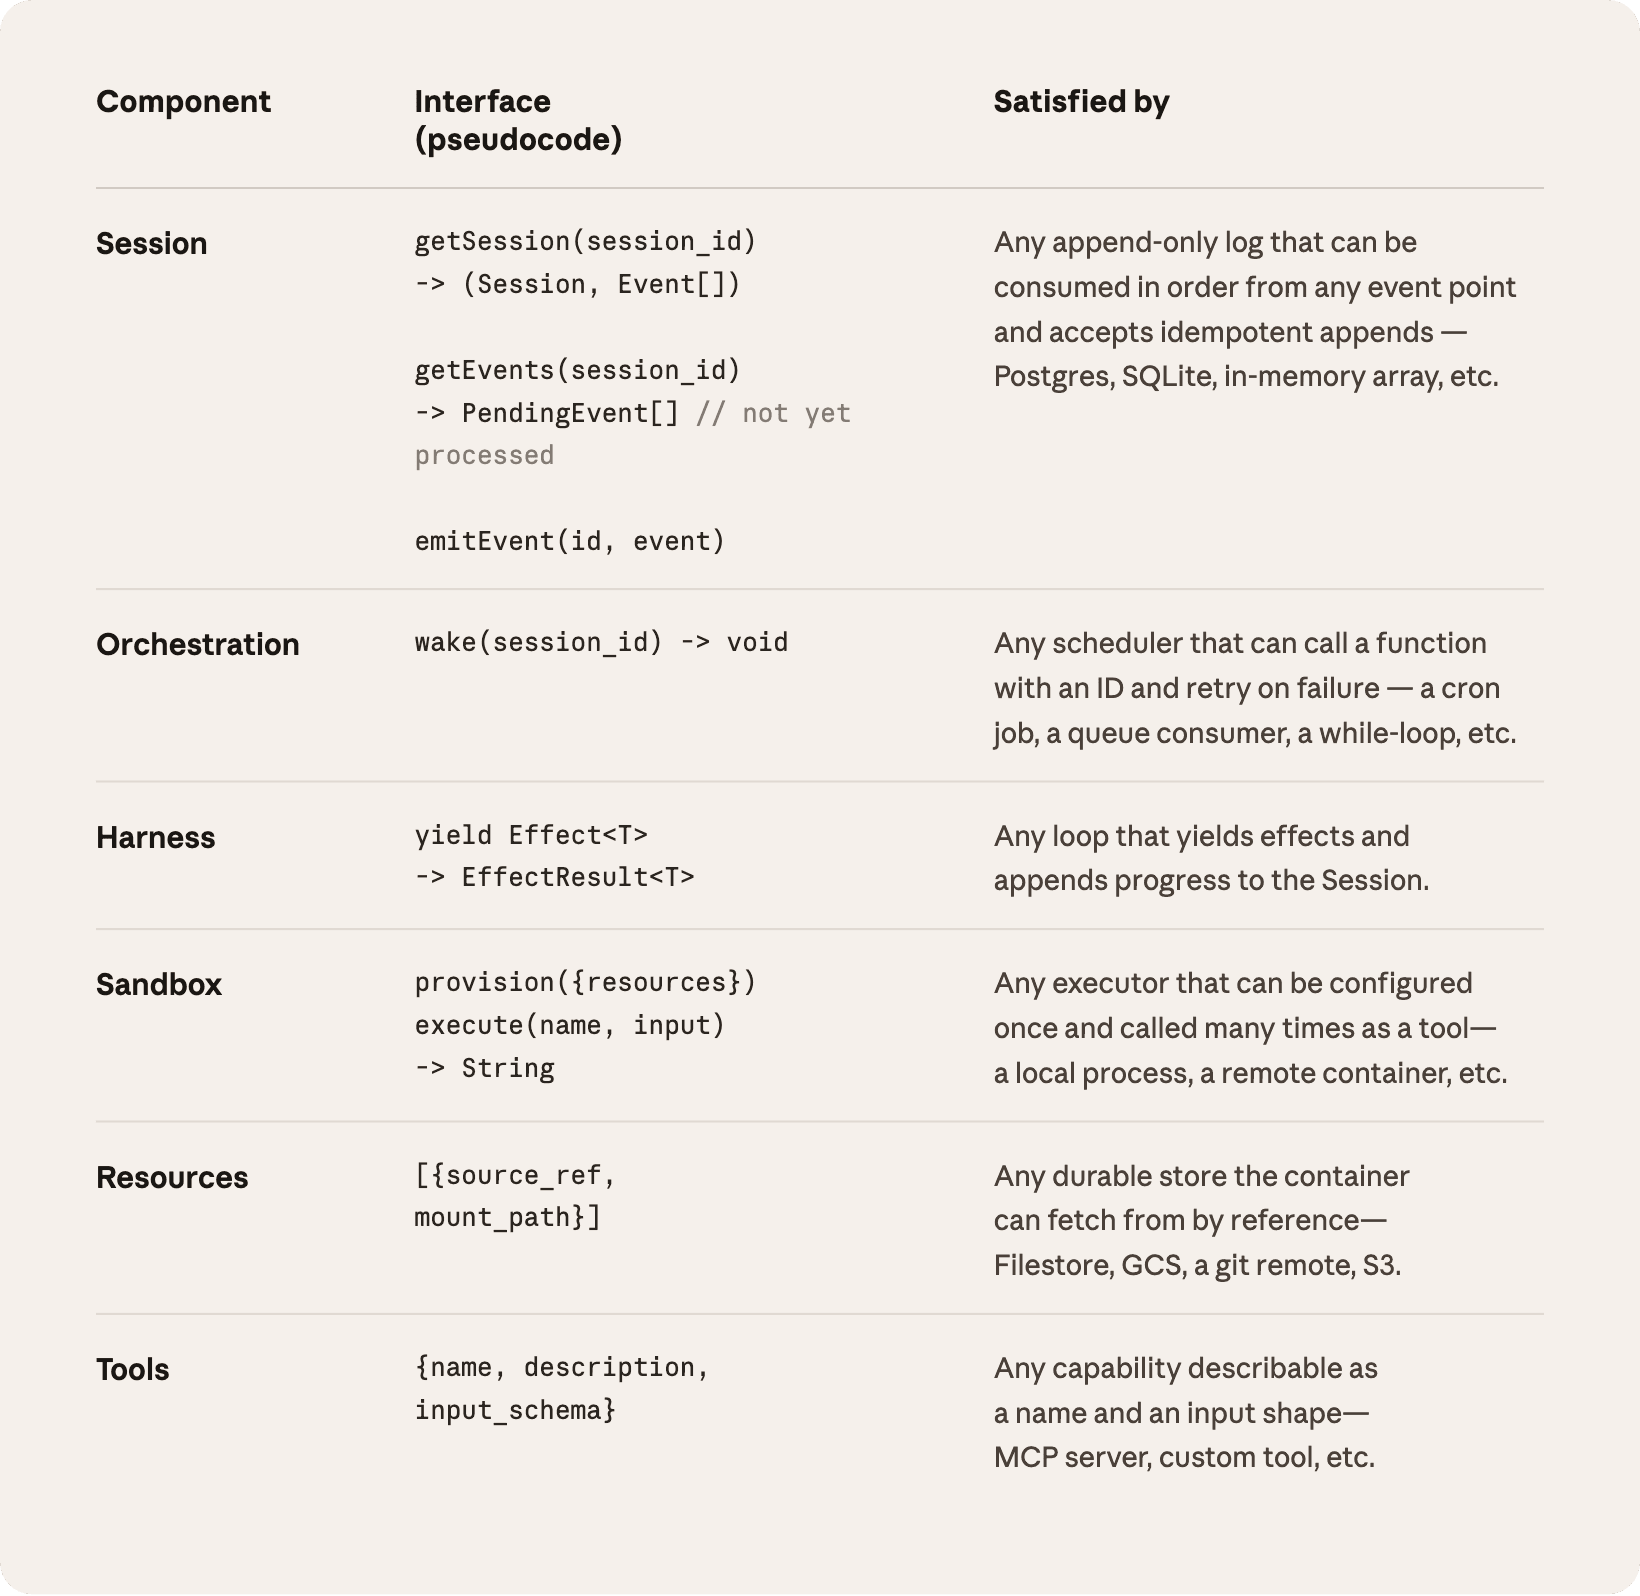
Managed Agents 采用了同样的模式。我们将 Agent 的组成部分虚拟化为:会话(记录所有已发生事件、只能追加写入的日志)、运行框架(调用 Claude,并将 Claude 的工具调用路由到相应基础设施的循环),以及沙箱(Claude 可以在其中运行代码、编辑文件的执行环境)。这样一来,各部分的实现都可以替换,而不会影响其他部分。我们对这些接口应当具有什么形态有明确主张,但不限定它们背后运行什么。
Managed Agents follow the same pattern. We virtualized the components of an agent: a session (the append-only log of everything that happened), a harness (the loop that calls Claude and routes Claude’s tool calls to the relevant infrastructure), and a sandbox (an execution environment where Claude can run code and edit files). This allows the implementation of each to be swapped without disturbing the others. We're opinionated about the shape of these interfaces, not about what runs behind them.
不要养一只“宠物”
Don’t adopt a pet
起初,我们把 Agent 的所有组件都放进同一个容器,这意味着会话、Agent 运行框架和沙箱共享同一个环境。这种做法有一些好处,例如文件编辑可以直接使用系统调用,也不需要设计服务之间的边界。
We started by placing all agent components into a single container, which meant the session, agent harness, and sandbox all shared an environment. There were benefits to this approach, including that file edits are direct syscalls, and there were no service boundaries to design.
但把所有东西耦合在一个容器中,让我们碰到了一个老牌基础设施问题:我们养了一只“宠物”。在“宠物与牲畜”的类比中,宠物是有名字、需要精心照料、无法承受失去的个体,而牲畜则可以相互替换。在我们的情境中,服务器成了那只宠物:容器一旦故障,会话就丢失了;容器一旦无响应,我们就得悉心照料,让它恢复正常。
But by coupling everything into one container, we ran into an old infrastructure problem: we’d adopted a pet. In the pets-vs-cattle analogy, a pet is a named, hand-tended individual you can’t afford to lose, while cattle are interchangeable. In our case, the server became that pet; if a container failed, the session was lost. If a container was unresponsive, we had to nurse it back to health.
照料容器意味着要调试那些卡住、没有响应的会话。我们唯一的观察窗口是 WebSocket 事件流,但它无法告诉我们故障发生在哪里。结果,运行框架中的 bug、事件流中的丢包,或者容器离线,表现出来全都一样。为了查清问题,工程师必须在容器内部打开 shell。但这个容器通常还存有用户数据,因此,这种做法实际上意味着我们没有可用的调试能力。
Nursing containers meant debugging unresponsive stuck sessions. Our only window in was the WebSocket event stream, but that couldn’t tell us where failures arose, which meant that a bug in the harness, a packet drop in the event stream, or a container going offline all presented the same. To figure out what went wrong, an engineer had to open a shell inside the container, but because that container often also held user data, that approach essentially meant we lacked the ability to debug.
第二个问题是,运行框架假设 Claude 处理的所有东西都与它放在同一个容器里。当客户要求我们将 Claude 连接到他们的虚拟私有云时,他们要么必须让自己的网络与我们的网络建立对等连接,要么必须在自己的环境中运行我们的运行框架。当我们想把运行框架连接到不同的基础设施时,固化在其中的一个假设就成了问题。
A second issue was that the harness assumed that whatever Claude worked on lived in the container with it. When customers asked us to connect Claude to their virtual private cloud, they had to either peer their network with ours, or run our harness in their own environment. An assumption baked into the harness became a problem when we wanted to connect it to different infrastructure.
将“大脑”与“双手”解耦
Decouple the brain from the hands
我们最终采取的解决方案,是把我们所说的“大脑”(Claude 及其运行框架)与“双手”(执行动作的沙箱和工具),以及“会话”(会话事件的日志)解耦。每个部分都形成了一个接口,对其他部分只做很少的假设,并且都可以独立发生故障或被替换。
The solution we arrived at was to decouple what we thought of as the “brain” (Claude and its harness) from both the “hands” (sandboxes and tools that perform actions) and the “session” (the log of session events). Each became an interface that made few assumptions about the others, and each could fail or be replaced independently.
运行框架离开容器。将大脑与双手解耦,意味着运行框架不再位于容器内部。它像调用其他任何工具一样调用容器:execute(name, input) → string。容器变成了“牲畜”。如果容器宕机,运行框架就将故障捕获为工具调用错误,并反馈给 Claude。如果 Claude 决定重试,就可以按照标准流程重新初始化一个新容器:provision({resources})。我们不再需要悉心修复发生故障的容器,让它们恢复正常。
The harness leaves the container. Decoupling the brain from the hands meant the harness no longer lived inside the container. It called the container the way it called any other tool: execute(name, input) → string. The container became cattle. If the container died, the harness caught the failure as a tool-call error and passed it back to Claude. If Claude decided to retry, a new container could be reinitialized with a standard recipe: provision({resources}). We no longer had to nurse failed containers back to health.
从运行框架故障中恢复。运行框架也变成了“牲畜”。由于会话日志位于运行框架之外,运行框架内没有任何东西必须在崩溃后保留下来。当一个运行框架发生故障时,可以通过 wake(sessionId) 启动一个新的运行框架,使用 getSession(id) 取回事件日志,并从最后一个事件继续执行。在 Agent 循环过程中,运行框架使用 emitEvent(id, event) 向会话写入事件,从而保留一份持久化的事件记录。
Recovering from harness failure. The harness also became cattle. Because the session log sits outside the harness, nothing in the harness needs to survive a crash. When one fails, a new one can be rebooted with wake(sessionId), use getSession(id) to get back the event log, and resume from the last event. During the agent loop, the harness writes to the session with emitEvent(id, event) in order to keep a durable record of events.
安全边界。在耦合的设计中,Claude 生成的任何不可信代码,都与凭证运行在同一个容器里——因此,提示注入只需要说服 Claude 读取它自己的环境即可。一旦攻击者拿到这些令牌,就可以创建新的、不受限制的会话,并将工作委派给它们。严格限制令牌的权限范围是一种显而易见的缓解措施,但这种做法隐含了一个假设:Claude 拿着受限令牌也做不了某些事情——而 Claude 正变得越来越聪明。结构性的解决办法是确保:Claude 生成的代码所运行的沙箱,永远无法访问这些令牌。
The security boundary. In the coupled design, any untrusted code that Claude generated was run in the same container as credentials—so a prompt injection only had to convince Claude to read its own environment. Once an attacker has those tokens, they can spawn fresh, unrestricted sessions and delegate work to them. Narrow scoping is an obvious mitigation, but this encodes an assumption about what Claude can't do with a limited token—and Claude is getting increasingly smart. The structural fix was to make sure the tokens are never reachable from the sandbox where Claude’s generated code runs.
我们采用了两种模式来确保这一点。身份验证可以与资源绑定,也可以保存在沙箱之外的凭证保管库中。对于 Git,我们在沙箱初始化期间,使用各代码仓库的访问令牌克隆仓库,并将其接入本地 Git 远程配置。在沙箱内部可以执行 Git push 和 pull,而 Agent 始终无需直接处理令牌本身。对于自定义工具,我们支持 MCP,并将 OAuth 令牌存储在安全的凭证保管库中。Claude 通过专用代理调用 MCP 工具;该代理接收一个与会话关联的令牌,然后从保管库中获取对应的凭证,并调用外部服务。运行框架始终不会获知任何凭证。
We used two patterns to ensure this. Auth can be bundled with a resource or held in a vault outside the sandbox. For Git, we use each repository’s access token to clone the repo during sandbox initialization and wire it into the local git remote. Git push and pull work from inside the sandbox without the agent ever handling the token itself. For custom tools, we support MCP and store OAuth tokens in a secure vault. Claude calls MCP tools via a dedicated proxy; this proxy takes in a token associated with the session. The proxy can then fetch the corresponding credentials from the vault and make the call to the external service. The harness is never made aware of any credentials.
会话并不等于 Claude 的上下文窗口
The session is not Claude’s context window
长程任务经常超出 Claude 上下文窗口的长度,而应对这一问题的常见方法,都涉及不可逆地决定保留哪些内容。我们在此前关于上下文工程的工作中探索过这些技术。例如,上下文压缩让 Claude 能够保存其上下文窗口的摘要,记忆工具则让 Claude 能把上下文写入文件,从而实现跨会话学习。这些方法还可以与上下文裁剪结合,选择性地移除旧工具结果或思考块等 token。
Long-horizon tasks often exceed the length of Claude’s context window, and the standard ways to address this all involve irreversible decisions about what to keep. We’ve explored these techniques in prior work on context engineering. For example, compaction lets Claude save a summary of its context window and the memory tool lets Claude write context to files, enabling learning across sessions. This can be paired with context trimming, which selectively removes tokens such as old tool results or thinking blocks.
但选择性保留或丢弃上下文的不可逆决策可能导致失败。我们很难知道未来的轮次需要哪些 token。如果消息经过压缩步骤转换,运行框架会将被压缩的消息从 Claude 的上下文窗口中移除;只有存储过这些消息,才能将其恢复。此前的工作探索过一种应对方式:将上下文存储为位于上下文窗口之外的对象。例如,上下文可以是 REPL 中的一个对象,LLM 通过编写代码,对它进行过滤或切片,从而以编程方式访问它。
But irreversible decisions to selectively retain or discard context can lead to failures. It is difficult to know which tokens the future turns will need. If messages are transformed by a compaction step, the harness removes compacted messages from Claude’s context window, and these are recoverable only if they are stored. Prior work has explored ways to address this by storing context as an object that lives outside the context window. For example, context can be an object in a REPL that the LLM programmatically accesses by writing code to filter or slice it.
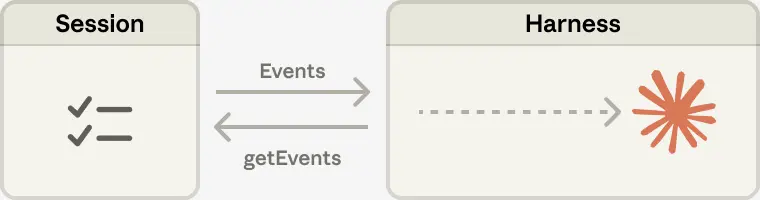
在 Managed Agents 中,会话同样提供了这一好处:它充当位于 Claude 上下文窗口之外的上下文对象。但上下文并非存储在沙箱或 REPL 中,而是持久化存储在会话日志里。getEvents(), 接口允许大脑按位置选取事件流的片段,从而查询上下文。这个接口可以灵活使用:大脑可以从上次停止阅读的位置继续,也可以回退到某个特定时刻之前的几个事件,了解事情的来龙去脉,或重新阅读某个特定动作之前的上下文。
In Managed Agents, the session provides this same benefit, serving as a context object that lives outside Claude’s context window. But rather than be stored within the sandbox or REPL, context is durably stored in the session log. The interface, getEvents(), allows the brain to interrogate context by selecting positional slices of the event stream. The interface can be used flexibly, allowing the brain to pick up from wherever it last stopped reading, rewinding a few events before a specific moment to see the lead up, or rereading context before a specific action.
获取到的任何事件,都可以先在运行框架中转换,再传入 Claude 的上下文窗口。这些转换可以是运行框架规定的任何操作,包括为了提高提示缓存命中率而组织上下文,以及其他上下文工程处理。我们将会话中可恢复的上下文存储,与运行框架中可自由实施的上下文管理分开,因为我们无法预测未来模型具体需要什么样的上下文工程。这些接口将上下文管理交由运行框架负责,只保证会话持久可靠,并且可供查询。
Any fetched events can also be transformed in the harness before being passed to Claude’s context window. These transformations can be whatever the harness encodes, including context organization to achieve a high prompt cache hit rate and context engineering. We separated the concerns of recoverable context storage in the session and arbitrary context management in the harness because we can’t predict what specific context engineering will be required in future models. The interfaces push that context management into the harness, and only guarantee that the session is durable and available for interrogation.
多个大脑,多双手
Many brains, many hands
多个大脑。将大脑与双手解耦,解决了客户最早提出的一类问题。当团队希望 Claude 操作他们自己 VPC 中的资源时,唯一的办法是让他们的网络与我们的网络建立对等连接,因为承载运行框架的容器假设每项资源都近在身旁。当运行框架不再位于容器中时,这一假设就消失了。同样的改变还带来了性能收益。最初,我们把大脑放进容器,这意味着有多少个大脑,就需要多少个容器。对每个大脑而言,容器配置完成之前无法进行任何推理;每个会话都必须预先承担完整的容器启动开销。每个会话——即使根本不会使用沙箱——都必须克隆仓库、启动进程,并从我们的服务器获取待处理事件。
Many brains. Decoupling the brain from the hands solved one of our earliest customer complaints. When teams wanted Claude to work against resources in their own VPC, the only path was to peer their network with ours, because the container holding the harness assumed every resource sat next to it. Once the harness was no longer in the container, that assumption went away. The same change had a performance payoff. When we initially put the brain in a container, it meant that many brains required as many containers. For each brain, no inference could happen until that container was provisioned; every session paid the full container setup cost up front. Every session, even ones that would never touch the sandbox, had to clone the repo, boot the process, fetch pending events from our servers.
这段空等时间体现在首 token 延迟(time-to-first-token,TTFT)中,它衡量的是会话从接受任务到生成第一个响应 token 之间的等待时间。TTFT 是用户感受最明显的延迟。
That dead time is expressed in time-to-first-token (TTFT), which measures how long a session waits between accepting work and producing its first response token. TTFT is the latency the user most acutely feels.
将大脑与双手解耦,意味着只有在确实需要容器时,大脑才会通过工具调用 (execute(name, input) → string) 配置容器。因此,不需要立即使用容器的会话,就不必等待容器就绪。只要编排层从会话日志中拉取到待处理事件,就能开始推理。采用这一架构后,我们的 p50 TTFT 降低了约 60%,p95 则降低了超过 90%。扩展到多个大脑,只需要启动多个无状态的运行框架,并仅在需要时为它们连接双手。
Decoupling the brain from the hands means that containers are provisioned by the brain via a tool call (execute(name, input) → string) only if they are needed. So a session that didn't need a container right away didn't wait for one. Inference could start as soon as the orchestration layer pulled pending events from the session log. Using this architecture, our p50 TTFT dropped roughly 60% and p95 dropped over 90%. Scaling to many brains just meant starting many stateless harnesses, and connecting them to hands only if needed.
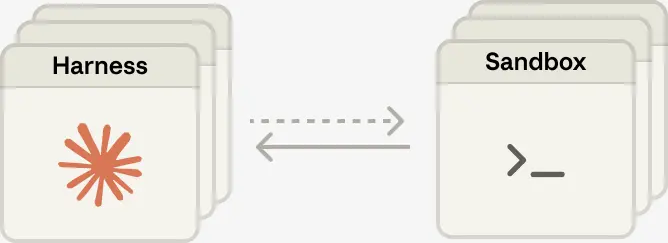
多双手。我们还希望能够为每个大脑连接多双手。在实践中,这意味着 Claude 必须对多个执行环境进行推理,并决定将工作发到哪里——这比在单个 shell 中操作需要更强的认知能力。最初,我们让大脑待在单个容器里,是因为早期模型还不具备这种能力。随着智能水平提升,单个容器反而成了限制:一旦这个容器发生故障,大脑所连接的所有“手”的状态都会丢失。
Many hands. We also wanted the ability to connect each brain to many hands. In practice, this means Claude must reason about many execution environments and decide where to send work—a harder cognitive task than operating in a single shell. We started with the brain in a single container because earlier models weren't capable of this. As intelligence scaled, the single container became the limitation instead: when that container failed, we lost state for every hand that the brain was reaching into.
将大脑与双手解耦,使每一只手都成为一个工具:execute(name, input) → string。传入名称和输入,返回一个字符串。这一接口支持任意自定义工具、任意 MCP 服务器,以及我们自己的工具。运行框架不知道沙箱究竟是一个容器、一部手机,还是一个宝可梦模拟器。而且,由于任何一只手都不与某个大脑耦合,大脑之间可以相互移交这些手。
Decoupling the brain from the hands makes each hand a tool, execute(name, input) → string: a name and input go in, and a string is returned. That interface supports any custom tool, any MCP server, and our own tools. The harness doesn’t know whether the sandbox is a container, a phone, or a Pokémon emulator. And because no hand is coupled to any brain, brains can pass hands to one another.
结语
Conclusion
我们面对的是一个老问题:如何为“尚未被构想出来的程序”设计系统。操作系统之所以能延续数十年,是因为它们把硬件虚拟化成了足够通用的抽象,能够适用于当时尚不存在的程序。通过 Managed Agents,我们希望设计一个系统,容纳未来围绕 Claude 构建的运行框架、沙箱及其他组件。
The challenge we faced is an old one: how to design a system for “programs as yet unthought of.” Operating systems have lasted decades by virtualizing the hardware into abstractions general enough for programs that didn't exist yet. With Managed Agents, we aimed to design a system that accommodates future harnesses, sandboxes, or other components around Claude.
Managed Agents 是遵循同样理念的元运行框架(meta-harness),它不预设 Claude 未来需要哪一种具体的运行框架。相反,它是一套具有通用接口、允许多种不同运行框架存在的系统。例如,Claude Code 是一个出色的运行框架,我们广泛将其用于各种任务。我们也展示过,针对特定任务设计的 Agent 运行框架,可以在狭窄领域表现优异。Managed Agents 可以容纳其中任何一种,随着时间推移适应 Claude 的智能水平。
Managed Agents is a meta-harness in the same spirit, unopinionated about the specific harness that Claude will need in the future. Rather, it is a system with general interfaces that allow many different harnesses. For example, Claude Code is an excellent harness that we use widely across tasks. We’ve also shown that task-specific agent harnesses excel in narrow domains. Managed Agents can accommodate any of these, matching Claude’s intelligence over time.
设计元运行框架,意味着对 Claude 周边接口的形态持有明确主张:我们预计 Claude 需要操作状态(会话)和执行计算(沙箱)的能力。我们也预计 Claude 需要扩展到多个大脑和多双手的能力。我们设计这些接口,是为了让它们能够在长时间跨度内可靠、安全地运行。但对于 Claude 将需要多少个大脑、多少双手,以及它们位于何处,我们不做任何假设。
Meta-harness design means being opinionated about the interfaces around Claude: we expect that Claude will need the ability to manipulate state (the session) and perform computation (the sandbox). We also expect that Claude will require the ability to scale to many brains and many hands. We designed the interfaces so that these can be run reliably and securely over long time horizons. But we make no assumptions about the number or location of brains or hands that Claude will need.
致谢
Acknowledgements
作者:Lance Martin、Gabe Cemaj 和 Michael Cohen。感谢 Nodir Turakulov 和 Jeremy Fox 就这些话题展开富有帮助的交流。特别感谢 Agents API 团队以及 Jake Eaton 的贡献。
Written by Lance Martin, Gabe Cemaj, and Michael Cohen. Thanks to Nodir Turakulov and Jeremy Fox for helpful conversations on these topics. Special thanks to the Agents API team and Jake Eaton for their contributions.
— 全文完 —
原文来自 Anthropic,中文为非官方学习译文。
查看原始出处 ↗