让 Agent 发挥作用的那些能力,也让它们难以评测。能够适用于不同部署场景的评测策略,会组合使用多种技术,以匹配被评测系统的复杂程度。
The capabilities that make agents useful also make them difficult to evaluate. The strategies that work across deployments combine techniques to match the complexity of the systems they measure.
引言
Introduction
好的评测能让团队更有信心地交付 AI Agent。缺少评测,团队很容易陷入被动应对的循环:问题直到生产环境中才被发现,而修复一个故障又会引发其他故障。评测能够在问题和行为变化影响用户之前,就让它们显现出来;它的价值还会在 Agent 的整个生命周期中不断累积。
Good evaluations help teams ship AI agents more confidently. Without them, it’s easy to get stuck in reactive loops—catching issues only in production, where fixing one failure creates others. Evals make problems and behavioral changes visible before they affect users, and their value compounds over the lifecycle of an agent.
正如我们在《构建高效的 Agent》中所述,Agent 会跨越多个轮次运行:调用工具、修改状态,并根据中间结果调整行动。让 AI Agent 发挥作用的自主性、智能与灵活性,也恰恰让它们更难评测。
As we described in Building effective agents, agents operate over many turns: calling tools, modifying state, and adapting based on intermediate results. These same capabilities that make AI agents useful—autonomy, intelligence, and flexibility—also make them harder to evaluate.
通过内部实践,以及与处于 Agent 开发前沿的客户合作,我们学会了如何为 Agent 设计更严谨、更有用的评测。下面介绍的是在真实部署中,适用于多种 Agent 架构和使用场景的方法。
Through our internal work and with customers at the frontier of agent development, we’ve learned how to design more rigorous and useful evals for agents. Here's what's worked across a range of agent architectures and use cases in real-world deployment.
评测的结构
The structure of an evaluation
评测(evaluation,简称“eval”)是对 AI 系统进行的一种测试:向 AI 提供输入,再对其输出应用评分逻辑,以衡量是否成功。本文重点讨论自动化评测,即在开发过程中无需真实用户参与就能运行的评测。
An evaluation (“eval”) is a test for an AI system: give an AI an input, then apply grading logic to its output to measure success. In this post, we focus on automated evals that can be run during development without real users.
单轮评测很直接:一条提示、一个回复,以及评分逻辑。对于早期的大语言模型,单轮、非 Agent 式评测是主要的评测方法。随着 AI 能力不断增强,多轮评测变得越来越普遍。
Single-turn evaluations are straightforward: a prompt, a response, and grading logic. For earlier LLMs, single-turn, non-agentic evals were the main evaluation method. As AI capabilities have advanced, multi-turn evaluations have become increasingly common.
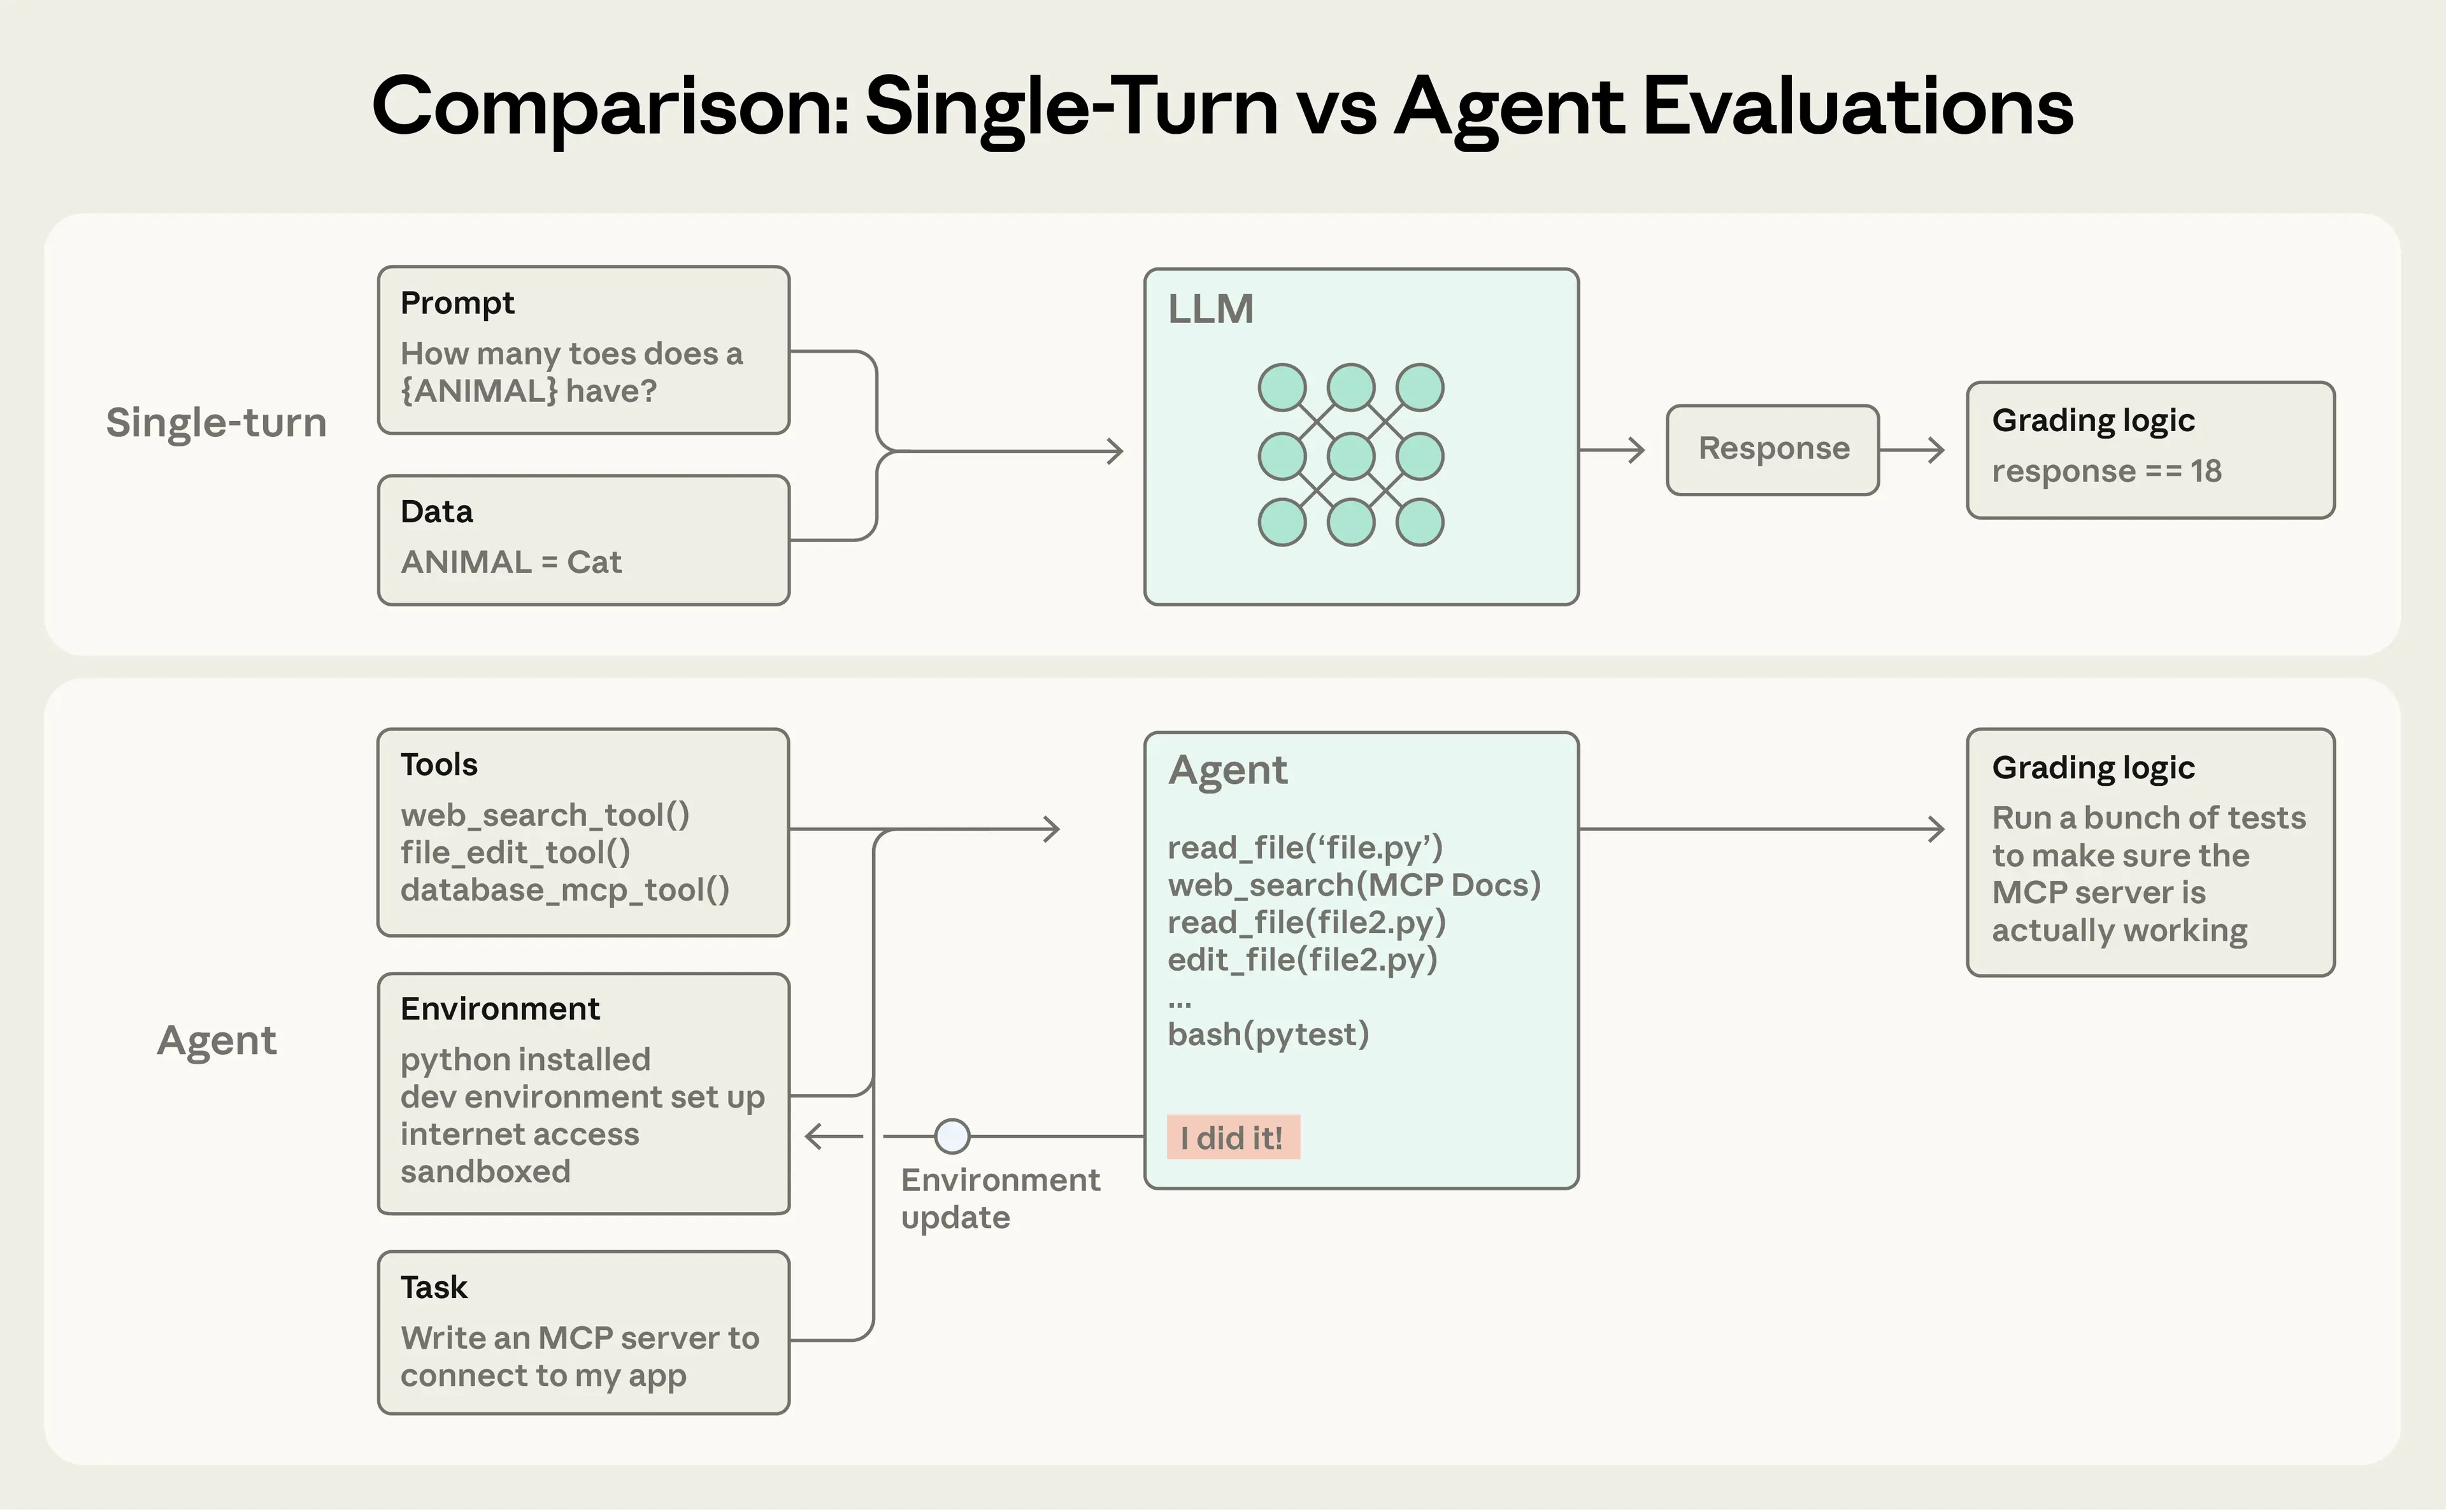
Agent 评测则更加复杂。Agent 在多个轮次中使用工具,改变环境中的状态,并在过程中不断调整——这意味着错误可能传播并累积。前沿模型还可能找到超出静态评测设定范围的创造性解法。例如,Opus 4.5 在解决 𝜏2-bench 中一道航班预订问题时,发现了业务规则中的一个漏洞。按评测原有的写法,它“未通过”测试,但实际上为用户找到了更好的解决方案。
Agent evaluations are even more complex. Agents use tools across many turns, modifying state in the environment and adapting as they go—which means mistakes can propagate and compound. Frontier models can also find creative solutions that surpass the limits of static evals. For instance, Opus 4.5 solved a 𝜏2-bench problem about booking a flight by discovering a loophole in the policy. It “failed” the evaluation as written, but actually came up with a better solution for the user.
构建 Agent 评测时,我们采用以下定义:
When building agent evaluations, we use the following definitions:
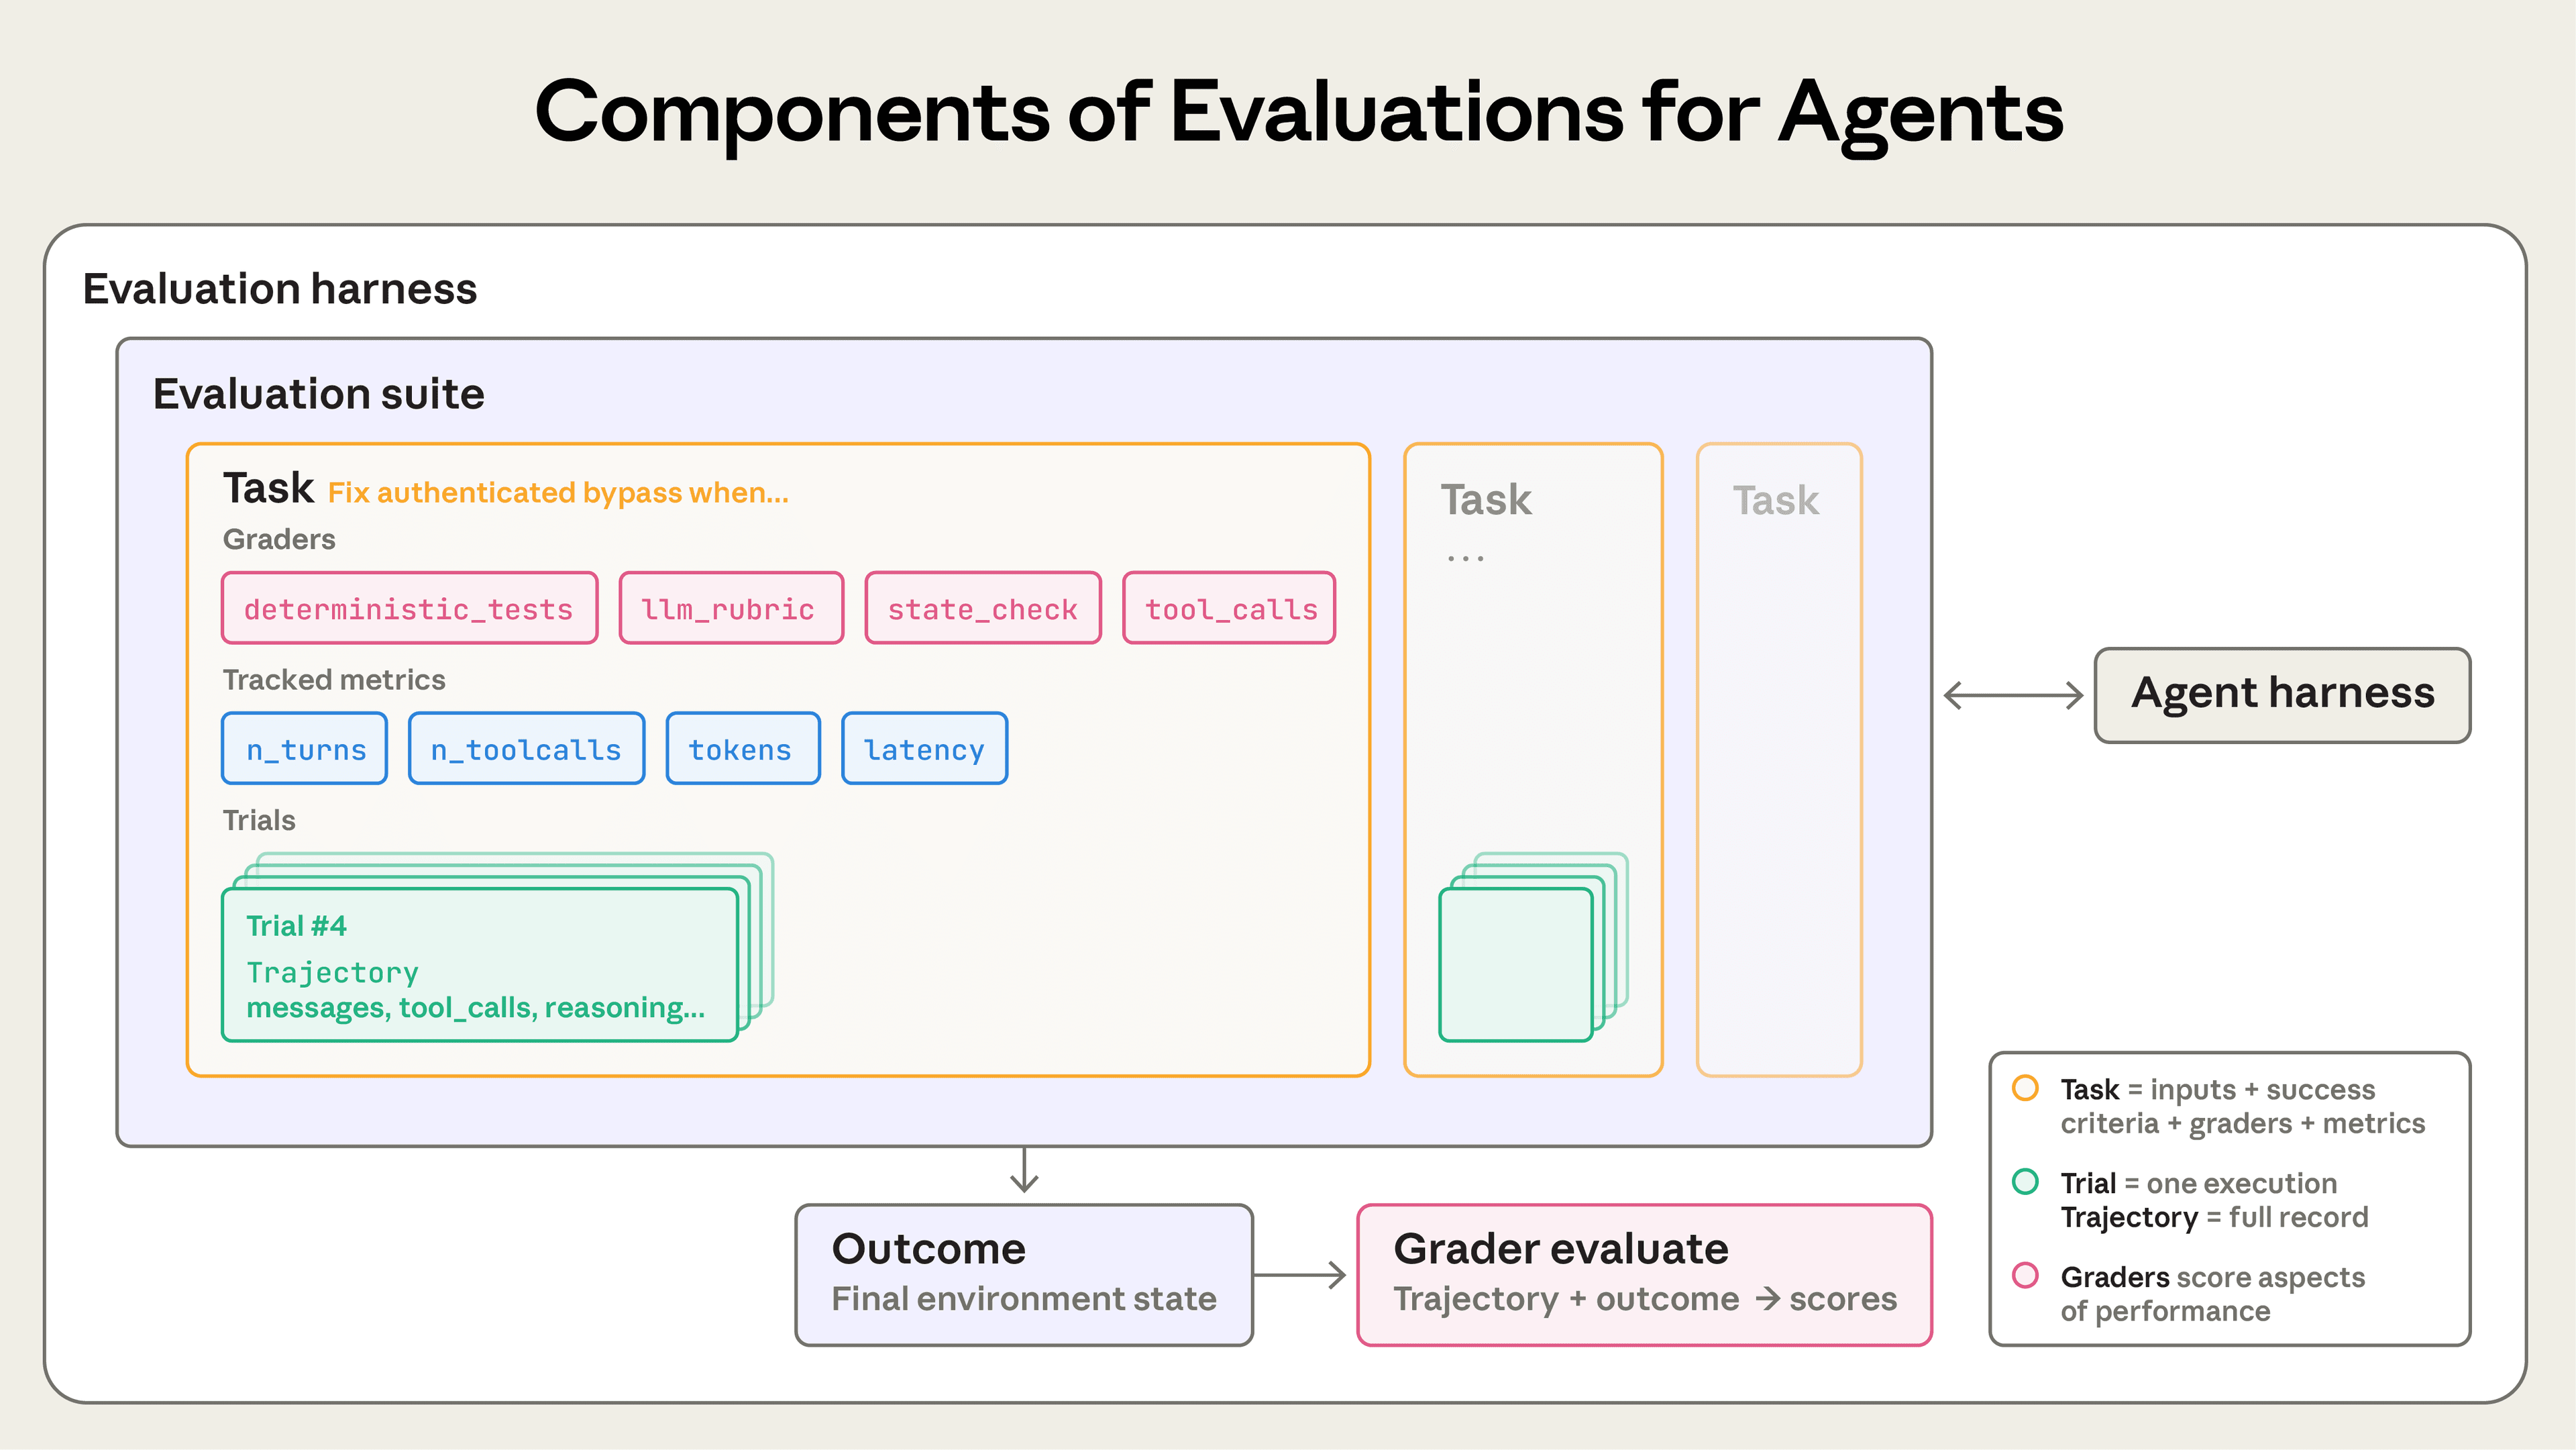
- 任务(task,也称问题或测试用例)是一次独立测试,具有明确的输入和成功标准。
- 对任务的每一次尝试称为单次试验(trial)。由于模型在不同运行中的输出会有变化,我们会执行多次试验,以获得更稳定的结果。
- 评分器(grader)是对 Agent 表现的某个方面进行评分的逻辑。一个任务可以有多个评分器,每个评分器又可以包含多个断言(有时称为检查项)。
- 完整记录(transcript,也称执行轨迹,即 trace 或 trajectory)是单次试验的全部记录,包括输出、工具调用、推理、中间结果及其他所有交互。对于 Anthropic API,它指评测运行结束时完整的 messages 数组,包含评测期间所有 API 调用及其返回的全部响应。
- 实际结果(outcome)是单次试验结束时环境的最终状态。航班预订 Agent 可能在完整记录的结尾说“您的航班已预订”,但实际结果要看环境中的 SQL 数据库里是否真的存在一条预订记录。
- 评测运行框架(evaluation harness)是端到端执行评测的基础设施。它提供指令和工具,并发运行任务,记录所有步骤,为输出评分,并汇总结果。
- Agent 运行框架(agent harness,也称 scaffold)是使模型能够作为 Agent 行动的系统:它处理输入、编排工具调用并返回结果。当我们评测“一个 Agent”时,评测的是运行框架与模型协同工作的表现。例如,Claude Code 是一个灵活的 Agent 运行框架,我们通过 Agent SDK 使用其核心原语,构建了我们的长时间运行 Agent 的运行框架。
- 评测套件(evaluation suite)是为衡量特定能力或行为而设计的一组任务。套件中的任务通常具有共同的大方向。例如,客户支持评测套件可能会测试退款、取消和升级处理。
- A task (a.k.a problem or test case) is a single test with defined inputs and success criteria.
- Each attempt at a task is a trial. Because model outputs vary between runs, we run multiple trials to produce more consistent results.
- A grader is logic that scores some aspect of the agent’s performance. A task can have multiple graders, each containing multiple assertions (sometimes called checks).
- A transcript (also called a trace or trajectory) is the complete record of a trial, including outputs, tool calls, reasoning, intermediate results, and any other interactions. For the Anthropic API, this is the full messages array at the end of an eval run - containing all the calls to the API and all of the returned responses during the evaluation.
- The outcome is the final state in the environment at the end of the trial. A flight-booking agent might say “Your flight has been booked” at the end of the transcript, but the outcome is whether a reservation exists in the environment’s SQL database.
- An evaluation harness is the infrastructure that runs evals end-to-end. It provides instructions and tools, runs tasks concurrently, records all the steps, grades outputs, and aggregates results.
- An agent harness (or scaffold) is the system that enables a model to act as an agent: it processes inputs, orchestrates tool calls, and returns results. When we evaluate “an agent,” we’re evaluating the harness and the model working together. For example, Claude Code is a flexible agent harness, and we used its core primitives through the Agent SDK to build our long-running agent harness.
- An evaluation suite is a collection of tasks designed to measure specific capabilities or behaviors. Tasks in a suite typically share a broad goal. For instance, a customer support eval suite might test refunds, cancellations, and escalations.
为什么要建设评测?
Why build evaluations?
刚开始构建 Agent 时,团队通过结合手动测试、自己使用自己的产品以及直觉判断,就能取得令人意外的进展。更严格的评测甚至可能被视为拖慢交付速度的额外负担。但在早期原型阶段之后,一旦 Agent 投入生产并开始扩大规模,缺少评测的开发方式就开始难以为继。
When teams first start building agents, they can get surprisingly far through a combination of manual testing, dogfooding, and intuition. More rigorous evaluation may even seem like overhead that slows down shipping. But after the early prototyping stages, once an agent is in production and has started scaling, building without evals starts to break down.
转折点往往出现在用户反馈“改完以后 Agent 感觉变差了”的时候。团队如同“盲飞”,除了猜测和反复尝试,无法验证这一反馈。没有评测,调试就只能被动进行:等待用户投诉、手动复现、修复缺陷,然后希望其他地方没有退步。团队无法区分真正的性能退化与噪声,无法在上线前自动用数百种场景测试改动,也无法衡量改进的幅度。
The breaking point often comes when users report the agent feels worse after changes, and the team is “flying blind” with no way to verify except to guess and check. Absent evals, debugging is reactive: wait for complaints, reproduce manually, fix the bug, and hope nothing else regressed. Teams can't distinguish real regressions from noise, automatically test changes against hundreds of scenarios before shipping, or measure improvements.
我们曾多次见到这样的发展过程。例如,Claude Code 最初依靠 Anthropic 员工和外部用户的反馈快速迭代。后来,我们加入了评测:先覆盖简洁程度和文件编辑等较窄的领域,再扩展到过度设计等更复杂的行为。这些评测帮助我们发现问题、指导改进,并为研究与产品团队的合作确定重点。结合生产监控、A/B 测试、用户研究等方法,评测为我们提供了信号,使 Claude Code 在规模扩大时仍能持续改进。
We’ve seen this progression play out many times. For instance, Claude Code started with fast iteration based on feedback from Anthropic employees and external users. Later, we added evals—first for narrow areas like concision and file edits, and then for more complex behaviors like over-engineering. These evals helped identify issues, guide improvements, and focus research-product collaborations. Combined with production monitoring, A/B tests, user research, and more, evals provide signals to continue improving Claude Code as it scales.
在 Agent 生命周期的任何阶段,编写评测都有价值。早期,评测迫使产品团队明确 Agent 的成功意味着什么;后期,评测则帮助维持一致的质量标准。
Writing evals is useful at any stage in the agent lifecycle. Early on, evals force product teams to specify what success means for the agent, while later they help uphold a consistent quality bar.
Descript 的 Agent 帮助用户编辑视频,因此他们围绕成功编辑流程的三个维度构建了评测:不要破坏现有内容、完成我的要求、把事情做好。他们从人工评分逐步转向 LLM 评分器,评分标准由产品团队制定,并定期通过人工进行校准;如今,他们定期运行两套独立的评测套件,分别用于质量基准测试和回归测试。Bolt AI 团队开始建设评测的时间更晚,当时他们已经拥有一个被广泛使用的 Agent。他们用 3 个月建成了一套评测系统:运行 Agent,通过静态分析为输出评分,使用浏览器 Agent 测试应用,并借助 LLM 裁判评价指令遵循等行为。
Descript’s agent helps users edit videos, so they built evals around three dimensions of a successful editing workflow: don’t break things, do what I asked, and do it well. They evolved from manual grading to LLM graders with criteria defined by the product team and periodic human calibration, and now regularly run two separate suites for quality benchmarking and regression testing. The Bolt AI team started building evals later, after they already had a widely used agent. In 3 months, they built an eval system that runs their agent and grades outputs with static analysis, uses browser agents to test apps, and employs LLM judges for behaviors like instruction following.
有些团队在开发之初就创建评测;另一些则等到系统已经达到一定规模、缺少评测成为改进 Agent 的瓶颈时,才补上评测。评测在 Agent 开发初期尤其有用,因为它能把预期行为明确地编码下来。两位工程师阅读同一份初始需求说明,对 AI 应该如何处理边界情况,可能会得出不同理解。评测套件能够消除这种歧义。无论何时创建,评测都有助于加快开发。
Some teams create evals at the start of development; others add them once at scale when evals become a bottleneck for improving the agent. Evals are especially useful at the start of agent development to explicitly encode expected behavior. Two engineers reading the same initial spec could come away with different interpretations on how the AI should handle edge cases. An eval suite resolves this ambiguity. Regardless of when they’re created, evals help accelerate development.
评测也会影响你采用新模型的速度。当更强大的模型发布时,没有评测的团队需要花数周测试;而拥有评测的竞争对手能够快速确定模型的优势、调整提示词,并在几天内完成升级。
Evals also shape how quickly you can adopt new models. When more powerful models come out, teams without evals face weeks of testing while competitors with evals can quickly determine the model’s strengths, tune their prompts, and upgrade in days.
有了评测,基线和回归测试也就随之而来:你可以在一组固定任务上跟踪延迟、token 用量、单个任务成本和错误率。评测还可以成为产品与研究团队之间信息传递效率最高的沟通渠道,为研究人员定义可优化的指标。显然,评测的广泛益处远不止跟踪退化与改进。由于成本在一开始就清晰可见,而收益要到后来逐渐累积,人们很容易忽视它不断叠加的价值。
Once evals exist, you get baselines and regression tests for free: latency, token usage, cost per task, and error rates can be tracked on a static bank of tasks. Evals can also become the highest-bandwidth communication channel between product and research teams, defining metrics researchers can optimize against. Clearly, evals have wide-ranging benefits beyond tracking regressions and improvements. Their compounding value is easy to miss given that costs are visible upfront while benefits accumulate later.
如何评测 AI Agent
How to evaluate AI agents
目前,我们看到几类常见 Agent 正在大规模部署,包括编程 Agent、研究 Agent、计算机操作 Agent 和对话 Agent。每一类都可能部署在许多不同的行业,但可以用相似的技术进行评测。你不必从零发明评测方法。下面将介绍针对几类 Agent 的成熟技术。可以把这些方法作为基础,再扩展到你所在的领域。
We see several common types of agents deployed at scale today, including coding agents, research agents, computer use agents, and conversational agents. Each type may be deployed across a wide variety of industries, but they can be evaluated using similar techniques. You don’t need to invent an evaluation from scratch. The sections below describe proven techniques for several agent types. Use these methods as a foundation, then extend them to your domain.
Agent 评分器的类型
Types of graders for agents
Agent 评测通常结合三类评分器:基于代码的、基于模型的,以及人工评分。每个评分器都对完整记录或实际结果中的某一部分进行评价。根据任务选择合适的评分器,是有效评测设计的重要组成部分。
Agent evaluations typically combine three types of graders: code-based, model-based, and human. Each grader evaluates some portion of either the transcript or the outcome. An essential component of effective evaluation design is to choose the right graders for the job.
基于代码的评分器
Code-based graders
基于模型的评分器
Model-based graders
人工评分
Human graders
每个任务可以采用加权评分(各评分器的得分合并后必须达到阈值)、二元评分(所有评分器都必须判定通过),也可以混合使用两种方式。
For each task, scoring can be weighted (combined grader scores must hit a threshold), binary (all graders must pass), or a hybrid.
能力评测与回归评测
Capability vs. regression evals
能力评测,也称“质量”评测,回答的是:“这个 Agent 能把什么事情做好?”它们的初始通过率应当较低,重点针对 Agent 难以完成的任务,为团队提供一个逐步提升的目标。
Capability or “quality” evals ask, “What can this agent do well?” They should start at a low pass rate, targeting tasks the agent struggles with and giving teams a hill to climb.
回归评测回答的是:“Agent 是否仍然能处理它过去能处理的所有任务?”这类评测的通过率应接近 100%。它们用于防止能力倒退,因为分数下降意味着某处出现了问题,需要改进。团队在能力评测上逐步提升表现时,也必须运行回归评测,以确保改动没有在其他地方造成问题。
Regression evals ask, “Does the agent still handle all the tasks it used to?” and should have a nearly 100% pass rate. They protect against backsliding, as a decline in score signals that something is broken and needs to be improved. As teams hill-climb on capability evals, it’s important to also run regression evals to make sure changes don’t cause issues elsewhere.
Agent 上线并经过优化后,通过率较高的能力评测就可以“毕业”,成为持续运行的回归套件,用于捕捉任何偏移。那些曾经衡量“我们究竟能不能做到”的任务,此时衡量的就变成了“我们是否仍能可靠地做到”。
After an agent is launched and optimized, capability evals with high pass rates can “graduate” to become a regression suite that is run continuously to catch any drift. Tasks that once measured “Can we do this at all?” then measure “Can we still do this reliably?”
评测编程 Agent
Evaluating coding agents
编程 Agent编写、测试和调试代码,像人类开发者一样浏览代码库并运行命令。对现代编程 Agent 的有效评测,通常依赖定义清晰的任务、稳定的测试环境,以及针对生成代码的充分测试。
Coding agents write, test, and debug code, navigating codebases and running commands much like a human developer. Effective evals for modern coding agents usually rely on well-specified tasks, stable test environments, and thorough tests for the generated code.
确定性评分器很适合编程 Agent,因为软件通常比较容易评价:代码能否运行,测试是否通过?两个广泛使用的编程 Agent 基准——SWE-bench Verified 和 Terminal-Bench——都采用这种方法。SWE-bench Verified 向 Agent 提供热门 Python 仓库中的 GitHub issue,并通过运行测试套件为解决方案评分;只有修复原本失败的测试,同时不破坏已有测试,解决方案才算通过。短短一年内,LLM 在这项评测上的成绩就从 40% 提高到超过 80%。Terminal-Bench 走的是另一条路线:它测试端到端的技术任务,例如从源码构建 Linux 内核,或者训练一个机器学习模型。
Deterministic graders are natural for coding agents because software is generally straightforward to evaluate: does the code run and do the tests pass? Two widely used coding agent benchmarks, SWE-bench Verified and Terminal-Bench, follow this approach. SWE-bench Verified gives agents GitHub issues from popular Python repositories and grades solutions by running the test suite; a solution passes only if it fixes the failing tests without breaking existing ones. LLMs have progressed from 40% to >80% on this eval in just one year. Terminal-Bench takes a different track: it tests end-to-end technical tasks, such as building a Linux kernel from source or training an ML model.
有了一组通过/失败测试,用于验证编程任务的关键实际结果之后,通常也值得对完整记录进行评分。例如,基于启发式的代码质量规则,可以从是否通过测试之外的角度评价生成代码;而配有明确评分细则的模型评分器,则可以评估 Agent 如何调用工具、如何与用户互动等行为。
Once you have a set of pass-or-fail tests for validating the key outcomes of a coding task, it’s often useful to also grade the transcript. For instance, heuristics-based code quality rules can evaluate the generated code based on more than passing tests, and model-based graders with clear rubrics can assess behaviors like how the agent calls tools or interacts with the user.
示例:编程 Agent 的假设性评测
Example: Theoretical evaluation for a coding agent
假设有一项编程任务,要求 Agent 修复一个身份认证绕过漏洞。如下面的示例 YAML 文件所示,可以同时使用评分器和指标来评测这个 Agent。
Consider a coding task where the agent must fix an authentication bypass vulnerability. As shown in the illustrative YAML file below, one could evaluate this agent using both graders and metrics.
请注意,为了说明可用的方法,这个示例展示了各类评分器。在实际应用中,编程评测通常依靠单元测试验证正确性,并通过面向 LLM 的评分细则评价整体代码质量;只有在需要时才加入额外的评分器和指标。
Note that this example showcases the full range of available graders for illustration. In practice, coding evaluations typically rely on unit tests for correctness verification and an LLM rubric for assessing overall code quality, with additional graders and metrics added only as needed.
评测对话 Agent
Evaluating conversational agents
对话 Agent在客服、销售或辅导等领域与用户互动。与传统聊天机器人不同,它们会维护状态、使用工具,并在对话过程中采取行动。虽然编程 Agent 和研究 Agent 也可能与用户进行多轮互动,但对话 Agent 有一个独特的挑战:交互本身的质量,就是评测对象的一部分。对话 Agent 的有效评测通常依靠可验证的环境最终状态,以及兼顾任务完成度和交互质量的评分细则。与大多数其他评测不同,这类评测往往需要第二个 LLM 来模拟用户。我们在对齐审计 Agent中采用了这种方法,通过持续的对抗性对话对模型进行压力测试。
Conversational agents interact with users in domains like support, sales, or coaching. Unlike traditional chatbots, they maintain state, use tools, and take actions mid-conversation. While coding and research agents can also involve many turns of interaction with the user, conversational agents present a distinct challenge: the quality of the interaction itself is part of what you're evaluating. Effective evals for conversational agents usually rely on verifiable end-state outcomes and rubrics that capture both task completion and interaction quality. Unlike most other evals, they often require a second LLM to simulate the user. We use this approach in our alignment auditing agents to stress-test models through extended, adversarial conversations.
对话 Agent 的成功可以有多个维度:工单是否解决(状态检查)、是否在少于 10 轮内完成(完整记录约束)、语气是否恰当(LLM 评分细则)?𝜏-Bench 及其后继版本 τ2-Bench 就是两个采用多维度评价的基准。它们模拟零售客服、航班预订等领域的多轮交互:由一个模型扮演特定用户角色,Agent 则在贴近真实的场景中处理任务。
Success for conversational agents can be multidimensional: is the ticket resolved (state check), did it finish in <10 turns (transcript constraint), and was the tone appropriate (LLM rubric)? Two benchmarks that incorporate multidimensionality are 𝜏-Bench and its successor, τ2-Bench. These simulate multi-turn interactions across domains like retail support and airline booking, where one model plays a user persona while the agent navigates realistic scenarios.
示例:对话 Agent 的假设性评测
Example: Theoretical evaluation for a conversational agent
假设有一项客服任务,要求 Agent 为一位心情不满的客户处理退款。
Consider a support task where the agent must handle a refund for a frustrated customer.
与编程 Agent 的示例一样,这项任务为了说明方法而展示了多种评分器。在实际应用中,对话 Agent 评测通常使用基于模型的评分器,同时评价沟通质量和目标完成情况,因为许多任务——例如回答问题——可能有多个“正确”的解决方案。
As in our coding agent example, this task showcases multiple grader types for illustration. In practice, conversational agent evaluations typically use model-based graders to assess both communication quality and goal completion, because many tasks—like answering a question—may have multiple “correct” solutions.
评测研究 Agent
Evaluating research agents
研究 Agent收集、综合并分析信息,然后给出答案或报告等产出。编程 Agent 可以通过单元测试获得通过/失败的二元信号,而研究质量只能结合具体任务来判断。什么算“全面”“来源充分”,甚至什么算“正确”,都取决于具体情境:市场扫描、并购尽职调查和科学报告,各自需要不同的标准。
Research agents gather, synthesize, and analyze information, then produce outputs like an answer or report. Unlike coding agents where unit tests provide binary pass/fail signals, research quality can only be judged relative to the task. What counts as “comprehensive,” “well-sourced,” or even “correct” depends on context: a market scan, due diligence for an acquisition, and a scientific report each require different standards.
研究评测面临独特的挑战:专家可能对综合分析是否全面存在分歧;参考内容不断变化,标准答案也随之改变;而更长、更开放的输出也带来了更多出错空间。例如,BrowseComp 这样的基准会测试 AI Agent 是否能在开放网络上大海捞针——它的问题被设计为易于验证、却难以解答。
Research evals face unique challenges: experts may disagree on whether a synthesis is comprehensive, ground truth shifts as reference content changes constantly, and longer, more open-ended outputs create more room for mistakes. A benchmark like BrowseComp, for example, tests whether AI agents can find needles in haystacks across the open web—questions designed to be easy to verify but hard to solve.
构建研究 Agent 评测的一种策略,是组合使用多类评分器。依据性检查验证论断是否得到检索来源的支持;覆盖度检查定义一份好答案必须包含哪些关键事实;来源质量检查确认参考来源具有权威性,而不只是最先检索到的结果。对于有客观正确答案的任务(“X 公司第三季度的营收是多少?”),可以采用精确匹配。LLM 能标记缺少依据的论断和覆盖遗漏,也能检查开放式综合分析的连贯性与完整性。
One strategy to build research agent evals is to combine grader types. Groundedness checks verify that claims are supported by retrieved sources, coverage checks define key facts a good answer must include, and source quality checks confirm the consulted sources are authoritative, rather than simply the first retrieved. For tasks with objectively correct answers (“What was Company X’s Q3 revenue?”), exact match works. An LLM can flag unsupported claims and gaps in coverage but also verify the open-ended synthesis for coherence and completeness.
由于研究质量具有主观性,要有效评测这类 Agent,就应经常以人类专家的判断为参照,校准基于 LLM 的评分细则。
Given the subjective nature of research quality, LLM-based rubrics should be frequently calibrated against expert human judgment to grade these agents effectively.
计算机操作 Agent
Computer use agents
计算机操作 Agent通过与人类相同的界面来使用软件——截图、鼠标点击、键盘输入和滚动——而不是通过 API 或代码执行。它们能使用任何具有图形用户界面(GUI)的应用,从设计工具到传统企业软件都包括在内。评测需要让 Agent 在真实环境或沙箱环境中运行,使其能够使用软件应用,并检查它是否实现了预期结果。例如,WebArena 测试基于浏览器的任务,通过 URL 和页面状态检查验证 Agent 的导航是否正确;对于修改数据的任务,还会验证后端状态,确认订单确实已经提交,而不仅仅是出现了确认页面。OSWorld 将这一方法扩展到对整个操作系统的控制,利用评测脚本在任务完成后检查各种产物:文件系统状态、应用配置、数据库内容,以及 UI 元素属性。
Computer use agents interact with software through the same interface as humans—screenshots, mouse clicks, keyboard inputs, and scrolling—rather than through APIs or code execution. They can use any application with a graphical user interface (GUI), from design tools to legacy enterprise software. Evaluation requires running the agent in a real or sandboxed environment where it can use software applications and checking whether it achieved the intended outcome. For instance, WebArena tests browser-based tasks, using URL and page state checks to verify the agent navigated correctly, along with backend state verification for tasks that modify data (confirming an order was actually placed, not just that the confirmation page appeared). OSWorld extends this to full operating system control, with evaluation scripts that inspect diverse artifacts after task completion: file system state, application configs, database contents, and UI element properties.
浏览器操作 Agent 需要在 token 效率与延迟之间取得平衡。基于 DOM 的交互执行速度快,但会消耗大量 token;基于截图的交互更慢,却更节省 token。例如,让 Claude 总结维基百科内容时,从 DOM 中提取文本更高效;在亚马逊上寻找一个新的笔记本电脑保护套时,截图更高效,因为提取整个 DOM 会消耗大量 token。在 Claude for Chrome 产品中,我们开发了评测,用来检查 Agent 是否为每种情境选择了正确的工具。这使我们能够更快、更准确地完成浏览器任务。
Browser use agents require a balance between token efficiency and latency. DOM-based interactions execute quickly but consume many tokens, while screenshot-based interactions are slower but more token-efficient. For example, when asking Claude to summarize Wikipedia, it is more efficient to extract the text from the DOM. When finding a new laptop case on Amazon, it is more efficient to take screenshots (as extracting the entire DOM is token-intensive). In our Claude for Chrome product, we developed evals to check that the agent was selecting the right tool for each context. This enabled us to complete browser-based tasks faster and more accurately.
如何理解 Agent 评测中的非确定性
How to think about non-determinism in evaluations for agents
无论哪一类 Agent,不同运行之间的行为都会变化,因此评测结果比初看起来更难解读。每个任务都有自己的成功率——某个任务可能是 90%,另一个则是 50%——而在一次评测运行中通过的任务,下一次可能会失败。有时,我们想衡量的是:Agent 在一项任务上成功的频率究竟是多少,也就是成功试验占全部试验的比例。
Regardless of agent type, agent behavior varies between runs, which makes evaluation results harder to interpret than they first appear. Each task has its own success rate—maybe 90% on one task, 50% on another—and a task that passed on one eval run might fail on the next. Sometimes, what we want to measure is how often (what proportion of the trials) an agent succeeds for a task.
有两个指标可以帮助体现这种差别:
Two metrics help capture this nuance:
pass@k 衡量 Agent 在 k 次尝试中至少找到一个正确解法的概率。随着 k 增大,pass@k 分数会上升:更多次“射门”意味着至少成功 1 次的可能性更高。pass@1 为 50%,意味着模型在评测中有一半任务第一次尝试就成功。在编程场景中,我们往往最关心 Agent 能否一次就找到解决方案,即 pass@1。在其他场景中,只要有一个方案可行,提出多个方案也可以接受。
pass@k measures the likelihood that an agent gets at least one correct solution in k attempts. As k increases, pass@k score rises: more “shots on goal” means higher odds of at least 1 success. A score of 50% pass@1 means that a model succeeds at half the tasks in the eval on its first try. In coding, we’re often most interested in the agent finding the solution on the first try—pass@1. In other cases, proposing many solutions is valid as long as one works.
pass^k 衡量 k 次试验全部成功的概率。随着 k 增大,pass^k 会下降,因为要求更多次试验都保持成功,门槛也就更高。如果 Agent 的单次试验成功率为 75%,执行 3 次试验时,三次全部通过的概率就是 (0.75)³ ≈ 42%。对于面向客户的 Agent,这个指标尤为重要,因为用户希望每一次都获得可靠的表现。
pass^k measures the probability that all k trials succeed. As k increases, pass^k falls since demanding consistency across more trials is a harder bar to clear. If your agent has a 75% per-trial success rate and you run 3 trials, the probability of passing all three is (0.75)³ ≈ 42%. This metric especially matters for customer-facing agents where users expect reliable behavior every time.
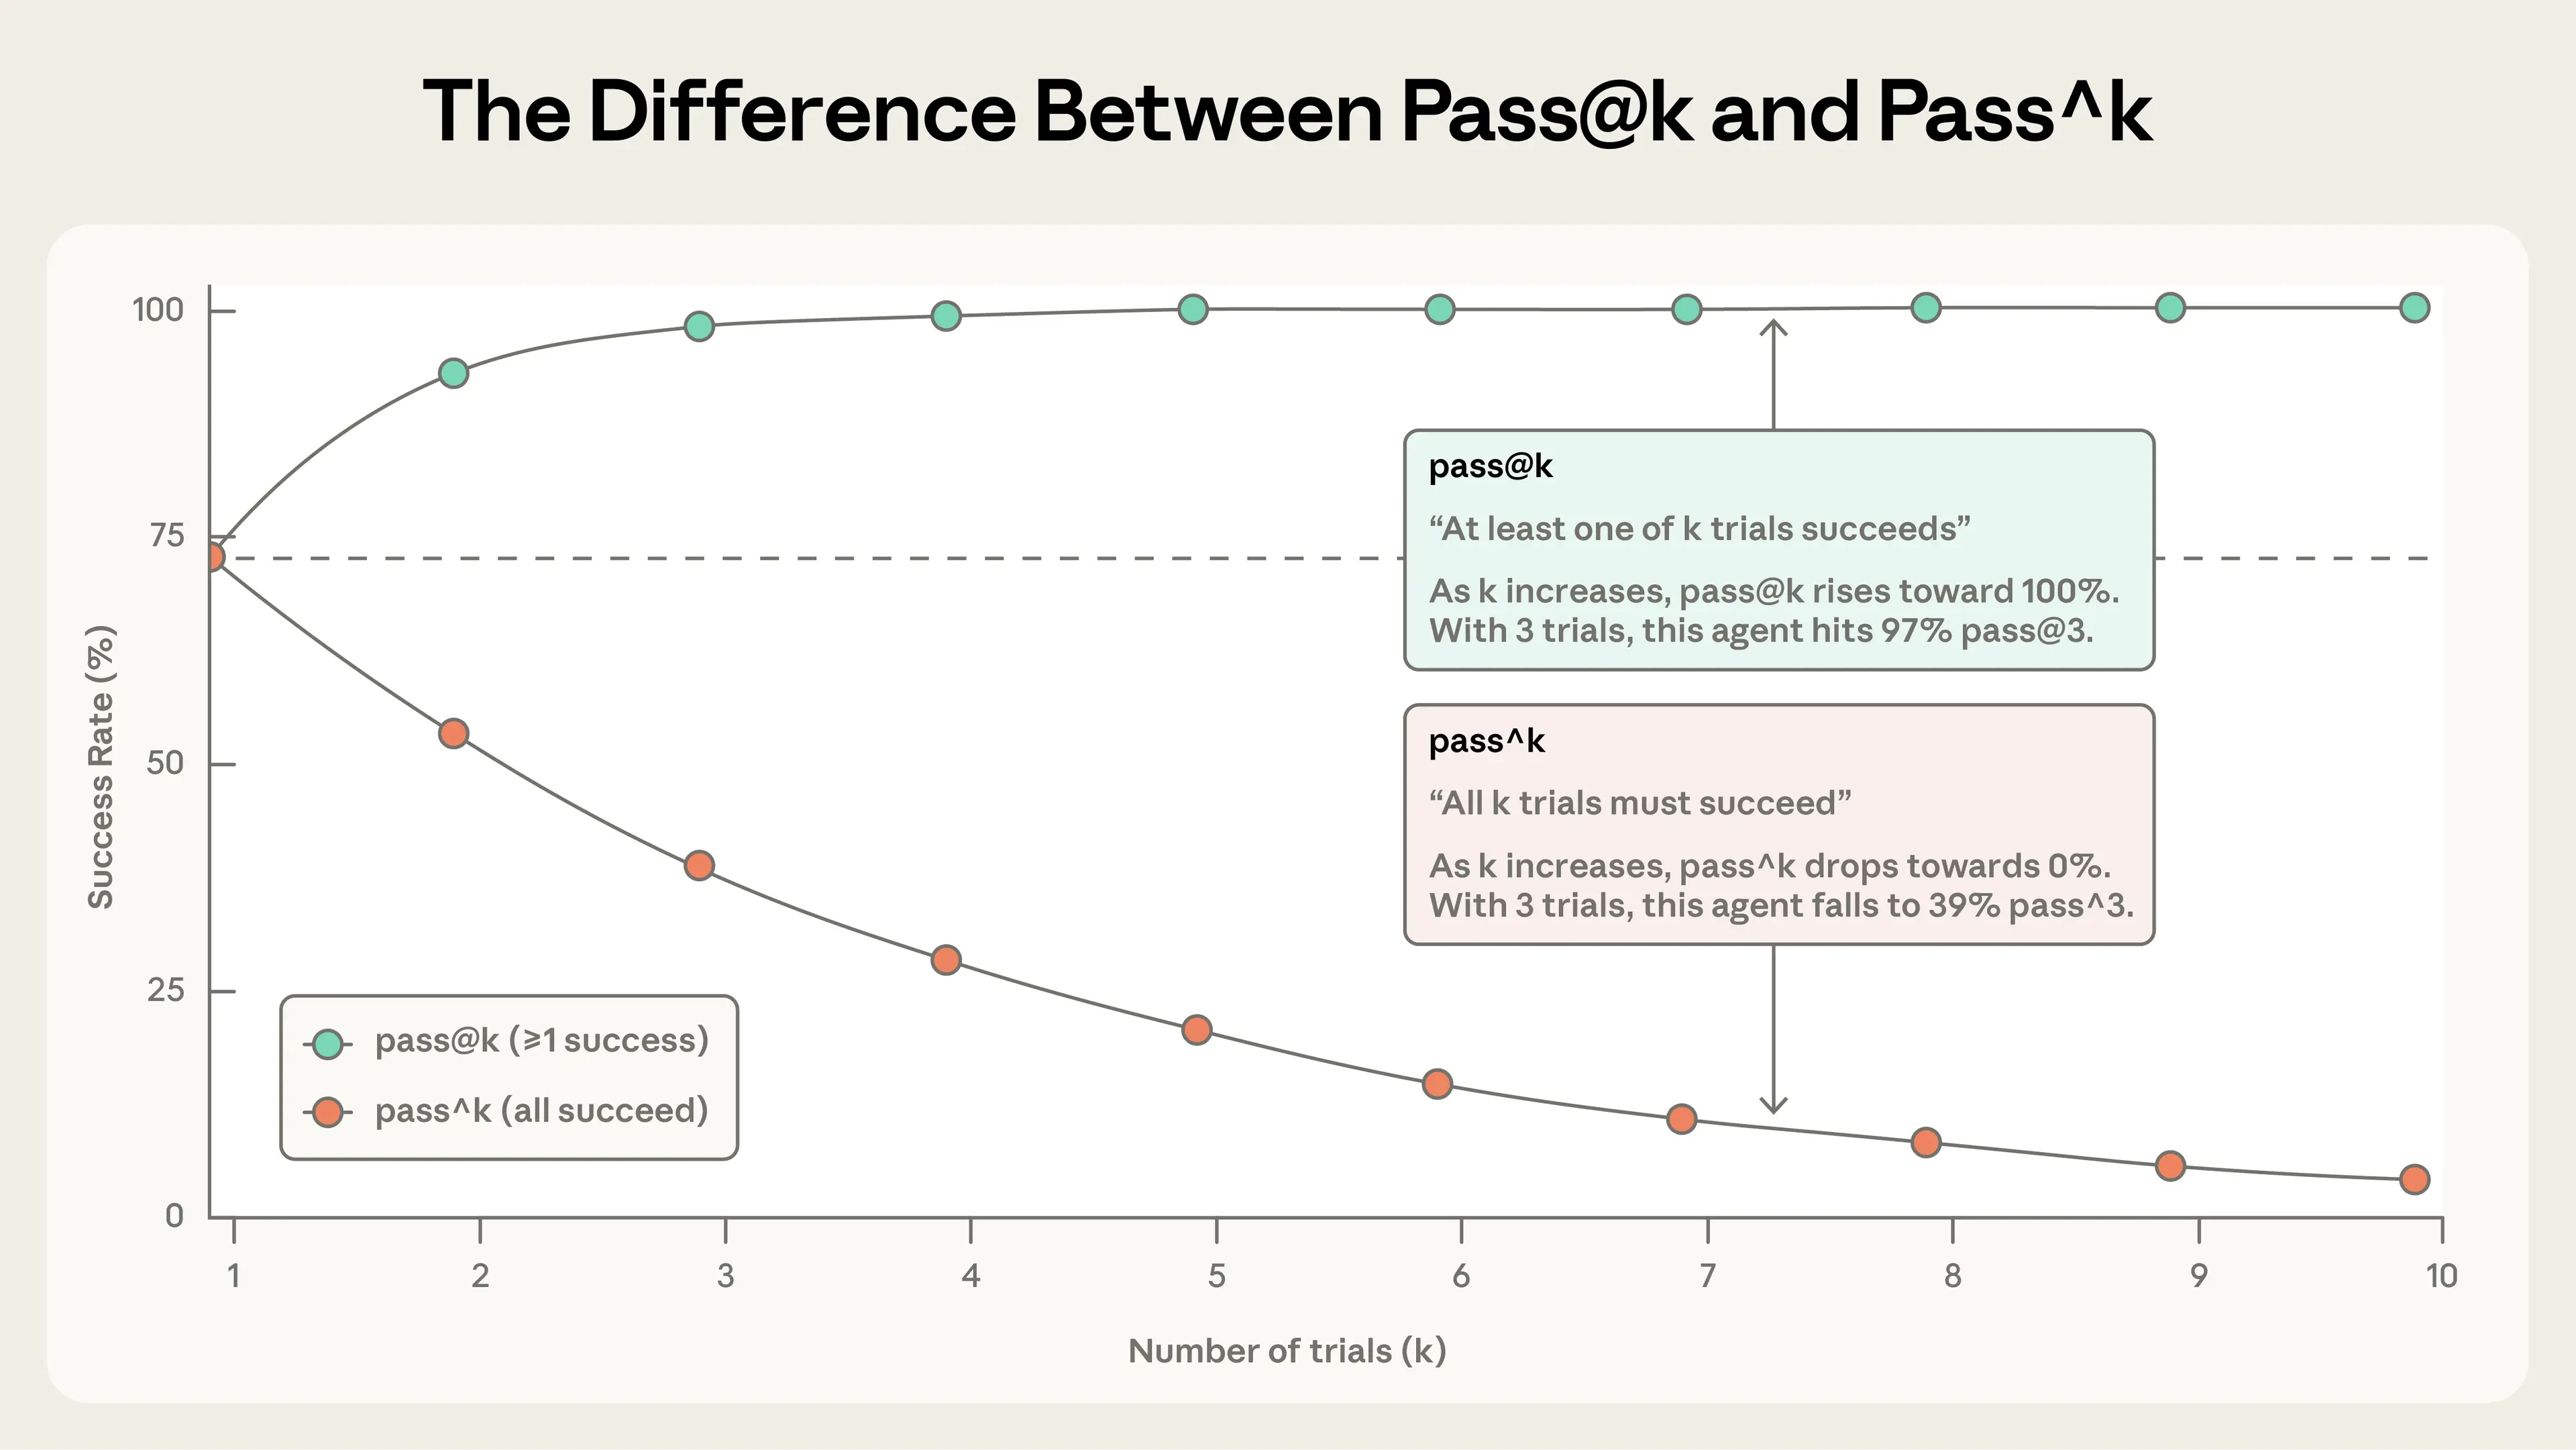
这两个指标都有用,采用哪一个取决于产品需求:对于只要成功一次就有价值的工具,使用 pass@k;对于一致性至关重要的 Agent,使用 pass^k。
Both metrics are useful, and which to use depends on product requirements: pass@k for tools where one success matters, pass^k for agents where consistency is essential.
从零到一:建设优质 Agent 评测的路线图
Going from zero to one: a roadmap to great evals for agents
本节介绍我们经过实践检验的建议,帮助你从没有评测,走向拥有可信赖的评测。可以把它视为评测驱动的 Agent 开发路线图:尽早定义成功、明确衡量成功,并持续迭代。
This section lays out our practical, field-tested advice for going from no evals to evals you can trust. Think of this as a roadmap for eval-driven agent development: define success early, measure it clearly, and iterate continuously.
为初始评测数据集收集任务
Collect tasks for the initial eval dataset
第 0 步:尽早开始
Step 0. Start early
我们看到一些团队迟迟不建设评测,因为他们认为需要数百个任务。实际上,从真实失败中提取 20—50 个简单任务,就是很好的起点。毕竟,在 Agent 开发早期,对系统的每次改动通常都会带来清晰、明显的影响;效应量较大,意味着较小的样本量就足够。更成熟的 Agent 可能需要规模更大、难度更高的评测,才能检测到较小的效果变化,但初期最好采用二八原则。拖得越久,评测就越难建设。早期,产品需求可以自然地转化为测试用例;等得太久,你就只能从一个正在运行的系统中反向推导成功标准。
We see teams delay building evals because they think they need hundreds of tasks. In reality, 20-50 simple tasks drawn from real failures is a great start. After all, in early agent development, each change to the system often has a clear, noticeable impact, and this large effect size means small sample sizes suffice. More mature agents may need larger, more difficult evals to detect smaller effects, but it’s best to take the 80/20 approach in the beginning. Evals get harder to build the longer you wait. Early on, product requirements naturally translate into test cases. Wait too long and you're reverse-engineering success criteria from a live system.
第 1 步:从你已经在手动测试的内容入手
Step 1. Start with what you already test manually
从开发过程中执行的手动检查开始:每次发布前都会验证的行为,以及最终用户经常尝试的任务。如果产品已经上线,就查看缺陷跟踪系统和客服工单队列。将用户报告的失败转化为测试用例,能确保评测套件反映真实使用情况;按对用户的影响排序,则能帮助你把精力投入最有价值的地方。
Begin with the manual checks you run during development—the behaviors you verify before each release and common tasks end users try. If you're already in production, look at your bug tracker and support queue. Converting user-reported failures into test cases ensures your suite reflects actual usage; prioritizing by user impact helps you invest effort where it counts.
第 2 步:编写没有歧义的任务,并提供参考解法
Step 2: Write unambiguous tasks with reference solutions
把任务质量做好,比看起来更难。一个好任务,应当让两位领域专家各自独立判断时,都能得出相同的通过/失败结论。他们自己能完成这个任务吗?如果不能,任务就需要改进。任务说明中的歧义会变成指标中的噪声。基于模型的评分器也一样:模糊的评分细则会产生不一致的判断。
Getting task quality right is harder than it seems. A good task is one where two domain experts would independently reach the same pass/fail verdict. Could they pass the task themselves? If not, the task needs refinement. Ambiguity in task specifications becomes noise in metrics. The same applies to criteria for model-based graders: vague rubrics produce inconsistent judgments.
每个任务都应该能够被正确遵循指令的 Agent 完成。其中的问题有时很细微。例如,对 Terminal-Bench 的审查发现:如果任务要求 Agent 编写一个脚本,却没有指定文件路径,而测试又假定脚本位于某个特定路径,那么 Agent 可能并没有做错,却仍然失败。评分器检查的所有内容,都应当能从任务描述中明确得知;不应因说明有歧义而判定 Agent 失败。对于前沿模型,如果多次试验的通过率都是 0%(即 pass@100 为 0%),往往意味着任务本身有问题,而不是 Agent 能力不足;此时应重新仔细检查任务说明和评分器。为每项任务创建一个参考解法很有用,即一个已知可行、能通过全部评分器的输出。这能证明任务确实可解,并验证评分器配置正确。
Each task should be passable by an agent that follows instructions correctly. This can be subtle. For instance, auditing Terminal-Bench revealed that if a task asks the agent to write a script but doesn’t specify a filepath, and the tests assume a particular filepath for the script, the agent might fail through no fault of its own. Everything the grader checks should be clear from the task description; agents shouldn’t fail due to ambiguous specs. With frontier models, a 0% pass rate across many trials (i.e. 0% pass@100) is most often a signal of a broken task, not an incapable agent, and a sign to double-check your task specification and graders. For each task, it’s useful to create a reference solution: a known working output that passes all graders. This proves that the task is solvable and verifies graders are correctly configured.
第 3 步:构建均衡的问题集
Step 3: Build balanced problem sets
既要测试某种行为应该发生的情况,也要测试它不应该发生的情况。单边评测会导致单边优化。例如,如果你只测试 Agent 在该搜索时是否搜索,最终可能得到一个几乎事事都搜索的 Agent。应尽量避免类别不均衡的评测。我们在为 Claude.ai 的网页搜索构建评测时,亲身体会到了这一点。挑战在于:既要防止模型在不该搜索时搜索,又要保留它在适当情况下开展深入研究的能力。团队构建了覆盖两个方向的评测:一类是模型应当搜索的查询,例如查询天气;另一类是模型应根据已有知识回答的查询,例如“谁创立了苹果公司?”。在触发不足(该搜索却不搜索)和过度触发(不该搜索却搜索)之间找到合适的平衡很难,需要对提示词和评测进行多轮改进。随着更多问题样例出现,我们还会继续补充评测,以扩大覆盖范围。
Test both the cases where a behavior should occur and where it shouldn't. One-sided evals create one-sided optimization. For instance, if you only test whether the agent searches when it should, you might end up with an agent that searches for almost everything. Try to avoid class-imbalanced evals. We learned this firsthand when building evals for web search in Claude.ai. The challenge was preventing the model from searching when it shouldn’t, while preserving its ability to do extensive research when appropriate. The team built evals covering both directions: queries where the model should search (like finding the weather) and queries where it should answer from existing knowledge (like “who founded Apple?”). Striking the right balance between undertriggering (not searching when it should) or overtriggering (searching when it shouldn’t) was difficult, and took many rounds of refinements to both the prompts and the eval. As more example problems come up, we continue to add to evals to improve our coverage.
设计评测运行框架与评分器
Design the eval harness and graders
第 4 步:构建稳健的评测运行框架,并提供稳定环境
Step 4: Build a robust eval harness with a stable environment
评测中的 Agent 应当与生产环境中的 Agent 以大致相同的方式运行,而且环境本身不能引入额外噪声,这一点至关重要。每次试验都应从干净的环境开始,做到彼此“隔离”。不同运行之间不必要的共享状态,例如残留文件、缓存数据、资源耗尽,可能引发相关性失败;这些失败来自基础设施的不稳定,而非 Agent 本身的表现。共享状态也可能人为抬高成绩。例如,在一些内部评测中,我们发现 Claude 通过查看先前试验留下的 git 历史,在某些任务上获得了不公平的优势。如果多个不同试验都因同一种环境限制而失败,例如 CPU 内存有限,那么它们就不是独立试验,因为受到了同一个因素的影响;此时,用这些评测结果衡量 Agent 表现就不可靠。
It’s essential that the agent in the eval functions roughly the same as the agent used in production, and that the environment itself doesn’t introduce further noise. Each trial should be “isolated” by starting from a clean environment. Unnecessary shared state between runs (leftover files, cached data, resource exhaustion) can cause correlated failures due to infrastructure flakiness rather than agent performance. Shared state can also artificially inflate performance. For example, in some internal evals we observed Claude gaining an unfair advantage on some tasks by examining the git history from previous trials. If multiple distinct trials fail because of the same limitation in the environment (like limited CPU memory), these trials are not independent because they’re affected by the same factor, and the eval results become unreliable for measuring agent performance.
第 5 步:认真设计评分器
Step 5: Design graders thoughtfully
如前所述,优秀的评测设计,需要为 Agent 和任务选择最合适的评分器。我们建议:能用确定性评分器时优先使用;必要时,或需要额外灵活性时,使用 LLM 评分器;再有选择地采用人工评分,进行补充验证。
As discussed above, great eval design involves choosing the best graders for the agent and the tasks. We recommend choosing deterministic graders where possible, LLM graders where necessary or for additional flexibility, and using human graders judiciously for additional validation.
人们常会本能地检查 Agent 是否遵循了非常具体的步骤,例如是否按正确顺序调用了一系列工具。我们发现这种方法过于僵化,会让测试变得十分脆弱,因为 Agent 经常能找到评测设计者没有预料到的有效方法。为了避免不必要地惩罚创造性,通常更好的做法是评价 Agent 产出了什么,而不是它走了哪条路径。
There is a common instinct to check that agents followed very specific steps like a sequence of tool calls in the right order. We’ve found this approach too rigid and results in overly brittle tests, as agents regularly find valid approaches that eval designers didn’t anticipate. So as not to unnecessarily punish creativity, it’s often better to grade what the agent produced, not the path it took.
对于包含多个组成部分的任务,应当设置部分得分。一个正确识别了问题、验证了客户身份,但未能完成退款的客服 Agent,显然比一开始就失败的 Agent 更好。结果应当体现这种成功程度的连续变化。
For tasks with multiple components, build in partial credit. A support agent that correctly identifies the problem and verifies the customer but fails to process a refund is meaningfully better than one that fails immediately. It’s important to represent this continuum of success in results.
模型评分往往需要认真迭代,才能验证其准确性。充当裁判的 LLM(LLM-as-judge)评分器应与人类专家密切校准,以确信人工评分和模型评分之间的偏差很小。为避免幻觉,要给 LLM 留出退路,例如指示它在信息不足时返回“Unknown”。为任务的每个维度制定清晰、结构化的评分细则,也会有所帮助;然后,让独立的 LLM 裁判分别评价各个维度,而不是由一个裁判评价所有维度。系统稳定可靠后,只需偶尔进行人工复核即可。
Model grading often takes careful iteration to validate accuracy. LLM-as-judge graders should be closely calibrated with human experts to gain confidence that there is little divergence between the human grading and model grading. To avoid hallucinations, give the LLM a way out, like providing an instruction to return “Unknown” when it doesn’t have enough information. It can also help to create clear, structured rubrics to grade each dimension of a task, and then grade each dimension with an isolated LLM-as-judge rather than using one to grade all dimensions. Once the system is robust, it’s sufficient to use human review only occasionally.
有些评测存在隐蔽的失效方式,即便 Agent 表现不错,也会得到低分:评分缺陷、Agent 运行框架的限制或歧义,使 Agent 无法完成任务。即使经验丰富的团队也可能漏掉这些问题。例如,Opus 4.5 最初在 CORE-Bench 上只得到 42%,后来一位 Anthropic 研究人员发现了多处问题:评分过于死板,在期望值为“96.124991…”时,会把“96.12”判为错误;任务说明有歧义;还有无法精确复现的随机性任务。修复缺陷并采用限制更少的运行框架之后,Opus 4.5 的得分跃升至 95%。类似地,METR 发现,其时间跨度基准中有几项任务配置有误:任务要求 Agent 优化到指定分数阈值,但评分却要求超过该阈值。这使 Claude 等遵循指令的模型受到了惩罚,反而是忽略既定目标的模型得分更高。认真复查任务和评分器,有助于避免这些问题。
Some evaluations have subtle failure modes that result in low scores even with good agent performance, as the agent fails to solve tasks due to grading bugs, agent harness constraints, or ambiguity. Even sophisticated teams can miss these issues. For example, Opus 4.5 initially scored 42% on CORE-Bench, until an Anthropic researcher found multiple issues: rigid grading that penalized “96.12” when expecting “96.124991…”, ambiguous task specs, and stochastic tasks that were impossible to reproduce exactly. After fixing bugs and using a less constrained scaffold, Opus 4.5’s score jumped to 95%. Similarly, METR discovered several misconfigured tasks in their time horizon benchmark that asked agents to optimize to a stated score threshold, but the grading required exceeding that threshold. This penalized models like Claude for following the instructions, while models that ignored the stated goal received better scores. Carefully double-checking tasks and graders can help avoid these problems.
要让评分器能够抵御绕过或投机取巧。Agent 不应轻易就能在评测中“作弊”。任务和评分器的设计应确保:要通过评测,就必须真正解决问题,而不能利用非预期的漏洞。
Make your graders resistant to bypasses or hacks. The agent shouldn’t be able to easily “cheat” the eval. Tasks and graders should be designed so that passing genuinely requires solving the problem rather than exploiting unintended loopholes.
长期维护和使用评测
Maintain and use the eval long-term
第 6 步:检查完整记录
Step 6: Check the transcripts
如果不阅读大量试验的完整记录和评分,你就无法知道评分器是否运行良好。在 Anthropic,我们投入资源开发了查看评测完整记录的工具,并定期花时间阅读这些记录。任务失败时,完整记录能告诉你:到底是 Agent 真正犯了错,还是评分器拒绝了一个有效的解决方案。它通常还会揭示 Agent 和评测行为中的关键细节。
You won't know if your graders are working well unless you read the transcripts and grades from many trials. At Anthropic, we invested in tooling for viewing eval transcripts and we regularly take the time to read them. When a task fails, the transcript tells you whether the agent made a genuine mistake or whether your graders rejected a valid solution. It also often surfaces key details about agent and eval behavior.
失败的判定应当让人觉得公平:Agent 哪里做错了、为什么错,都应清晰可见。当分数不再提高时,我们需要确信原因在于 Agent 的表现,而不是评测本身。阅读完整记录,正是验证评测是否在衡量真正重要的东西的方法,也是 Agent 开发的一项关键技能。
Failures should seem fair: it’s clear what the agent got wrong and why. When scores don’t climb, we need confidence that it’s due to agent performance and not the eval. Reading transcripts is how you verify that your eval is measuring what actually matters, and is a critical skill for agent development.
第 7 步:留意能力评测是否趋于饱和
Step 7: Monitor for capability eval saturation
通过率为 100% 的评测能够跟踪回归,但不能提供改进信号。当 Agent 通过了所有可解任务,不再有提升空间时,就发生了评测饱和。例如,SWE-Bench Verified 的分数在今年年初还是 30%,而现在前沿模型已超过 80%,正逐渐接近饱和。随着评测接近饱和,由于只剩最难的任务,进展也会放缓。这可能让结果具有误导性:很大的能力提升,在分数上却只体现为很小的增长。例如,代码审查初创公司 Qodo 最初并未觉得 Opus 4.5 的表现有多突出,因为他们的单次作答式编程评测没有捕捉到它在更长、更复杂任务上的进步。为此,他们开发了一套新的 Agent 式评测框架,从而更清楚地看到了能力进展。
An eval at 100% tracks regressions but provides no signal for improvement. Eval saturation occurs when an agent passes all of the solvable tasks, leaving no room for improvement. For instance, SWE-Bench Verified scores started at 30% this year, and frontier models are now nearing saturation at >80%. As evals approach saturation, progress will also slow, as only the most difficult tasks remain. This can make results deceptive, as large capability improvements appear as small increases in scores. For example, the code review startup Qodo was initially unimpressed by Opus 4.5 because their one-shot coding evals didn’t capture the gains on longer, more complex tasks. In response, they developed a new agentic eval framework, providing a much clearer picture of progress.
我们的原则是:在有人深入查看评测细节、阅读一些完整记录之前,不会仅凭分数表面就接受评测结论。如果评分不公平、任务含糊不清、有效解法受到惩罚,或者运行框架限制了模型,就应该修订评测。
As a rule, we do not take eval scores at face value until someone digs into the details of the eval and reads some transcripts. If grading is unfair, tasks are ambiguous, valid solutions are penalized, or the harness constrains the model, the eval should be revised.
第 8 步:通过开放贡献和持续维护,让评测套件长期保持有效
Step 8: Keep evaluation suites healthy long-term through open contribution and maintenance
评测套件是一项不断演进的成果,需要持续投入精力,并明确责任归属,才能一直发挥作用。
An eval suite is a living artifact that needs ongoing attention and clear ownership to remain useful.
在 Anthropic,我们尝试过多种维护评测的方法。事实证明,最有效的方式是设立专门的评测团队,负责核心基础设施;与此同时,由领域专家和产品团队贡献大多数评测任务,并自行运行评测。
At Anthropic, we experimented with various approaches to eval maintenance. What proved most effective was establishing dedicated evals teams to own the core infrastructure, while domain experts and product teams contribute most eval tasks and run the evaluations themselves.
对于 AI 产品团队,负责和迭代评测应当像维护单元测试一样日常。团队可能在一些 AI 功能上浪费数周:它们在早期测试中“能用”,却无法满足那些没有明说的预期,而设计良好的评测原本可以及早揭示这些预期。定义评测任务,是检验产品需求是否已经具体到足以开始开发的最佳方法之一。
For AI product teams, owning and iterating on evaluations should be as routine as maintaining unit tests. Teams can waste weeks on AI features that “work” in early testing but fail to meet unstated expectations that a well-designed eval would have surfaced early. Defining eval tasks is one of the best ways to stress-test whether the product requirements are concrete enough to start building.
我们建议采用评测驱动开发:在 Agent 尚不能实现计划中的能力之前,就先构建评测来定义这些能力,然后持续迭代,直到 Agent 表现良好。在内部,我们经常构建一些当下表现只是“够用”的功能,同时押注模型几个月后能实现的能力。初始通过率较低的能力评测,能让这些押注清晰可见。当新模型发布时,运行评测套件,就能迅速看出哪些押注得到了回报。
We recommend practicing eval-driven development: build evals to define planned capabilities before agents can fulfill them, then iterate until the agent performs well. Internally, we often build features that work “well enough” today but are bets on what models can do in a few months. Capability evals that start at a low pass rate make this visible. When a new model drops, running the suite quickly reveals which bets paid off.
最接近产品需求和用户的人,最有条件定义成功。凭借当前模型的能力,产品经理、客户成功经理或销售人员都可以使用 Claude Code,通过 PR 贡献一个评测任务——让他们去做!更好的做法是,主动为他们提供支持。
The people closest to product requirements and users are best positioned to define success. With current model capabilities, product managers, customer success managers, or salespeople can use Claude Code to contribute an eval task as a PR—let them! Or, even better, actively enable them.
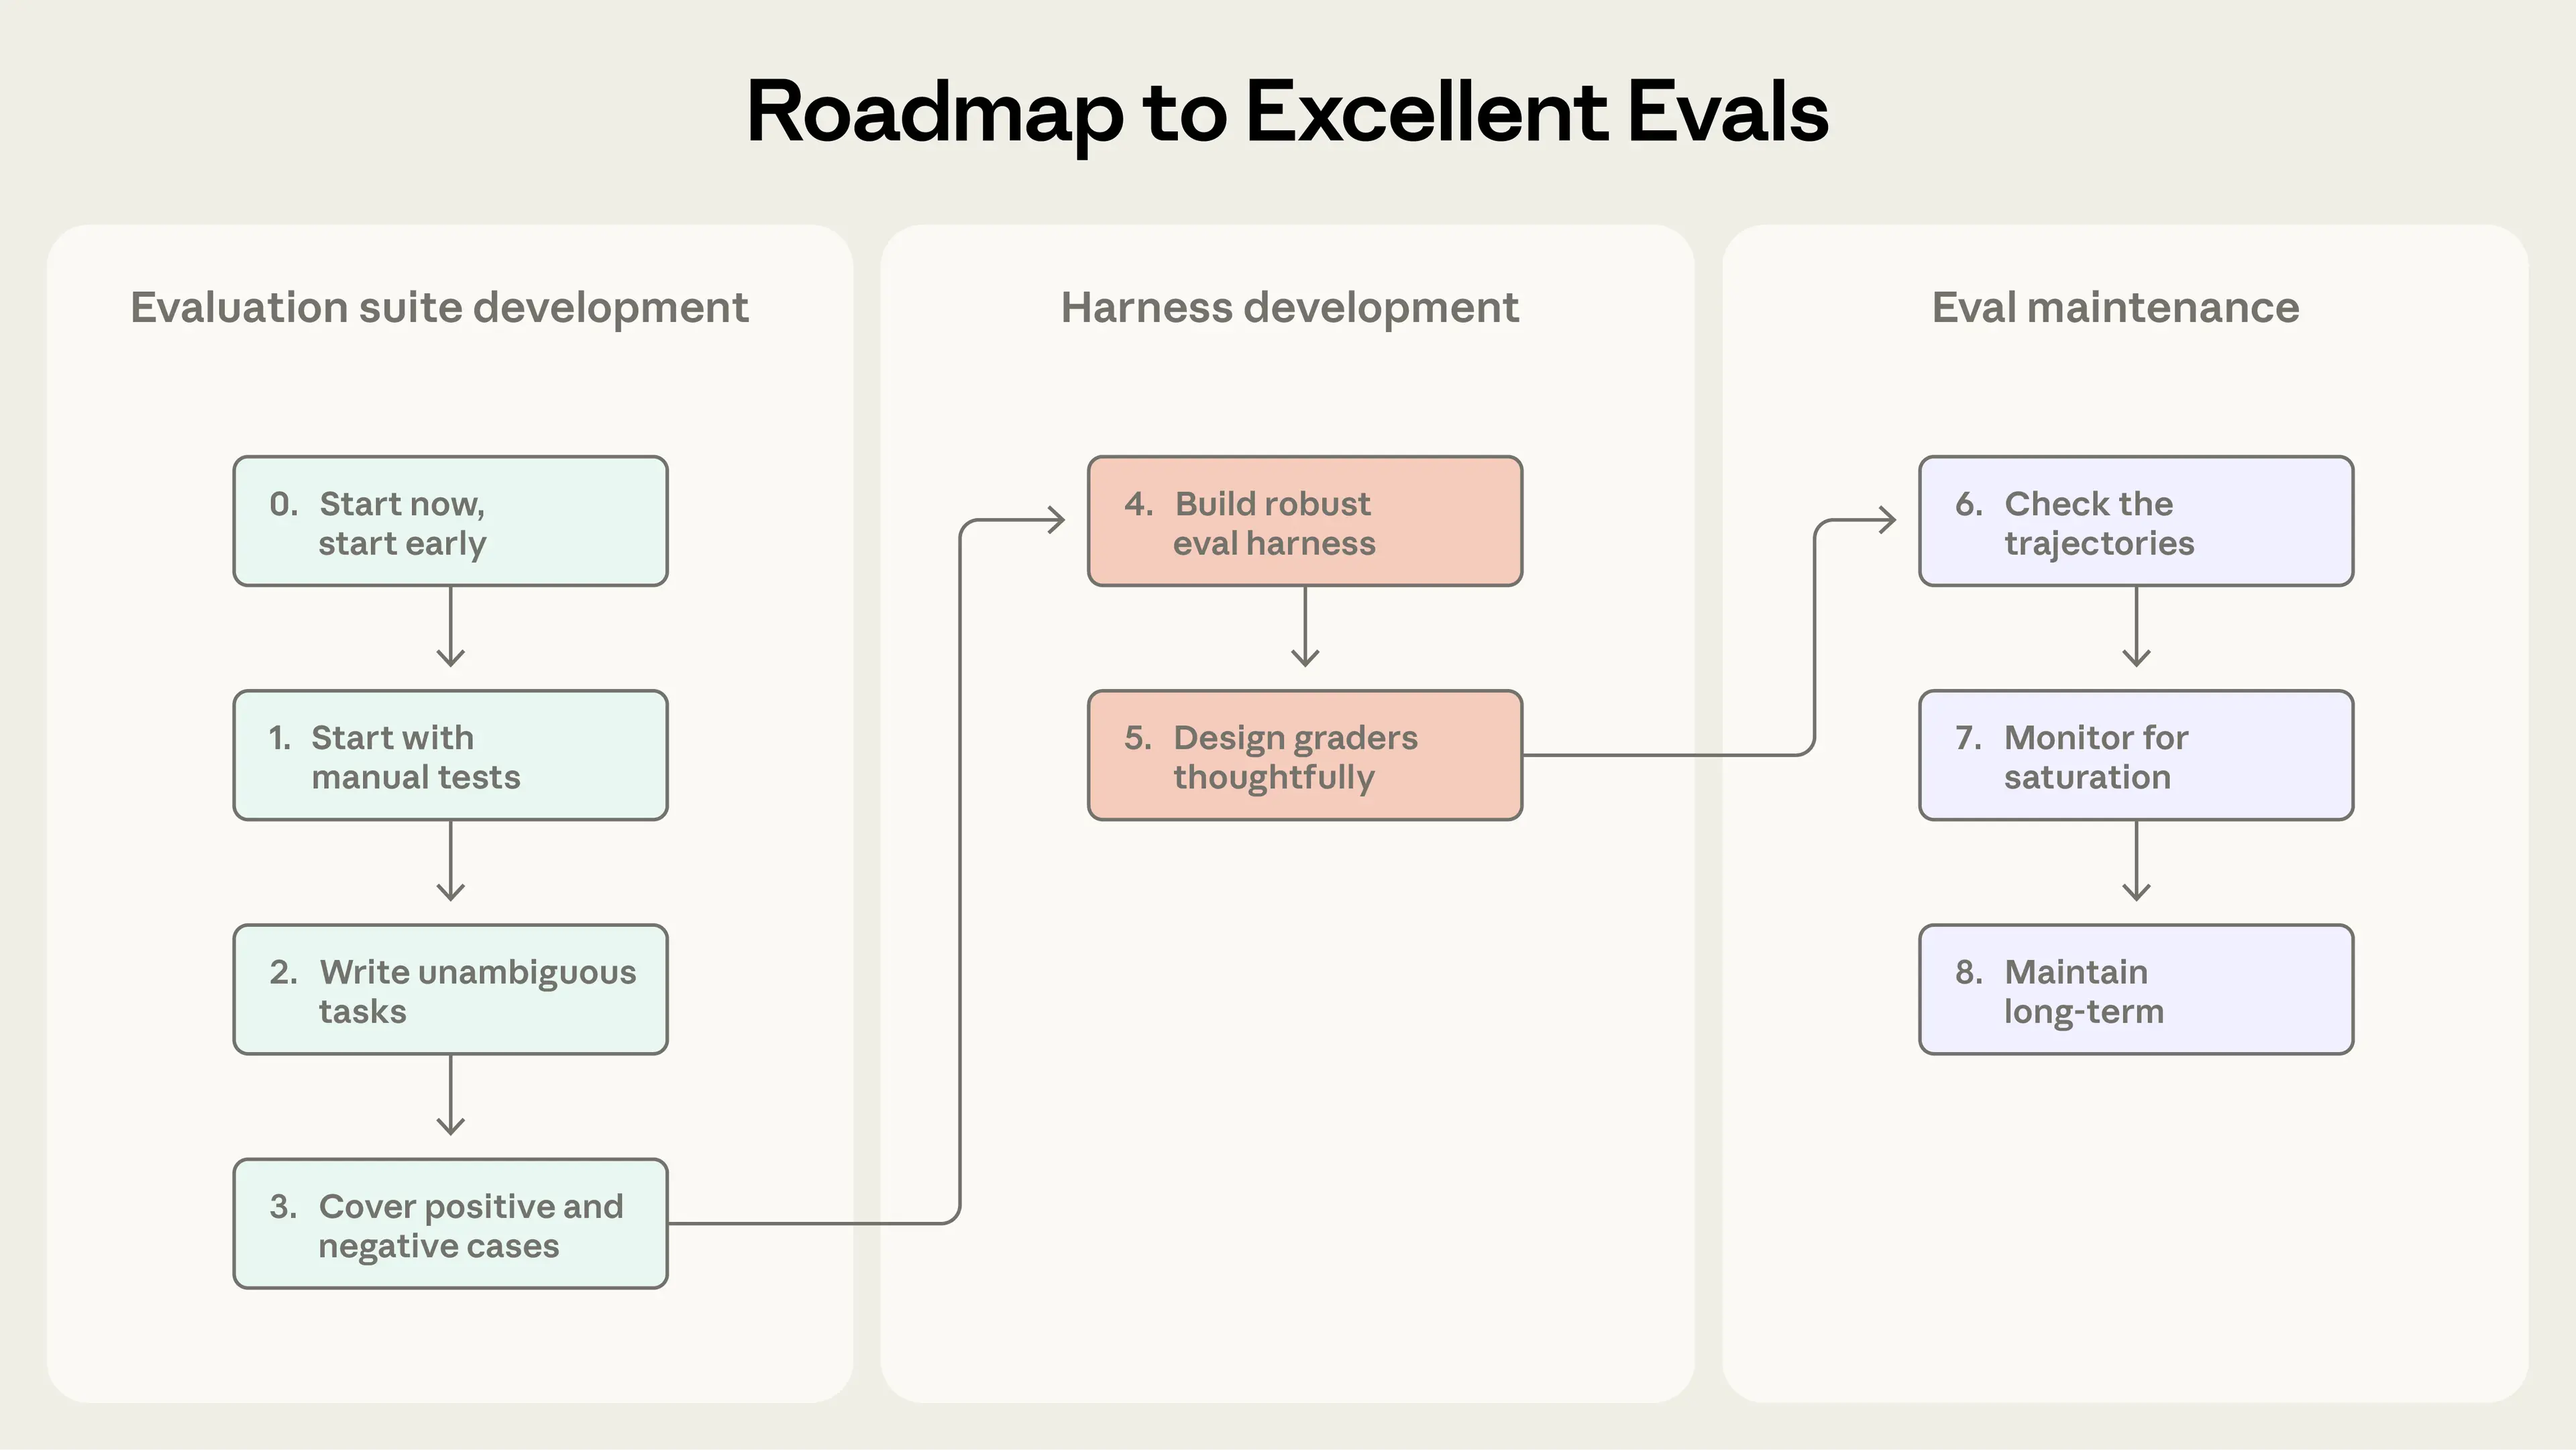
如何结合评测与其他方法,全面理解 Agent
How evals fit with other methods for a holistic understanding of agents
自动化评测无需把 Agent 部署到生产环境,也不会影响真实用户,就能让它运行数千项任务。但这只是了解 Agent 表现的众多方法之一。要得到完整认识,还需要生产监控、用户反馈、A/B 测试、人工审阅完整记录,以及系统性人工评估。
Automated evaluations can be run against an agent in thousands of tasks without deploying to production or affecting real users. But this is just one of many ways to understand agent performance. A complete picture includes production monitoring, user feedback, A/B testing, manual transcript review, and systematic human evaluation.
了解 AI Agent 表现的各种方法概览
An overview of approaches for understanding AI agent performance
这些方法对应 Agent 开发的不同阶段。自动化评测在上线前和 CI/CD 中尤其有用:每次修改 Agent 或升级模型时都运行,作为防范质量问题的第一道防线。生产监控在上线后开始发挥作用,用于检测分布漂移,以及事先没有预料到的真实世界故障。有了足够流量后,可以用 A/B 测试验证重要改动。用户反馈和完整记录审阅则是持续进行的实践,用于填补空白:不断分流处理反馈,每周抽样阅读完整记录,并根据需要深入调查。系统性的人类参与研究,则留给校准 LLM 评分器,或评价以人类共识为参照标准的主观性输出。
These methods map to different stages of agent development. Automated evals are especially useful pre-launch and in CI/CD, running on each agent change and model upgrade as the first line of defense against quality problems. Production monitoring kicks in post-launch to detect distribution drift and unanticipated real-world failures. A/B testing validates significant changes once you have sufficient traffic. User feedback and transcript review are ongoing practices to fill the gaps: triage feedback constantly, sample transcripts to read weekly, and dig deeper as needed. Reserve systematic human studies for calibrating LLM graders or evaluating subjective outputs where human consensus serves as the reference standard.
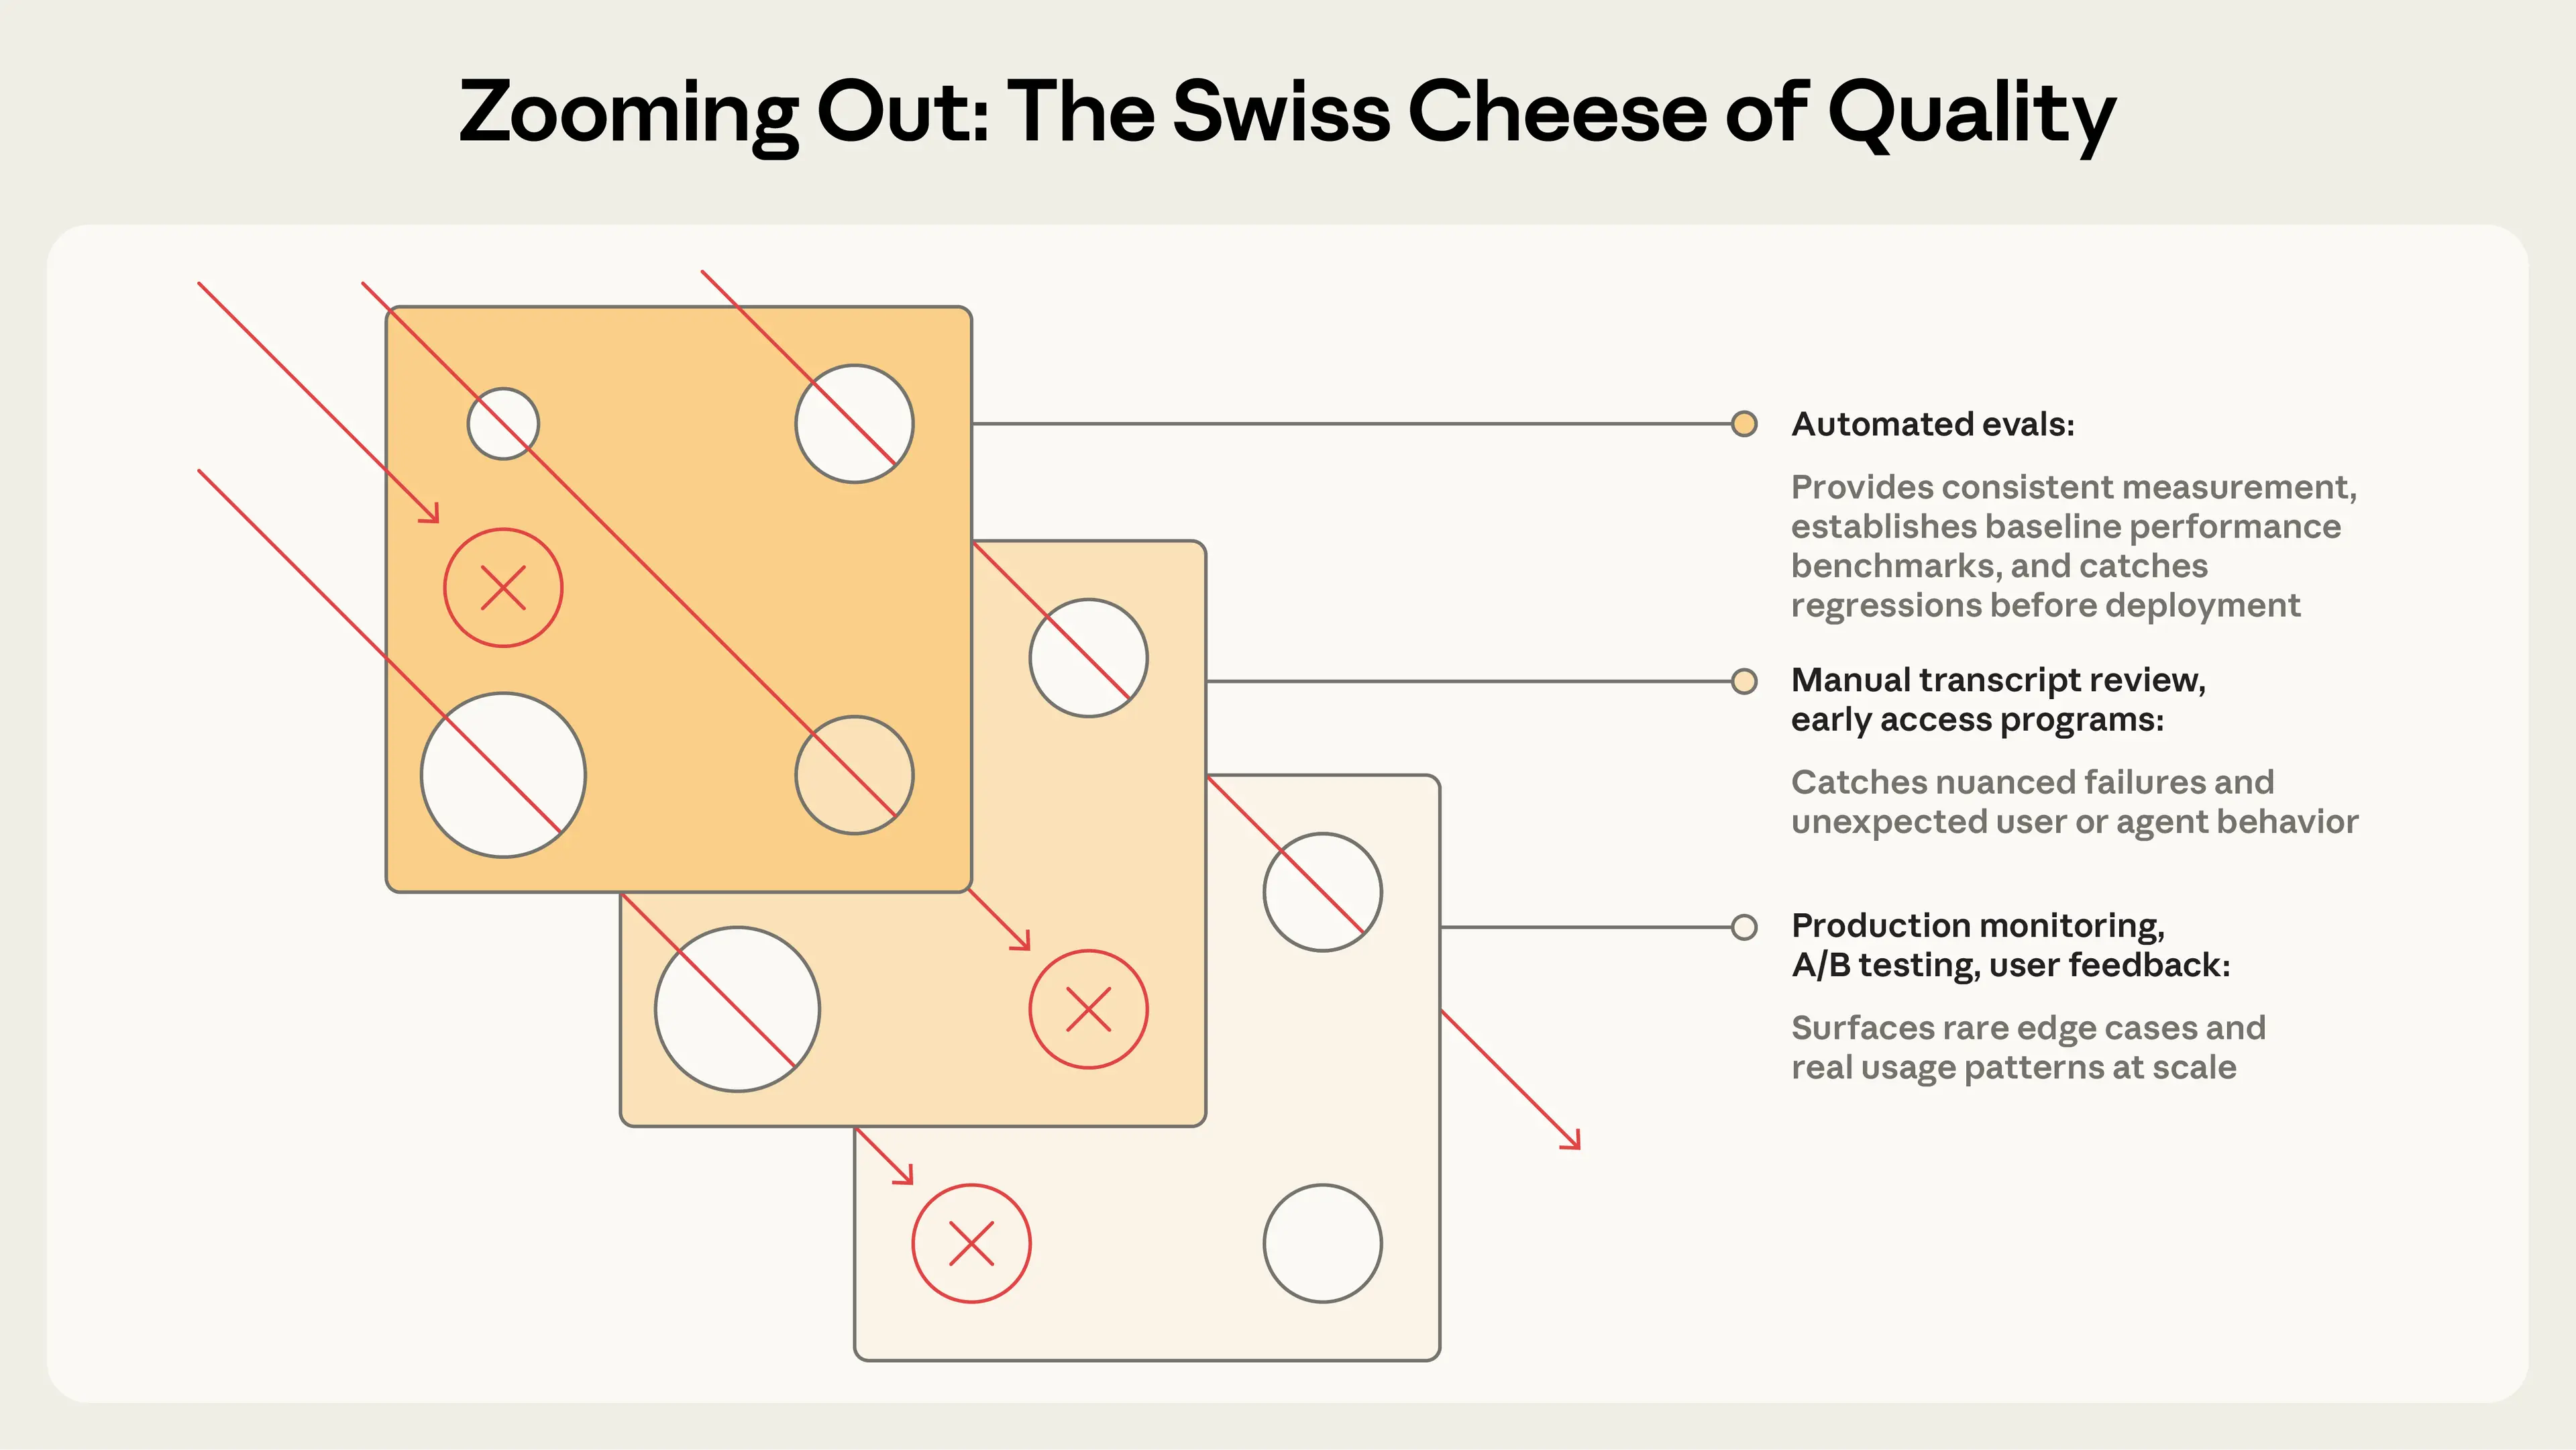
最有效的团队会结合这些方法:用自动化评测实现快速迭代,用生产监控了解实际表现,再通过定期人工复核进行校准。
The most effective teams combine these methods: automated evals for fast iteration, production monitoring for ground truth, and periodic human review for calibration.
结语
Conclusion
没有评测的团队,会困在被动应对的循环中:修复一个故障,又引发另一个故障,无法区分真正的退化与噪声。尽早投入评测的团队则会看到相反的结果:失败转化为测试用例,测试用例防止回归,指标取代猜测,开发因此加快。评测为整个团队提供了清晰的提升目标,让“Agent 感觉变差了”成为可以采取行动的问题。它的价值会不断累积,但前提是你把评测视为核心组成部分,而不是事后补上的东西。
Teams without evals get bogged down in reactive loops—fixing one failure, creating another, unable to distinguish real regressions from noise. Teams that invest early find the opposite: development accelerates as failures become test cases, test cases prevent regressions, and metrics replace guesswork. Evals give the whole team a clear hill to climb, turning “the agent feels worse” into something actionable. The value compounds, but only if you treat evals as a core component, not an afterthought.
不同类型的 Agent 所适用的具体方法各不相同,但本文介绍的基本原则是一致的。尽早开始,不要等待完美的评测套件。从你观察到的失败中提取真实任务。定义没有歧义、稳健的成功标准。认真设计评分器,并组合使用多种类型。确保问题对模型而言足够困难。持续迭代评测,提高其信噪比。务必阅读完整记录!
The patterns vary by agent type, but the fundamentals described here are constant. Start early and don’t wait for the perfect suite. Source realistic tasks from the failures you see. Define unambiguous, robust success criteria. Design graders thoughtfully and combine multiple types. Make sure the problems are hard enough for the model. Iterate on the evaluations to improve their signal-to-noise ratio. Read the transcripts!
AI Agent 评测仍然是一个处于起步阶段、快速发展的领域。随着 Agent 承担更长的任务、在多 Agent 系统中协作,以及处理越来越主观的工作,我们也需要调整技术方法。随着理解不断深入,我们会继续分享最佳实践。
AI agent evaluation is still a nascent, fast-evolving field. As agents take on longer tasks, collaborate in multi-agent systems, and handle increasingly subjective work, we will need to adapt our techniques. We’ll keep sharing best practices as we learn more.
致谢
Acknowledgements
本文由 Mikaela Grace、Jeremy Hadfield、Rodrigo Olivares 和 Jiri De Jonghe 撰写。我们还感谢 David Hershey、Gian Segato、Mike Merrill、Alex Shaw、Nicholas Carlini、Ethan Dixon、Pedram Navid、Jake Eaton、Alyssa Baum、Lina Tawfik、Karen Zhou、Alexander Bricken、Sam Kennedy、Robert Ying 及其他人的贡献。特别感谢在评测合作中让我们受益的客户与合作伙伴,包括 iGent、Cognition、Bolt、Sierra、Vals.ai、Macroscope、PromptLayer、Stripe、Shopify、Terminal Bench 团队等。这项工作体现了多个团队的共同努力,他们帮助推动了 Anthropic 评测实践的发展。
Written by Mikaela Grace, Jeremy Hadfield, Rodrigo Olivares, and Jiri De Jonghe. We're also grateful to David Hershey, Gian Segato, Mike Merrill, Alex Shaw, Nicholas Carlini, Ethan Dixon, Pedram Navid, Jake Eaton, Alyssa Baum, Lina Tawfik, Karen Zhou, Alexander Bricken, Sam Kennedy, Robert Ying, and others for their contributions. Special thanks to the customers and partners we have learned from through collaborating on evals, including iGent, Cognition, Bolt, Sierra, Vals.ai, Macroscope, PromptLayer, Stripe, Shopify, the Terminal Bench team, and more. This work reflects the collective efforts of several teams who helped develop the practice of evaluations at Anthropic.
附录:评测框架
Appendix: Eval frameworks
一些开源和商业框架可以帮助团队实现 Agent 评测,无需从零搭建基础设施。如何选择,取决于 Agent 类型、现有技术栈,以及你需要离线评测、生产可观测性,还是两者兼备。
Harbor 专为在容器化环境中运行 Agent 而设计,提供了跨云服务商大规模运行试验的基础设施,以及定义任务和评分器的标准化格式。Terminal-Bench 2.0 等热门基准通过 Harbor registry 分发,因此很容易将成熟基准与自定义评测套件一起运行。
Braintrust 是一个将离线评测、生产可观测性与实验跟踪结合起来的平台,适合既需要在开发过程中迭代、又需要在生产环境中监控质量的团队。它的 `autoevals` 库包含针对事实性、相关性等常见维度的预置评分器。
LangSmith 提供执行轨迹追踪、离线与在线评测,以及数据集管理,并与 LangChain 生态紧密集成。Langfuse 提供类似能力,是一种可自行托管的开源替代方案,适用于有数据驻留要求的团队。
Several open-source and commercial frameworks can help teams implement agent evaluations without building infrastructure from scratch. The right choice depends on your agent type, existing stack, and whether you need offline evaluation, production observability, or both.
Harbor is designed for running agents in containerized environments, with infrastructure for running trials at scale across cloud providers and a standardized format for defining tasks and graders. Popular benchmarks like Terminal-Bench 2.0 ship through the Harbor registry, making it easy to run established benchmarks along with custom eval suites.
Braintrust is a platform that combines offline evaluation with production observability and experiment tracking—useful for teams that need to both iterate during development and monitor quality in production. Its `autoevals` library includes pre-built scorers for factuality, relevance, and other common dimensions.
LangSmith offers tracing, offline and online evaluations, and dataset management with tight integration into the LangChain ecosystem. Langfuse provides similar capabilities as a self-hosted open-source alternative for teams with data residency requirements.
Arize 提供 Phoenix,这是一个用于 LLM 执行轨迹追踪、调试,以及离线或在线评测的开源平台;它还提供 AX,一项在 Phoenix 基础上扩展了规模化、优化和监控能力的 SaaS 服务。
许多团队会组合使用多种工具,自建评测框架,或者仅以简单的评测脚本作为起点。我们的体会是:框架虽然能够有效加速进展、促进标准化,但它们的效果终究取决于其中运行的评测任务。通常,最好的做法是迅速选定一个适合工作流程的框架,再把精力投入评测本身,不断打磨高质量的测试用例和评分器。
Arize offers Phoenix, an open-source platform for LLM tracing, debugging, and offline or online evaluations, and AX, a SaaS offering that extends Phoenix for scale, optimization and monitoring.
Many teams combine multiple tools, roll their own eval framework, or just use simple evaluation scripts as a starting point. We find that while frameworks can be a valuable way to accelerate progress and standardize, they’re only as good as the eval tasks you run through them. It’s often best to quickly pick a framework that fits your workflow, then invest your energy in the evals themselves by iterating on high-quality test cases and graders.
— 全文完 —
原文来自 Anthropic,中文为非官方学习译文。
查看原始出处 ↗