
2025/7/18 --Yichao 'Peak' Ji
2025/7/18 --Yichao 'Peak' Ji
At the very beginning of the Manus project, my team and I faced a key decision: should we train an end-to-end agentic model using open-source foundations, or build an agent on top of the in-context learning abilities of frontier models?
在我从事自然语言处理的第一个十年里,我们没有这样的选择余地。在遥远的 BERT 时代——没错,已经过去七年了——模型必须经过微调与评测,才能迁移到新任务。即使当时的模型比今天的大语言模型小得多,每轮迭代也往往需要数周。对于快速发展的应用,尤其是尚未找到产品与市场匹配点的阶段,如此缓慢的反馈循环是无法接受的。这是我上一次创业时得到的惨痛教训:当时我从零训练模型,用于开放信息抽取和语义搜索。随后,GPT-3 和 Flan-T5 出现,我的自研模型一夜之间失去了意义。讽刺的是,也正是这些模型,开启了上下文学习,以及一条全新的前进道路。
Back in my first decade in NLP, we didn't have the luxury of that choice. In the distant days of BERT (yes, it's been seven years), models had to be fine-tuned—and evaluated—before they could transfer to a new task. That process often took weeks per iteration, even though the models were tiny compared to today's LLMs. For fast-moving applications, especially pre–PMF, such slow feedback loops are a deal-breaker. That was a bitter lesson from my last startup, where I trained models from scratch for open information extraction and semantic search. Then came GPT-3 and Flan-T5, and my in-house models became irrelevant overnight. Ironically, those same models marked the beginning of in-context learning—and a whole new path forward.
这堂来之不易的课,让选择变得明确:Manus 要押注上下文工程。它让我们可以用数小时而非数周交付改进,并让产品与底层模型保持解耦:如果模型进步是不断上涨的潮水,我们希望 Manus 是船,而不是固定在海床上的柱子。
That hard-earned lesson made the choice clear: Manus would bet on context engineering. This allows us to ship improvements in hours instead of weeks, and kept our product orthogonal to the underlying models: If model progress is the rising tide, we want Manus to be the boat, not the pillar stuck to the seabed.
不过,事实证明,上下文工程一点也不简单。它是一门实验科学。我们已经重建了四次 Agent 框架,每一次都是因为发现了更好的上下文塑造方式。我们亲切地将这种手工进行架构搜索、调整提示词和凭经验试探的过程,称为“随机研究生下降”(Stochastic Graduate Descent)。它不优雅,但确实有效。
Still, context engineering turned out to be anything but straightforward. It's an experimental science—and we've rebuilt our agent framework four times, each time after discovering a better way to shape context. We affectionately refer to this manual process of architecture searching, prompt fiddling, and empirical guesswork as "Stochastic Graduate Descent". It's not elegant, but it works.
本文分享我们通过自己的“SGD”找到的局部最优解。如果你正在构建自己的 AI Agent,希望这些原则能帮助你更快收敛。
This post shares the local optima we arrived at through our own "SGD". If you're building your own AI agent, I hope these principles help you converge faster.
围绕 KV 缓存进行设计
Design Around the KV-Cache
如果只能选择一个指标,我会认为,KV 缓存命中率是生产阶段 AI Agent 最重要的单一指标。它直接影响时延与成本。要理解原因,先看看一个典型 Agent 是如何运行的:
If I had to choose just one metric, I'd argue that the KV-cache hit rate is the single most important metric for a production-stage AI agent. It directly affects both latency and cost. To understand why, let's look at how a typical agent operates:
接收到用户输入后,Agent 会通过一连串工具使用来完成任务。在每次迭代中,模型根据当前上下文,从预定义的动作空间中选择一个动作。随后,在环境中执行这个动作,例如 Manus 的虚拟机沙箱,并产生一项观测。动作和观测被追加到上下文,形成下一次迭代的输入。这个循环持续进行,直到任务完成。
After receiving a user input, the agent proceeds through a chain of tool uses to complete the task. In each iteration, the model selects an action from a predefined action space based on the current context. That action is then executed in the environment (e.g., Manus's virtual machine sandbox) to produce an observation. The action and observation are appended to the context, forming the input for the next iteration. This loop continues until the task is complete.
可以想象,上下文会随着每一步不断增长,而输出通常是结构化的函数调用,仍然相对简短。因此,与聊天机器人相比,Agent 的预填充与解码之间的比例明显失衡。例如,Manus 的平均输入与输出 token 比例约为 100:1。
As you can imagine, the context grows with every step, while the output—usually a structured function call—remains relatively short. This makes the ratio between prefilling and decoding highly skewed in agents compared to chatbots. In Manus, for example, the average input-to-output token ratio is around 100:1.
好在,前缀相同的上下文可以利用 KV 缓存,大幅降低首 token 时间(TTFT)与推理成本,无论你使用的是自托管模型,还是调用推理 API。而且,这不是小幅节省:以 Claude Sonnet 为例,已缓存的输入 token 价格为每百万 token 0.30 美元,未缓存的价格为每百万 token 3 美元,相差 10 倍。
Fortunately, contexts with identical prefixes can take advantage of KV-cache, which drastically reduces time-to-first-token (TTFT) and inference cost—whether you're using a self-hosted model or calling an inference API. And we're not talking about small savings: with Claude Sonnet, for instance, cached input tokens cost 0.30 USD/MTok, while uncached ones cost 3 USD/MTok—a 10x difference.
从上下文工程的角度看,提高 KV 缓存命中率需要几项关键实践:
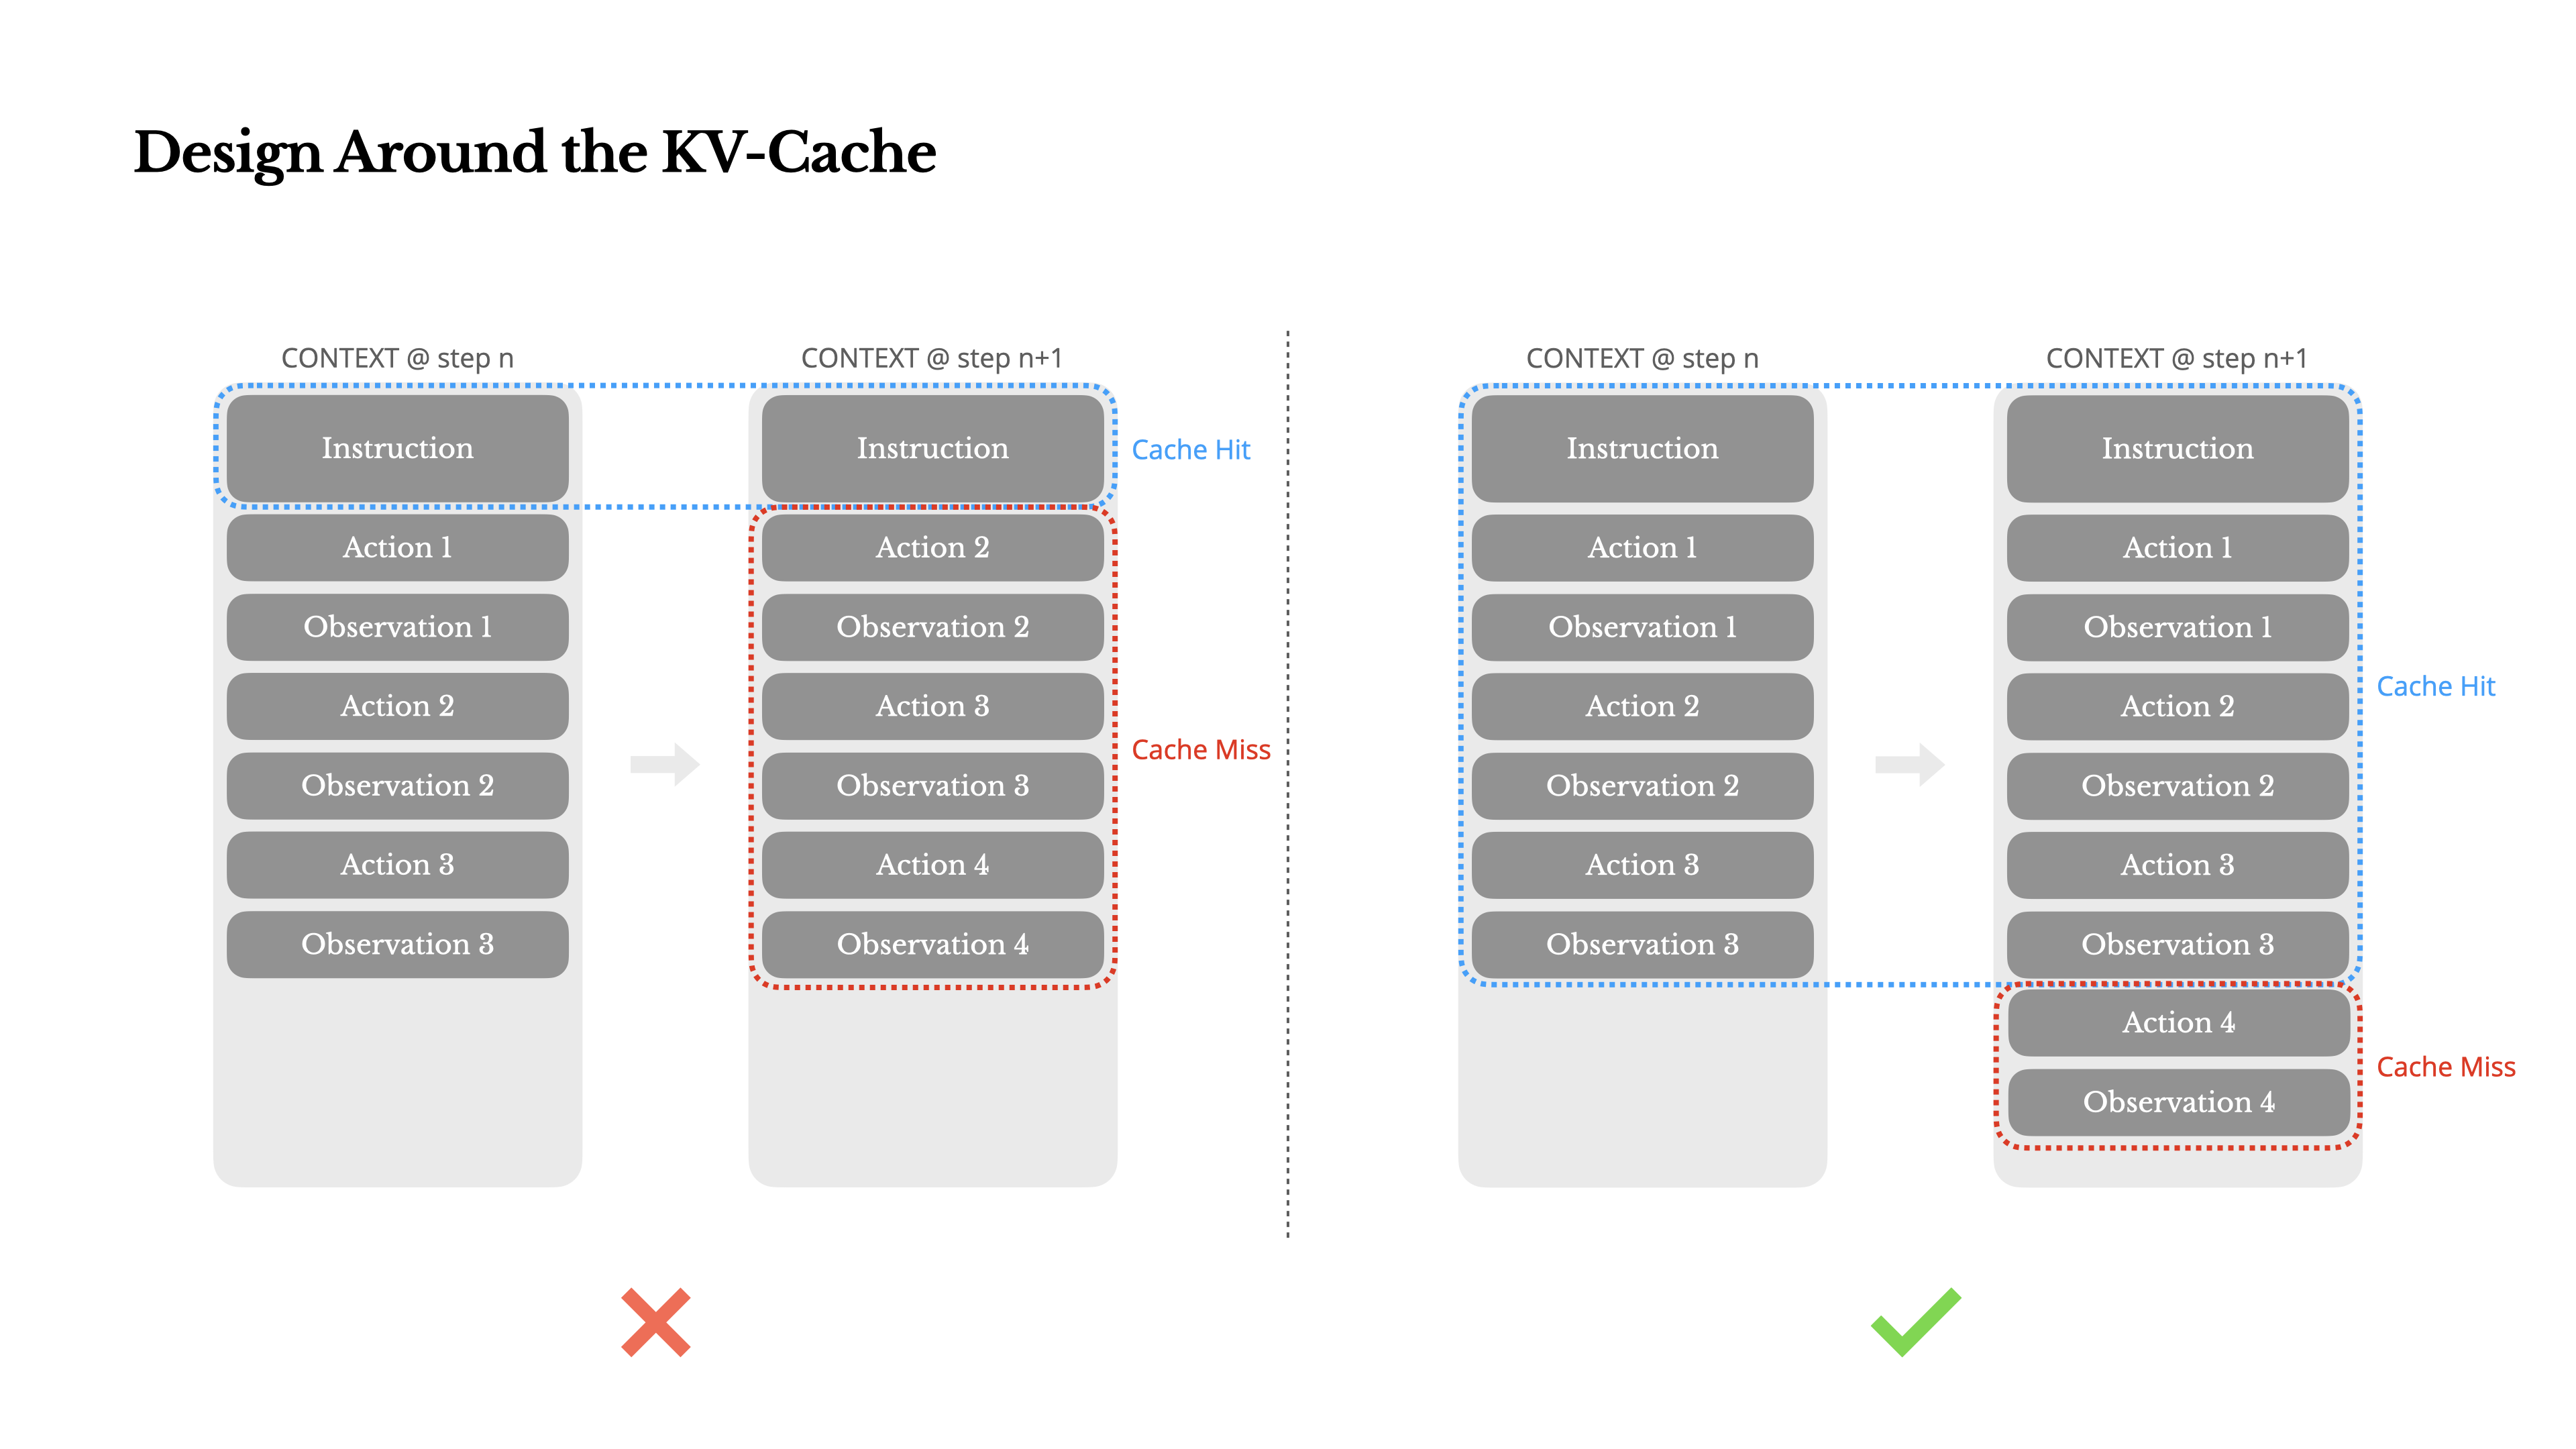
From a context engineering perspective, improving KV-cache hit rate involves a few key practices:
- 保持提示词前缀稳定。由于大语言模型具有自回归特性,即使只有一个 token 不同,也可能使从该 token 开始的后续缓存失效。一个常见错误,是在系统提示词开头加入时间戳,尤其是精确到秒的时间戳。没错,它能让模型告诉你当前时间,但也会摧毁缓存命中率。
- 让上下文只追加、不修改。避免修改此前的动作或观测。确保序列化具有确定性。许多编程语言和库在序列化 JSON 对象时,并不保证键的顺序稳定,这可能悄无声息地破坏缓存。
- 必要时显式标记缓存断点。某些模型供应商或推理框架不支持自动增量前缀缓存,而要求在上下文中手动插入缓存断点。设置断点时,要考虑缓存可能过期的情况,并至少确保断点覆盖到系统提示词的末尾。
- Keep your prompt prefix stable. Due to the autoregressive nature of LLMs, even a single-token difference can invalidate the cache from that token onward. A common mistake is including a timestamp—especially one precise to the second—at the beginning of the system prompt. Sure, it lets the model tell you the current time, but it also kills your cache hit rate.
- Make your context append-only. Avoid modifying previous actions or observations. Ensure your serialization is deterministic. Many programming languages and libraries don't guarantee stable key ordering when serializing JSON objects, which can silently break the cache.
- Mark cache breakpoints explicitly when needed. Some model providers or inference frameworks don't support automatic incremental prefix caching, and instead require manual insertion of cache breakpoints in the context. When assigning these, account for potential cache expiration and at minimum, ensure the breakpoint includes the end of the system prompt.
Additionally, if you're self-hosting models using frameworks like vLLM, make sure prefix/prompt caching is enabled, and that you're using techniques like session IDs to route requests consistently across distributed workers.
屏蔽,而不是移除
Mask, Don't Remove
随着 Agent 获得更多能力,它的动作空间自然会变得更加复杂。说得直白些,就是工具数量爆炸式增长。最近 MCP 的流行,更是火上浇油。如果允许用户自行配置工具,相信我:总会有人往你精心整理的动作空间里,塞进数百个来历不明的工具。结果是,模型更容易选择错误动作,或走上低效路径。简而言之,你那全副武装的 Agent 反而变笨了。
As your agent takes on more capabilities, its action space naturally grows more complex—in plain terms, the number of tools explodes. The recent popularity of MCP only adds fuel to the fire. If you allow user-configurable tools, trust me: someone will inevitably plug hundreds of mysterious tools into your carefully curated action space. As a result, the model is more likely to select the wrong action or take an inefficient path. In short, your heavily armed agent gets dumber.
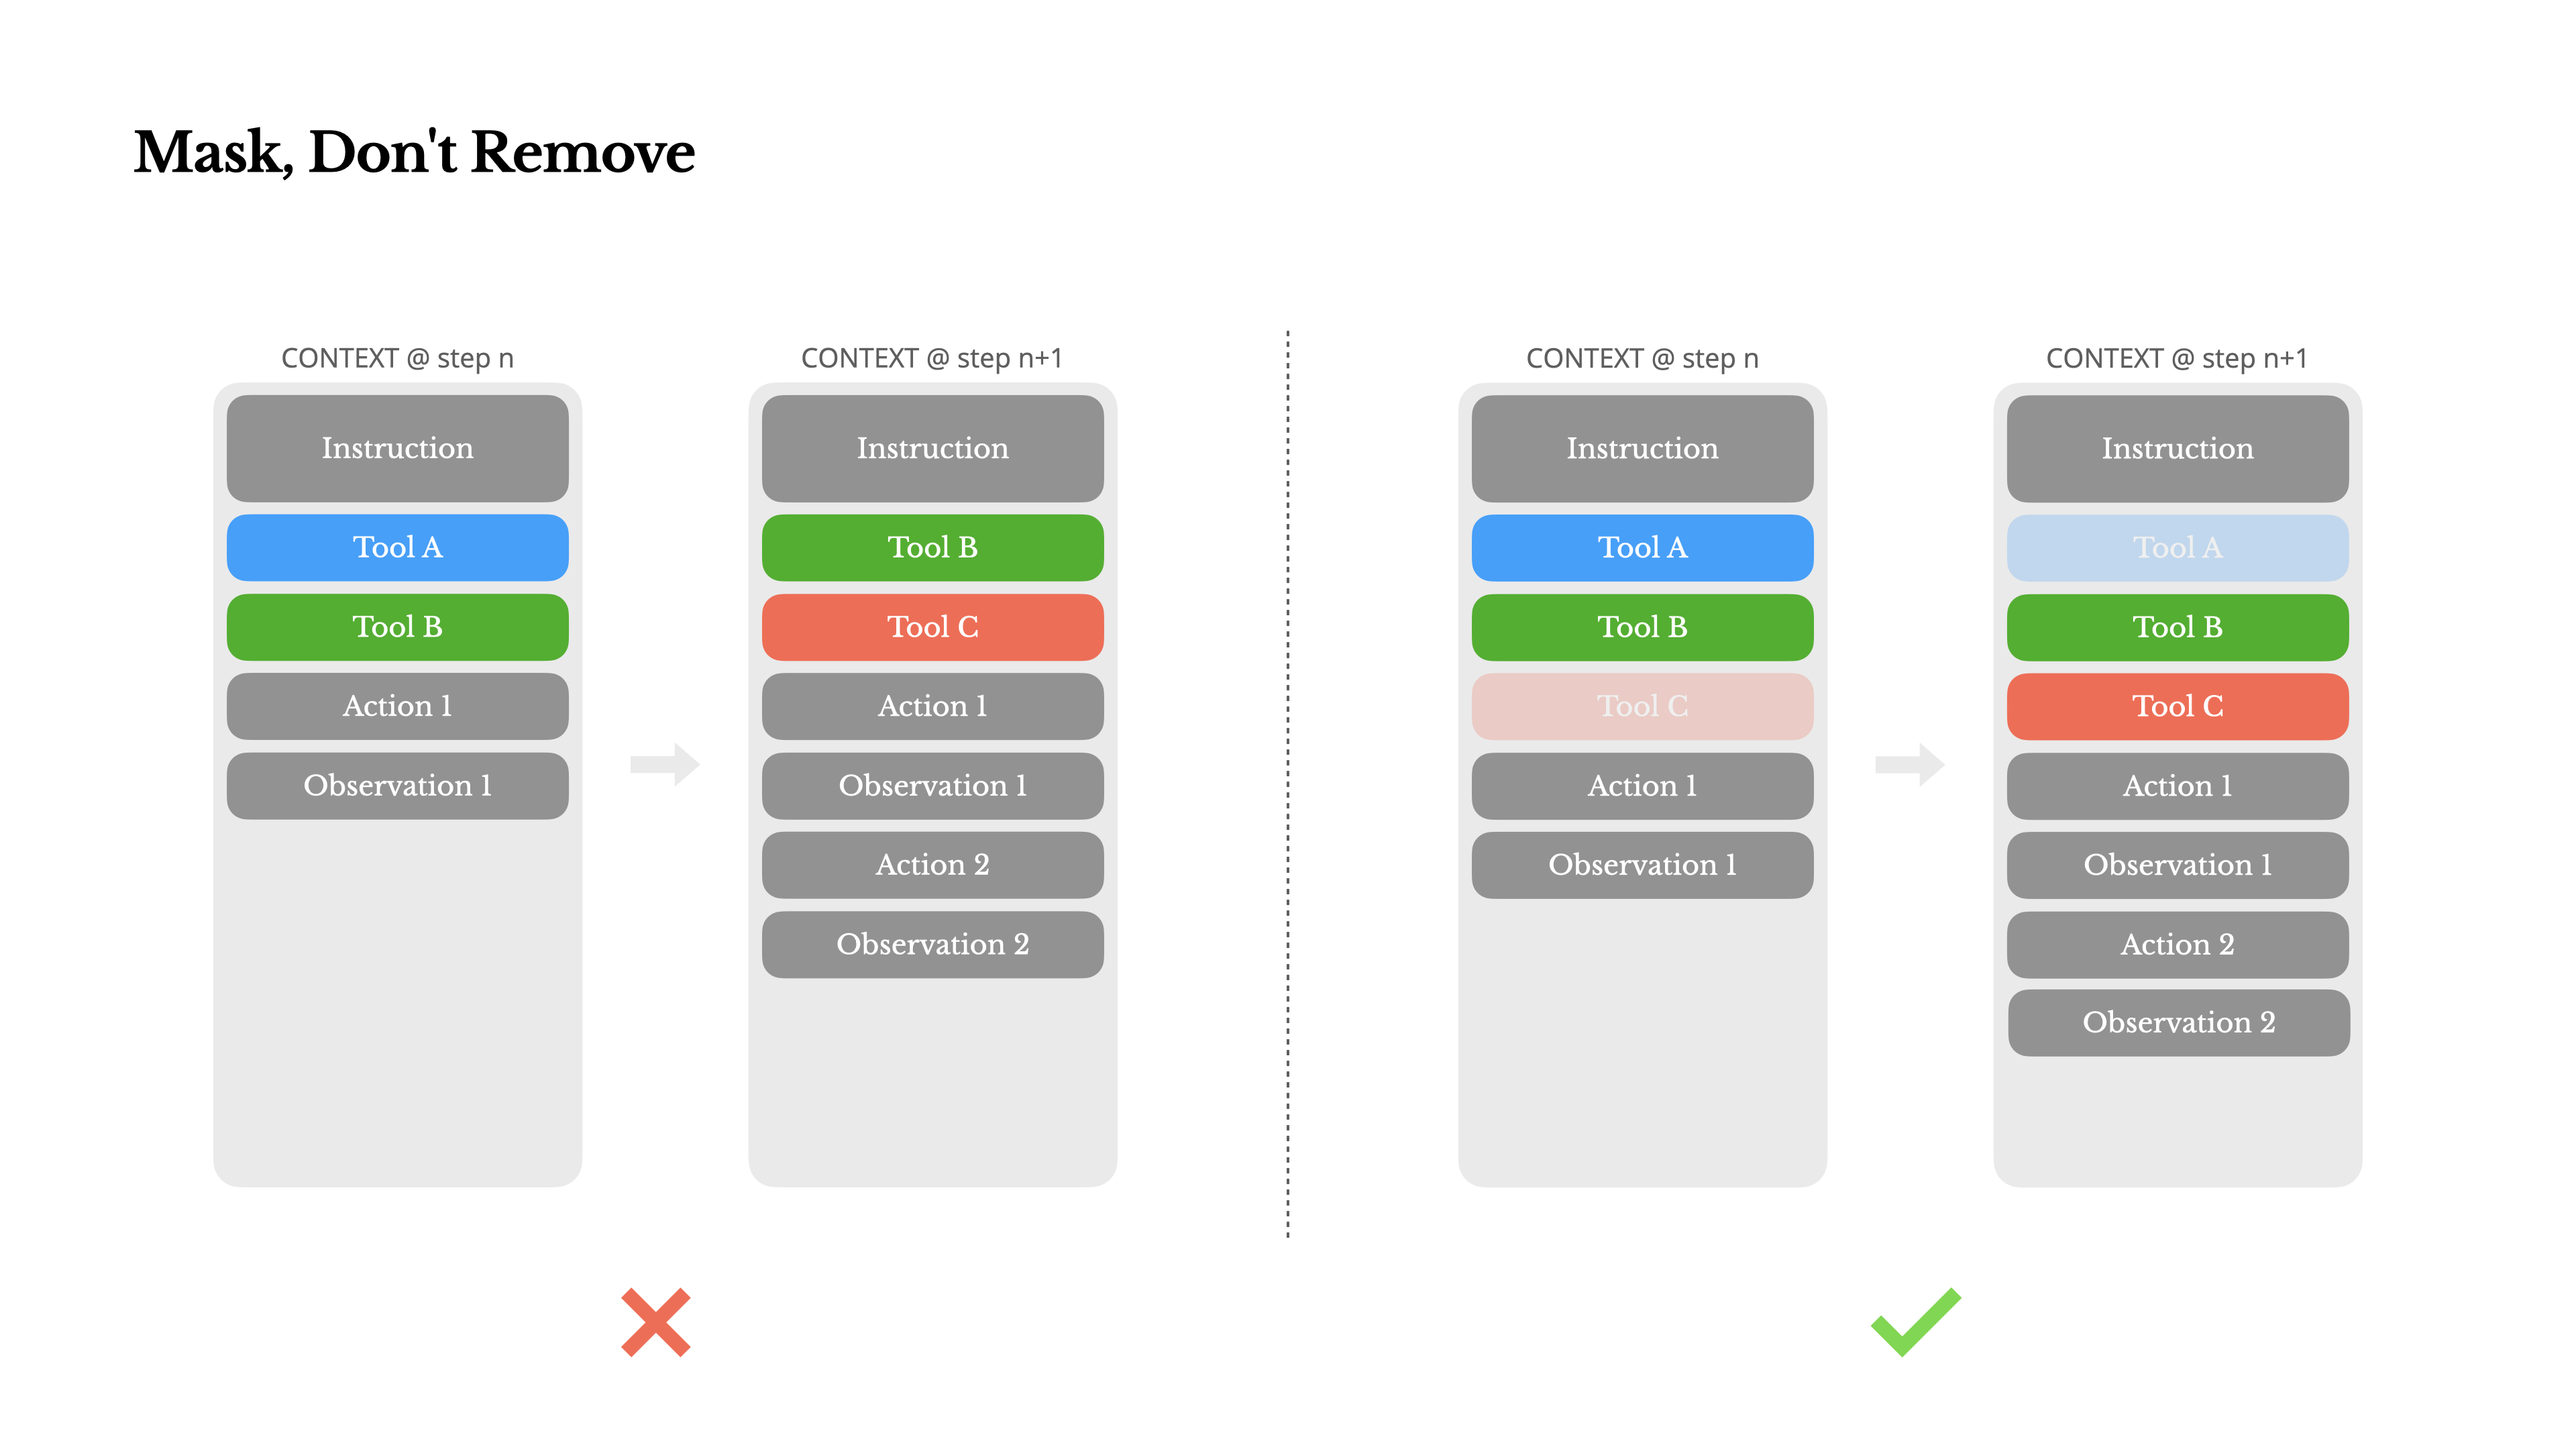
一个自然的反应,是设计动态动作空间,比如用类似 RAG 的方法按需加载工具。我们在 Manus 中也尝试过。但实验指向一条明确原则:除非绝对必要,否则避免在迭代过程中动态添加或移除工具。主要有两个原因:
A natural reaction is to design a dynamic action space—perhaps loading tools on demand using something RAG-like. We tried that in Manus too. But our experiments suggest a clear rule: unless absolutely necessary, avoid dynamically adding or removing tools mid-iteration. There are two main reasons for this:
- 在大多数大语言模型中,工具定义在序列化后位于上下文的前部,通常在系统提示词之前或之后。因此,任何改动都会使后续所有动作和观测对应的 KV 缓存失效。
- 如果此前的动作和观测仍然引用某些工具,但这些工具的定义已经不在当前上下文中,模型就会感到困惑。在没有约束解码的情况下,这往往导致违反 schema 或产生幻觉动作。
- In most LLMs, tool definitions live near the front of the context after serialization, typically before or after the system prompt. So any change will invalidate the KV-cache for all subsequent actions and observations.
- When previous actions and observations still refer to tools that are no longer defined in the current context, the model gets confused. Without constrained decoding, this often leads to schema violations or hallucinated actions.
为解决这一问题,同时改善动作选择,Manus 使用一个感知上下文的状态机来管理工具可用性。它不会移除工具,而是在解码时屏蔽 token 的 logits,根据当前上下文阻止或强制选择某些动作。
To solve this while still improving action selection, Manus uses a context-aware state machine to manage tool availability. Rather than removing tools, it masks the token logits during decoding to prevent (or enforce) the selection of certain actions based on the current context.
在实践中,大多数模型供应商和推理框架都支持某种形式的响应预填充,使你能够在不修改工具定义的情况下约束动作空间。函数调用通常有三种模式,下面以 NousResearch 的 Hermes 格式为例:
In practice, most model providers and inference frameworks support some form of response prefill, which allows you to constrain the action space without modifying the tool definitions. There are generally three modes of function calling (we'll use the Hermes format from NousResearch as an example):
- Auto:模型可以选择调用函数,也可以不调用。实现方式是只预填充回复前缀:
<|im_start|>assistant - Required:模型必须调用一个函数,但不限制选择哪个函数。实现方式是预填充到工具调用 token:
<|im_start|>assistant<tool_call> - Specified:模型必须从特定子集中选择一个函数调用。实现方式是预填充到函数名称的开头:
<|im_start|>assistant<tool_call>{"name": “browser_
- Auto – The model may choose to call a function or not. Implemented by prefilling only the reply prefix:
<|im_start|>assistant - Required – The model must call a function, but the choice is unconstrained. Implemented by prefilling up to tool call token:
<|im_start|>assistant<tool_call> - Specified – The model must call a function from a specific subset. Implemented by prefilling up to the beginning of the function name:
<|im_start|>assistant<tool_call>{"name": “browser_
利用这一机制,我们直接通过屏蔽 token 的 logits 来约束动作选择。例如,当用户提供新输入时,Manus 必须立即回复,而不是执行动作。我们还特意让动作名称采用一致的前缀:所有浏览器相关工具都以 browser_ 开头,命令行工具则以 shell_ 开头。这样,无需使用有状态的 logits 处理器,就能轻松强制 Agent 在特定状态下只从某一组工具中选择。
Using this, we constrain action selection by masking token logits directly. For example, when the user provides a new input, Manus must reply immediately instead of taking an action. We've also deliberately designed action names with consistent prefixes—e.g., all browser-related tools start with browser_, and command-line tools with shell_. This allows us to easily enforce that the agent only chooses from a certain group of tools at a given state without using stateful logits processors.
这些设计帮助 Manus 的 Agent 循环保持稳定,即使采用由模型驱动的架构也是如此。
These designs help ensure that the Manus agent loop remains stable—even under a model-driven architecture.
将文件系统用作上下文
Use the File System as Context
如今,前沿大语言模型已经提供 128K token 甚至更大的上下文窗口。但在真实的 Agent 场景中,这往往仍然不够,有时甚至会成为负担。常见的痛点有三个:
Modern frontier LLMs now offer context windows of 128K tokens or more. But in real-world agentic scenarios, that's often not enough, and sometimes even a liability. There are three common pain points:
- 观测可能非常庞大,尤其是在 Agent 与网页、PDF 等非结构化数据交互时,很容易超出上下文限制。
- 超过一定上下文长度后,模型表现往往会下降,即使从技术上说,上下文窗口仍能容纳这些内容。
- 长输入很昂贵,即使启用了前缀缓存,你仍然需要为每个 token 的传输和预填充付费。
- Observations can be huge, especially when agents interact with unstructured data like web pages or PDFs. It's easy to blow past the context limit.
- Model performance tends to degrade beyond a certain context length, even if the window technically supports it.
- Long inputs are expensive, even with prefix caching. You're still paying to transmit and prefill every token.
为此,许多 Agent 系统实现了上下文截断或压缩策略。但过于激进的压缩不可避免地会丢失信息。这个问题是根本性的:Agent 本质上必须根据此前所有状态预测下一步动作,而你无法可靠预测哪项观测会在十步之后变得至关重要。从逻辑上说,任何不可逆的压缩都存在风险。
To deal with this, many agent systems implement context truncation or compression strategies. But overly aggressive compression inevitably leads to information loss. The problem is fundamental: an agent, by nature, must predict the next action based on all prior state—and you can't reliably predict which observation might become critical ten steps later. From a logical standpoint, any irreversible compression carries risk.
因此,在 Manus 中,我们将文件系统视为终极上下文:大小没有限制,天然可以持久保存,而且 Agent 能直接操作。模型学会按需读写文件,将文件系统用于结构化的外部记忆,而不只是存储。
That's why we treat the file system as the ultimate context in Manus: unlimited in size, persistent by nature, and directly operable by the agent itself. The model learns to write to and read from files on demand—using the file system not just as storage, but as structured, externalized memory.
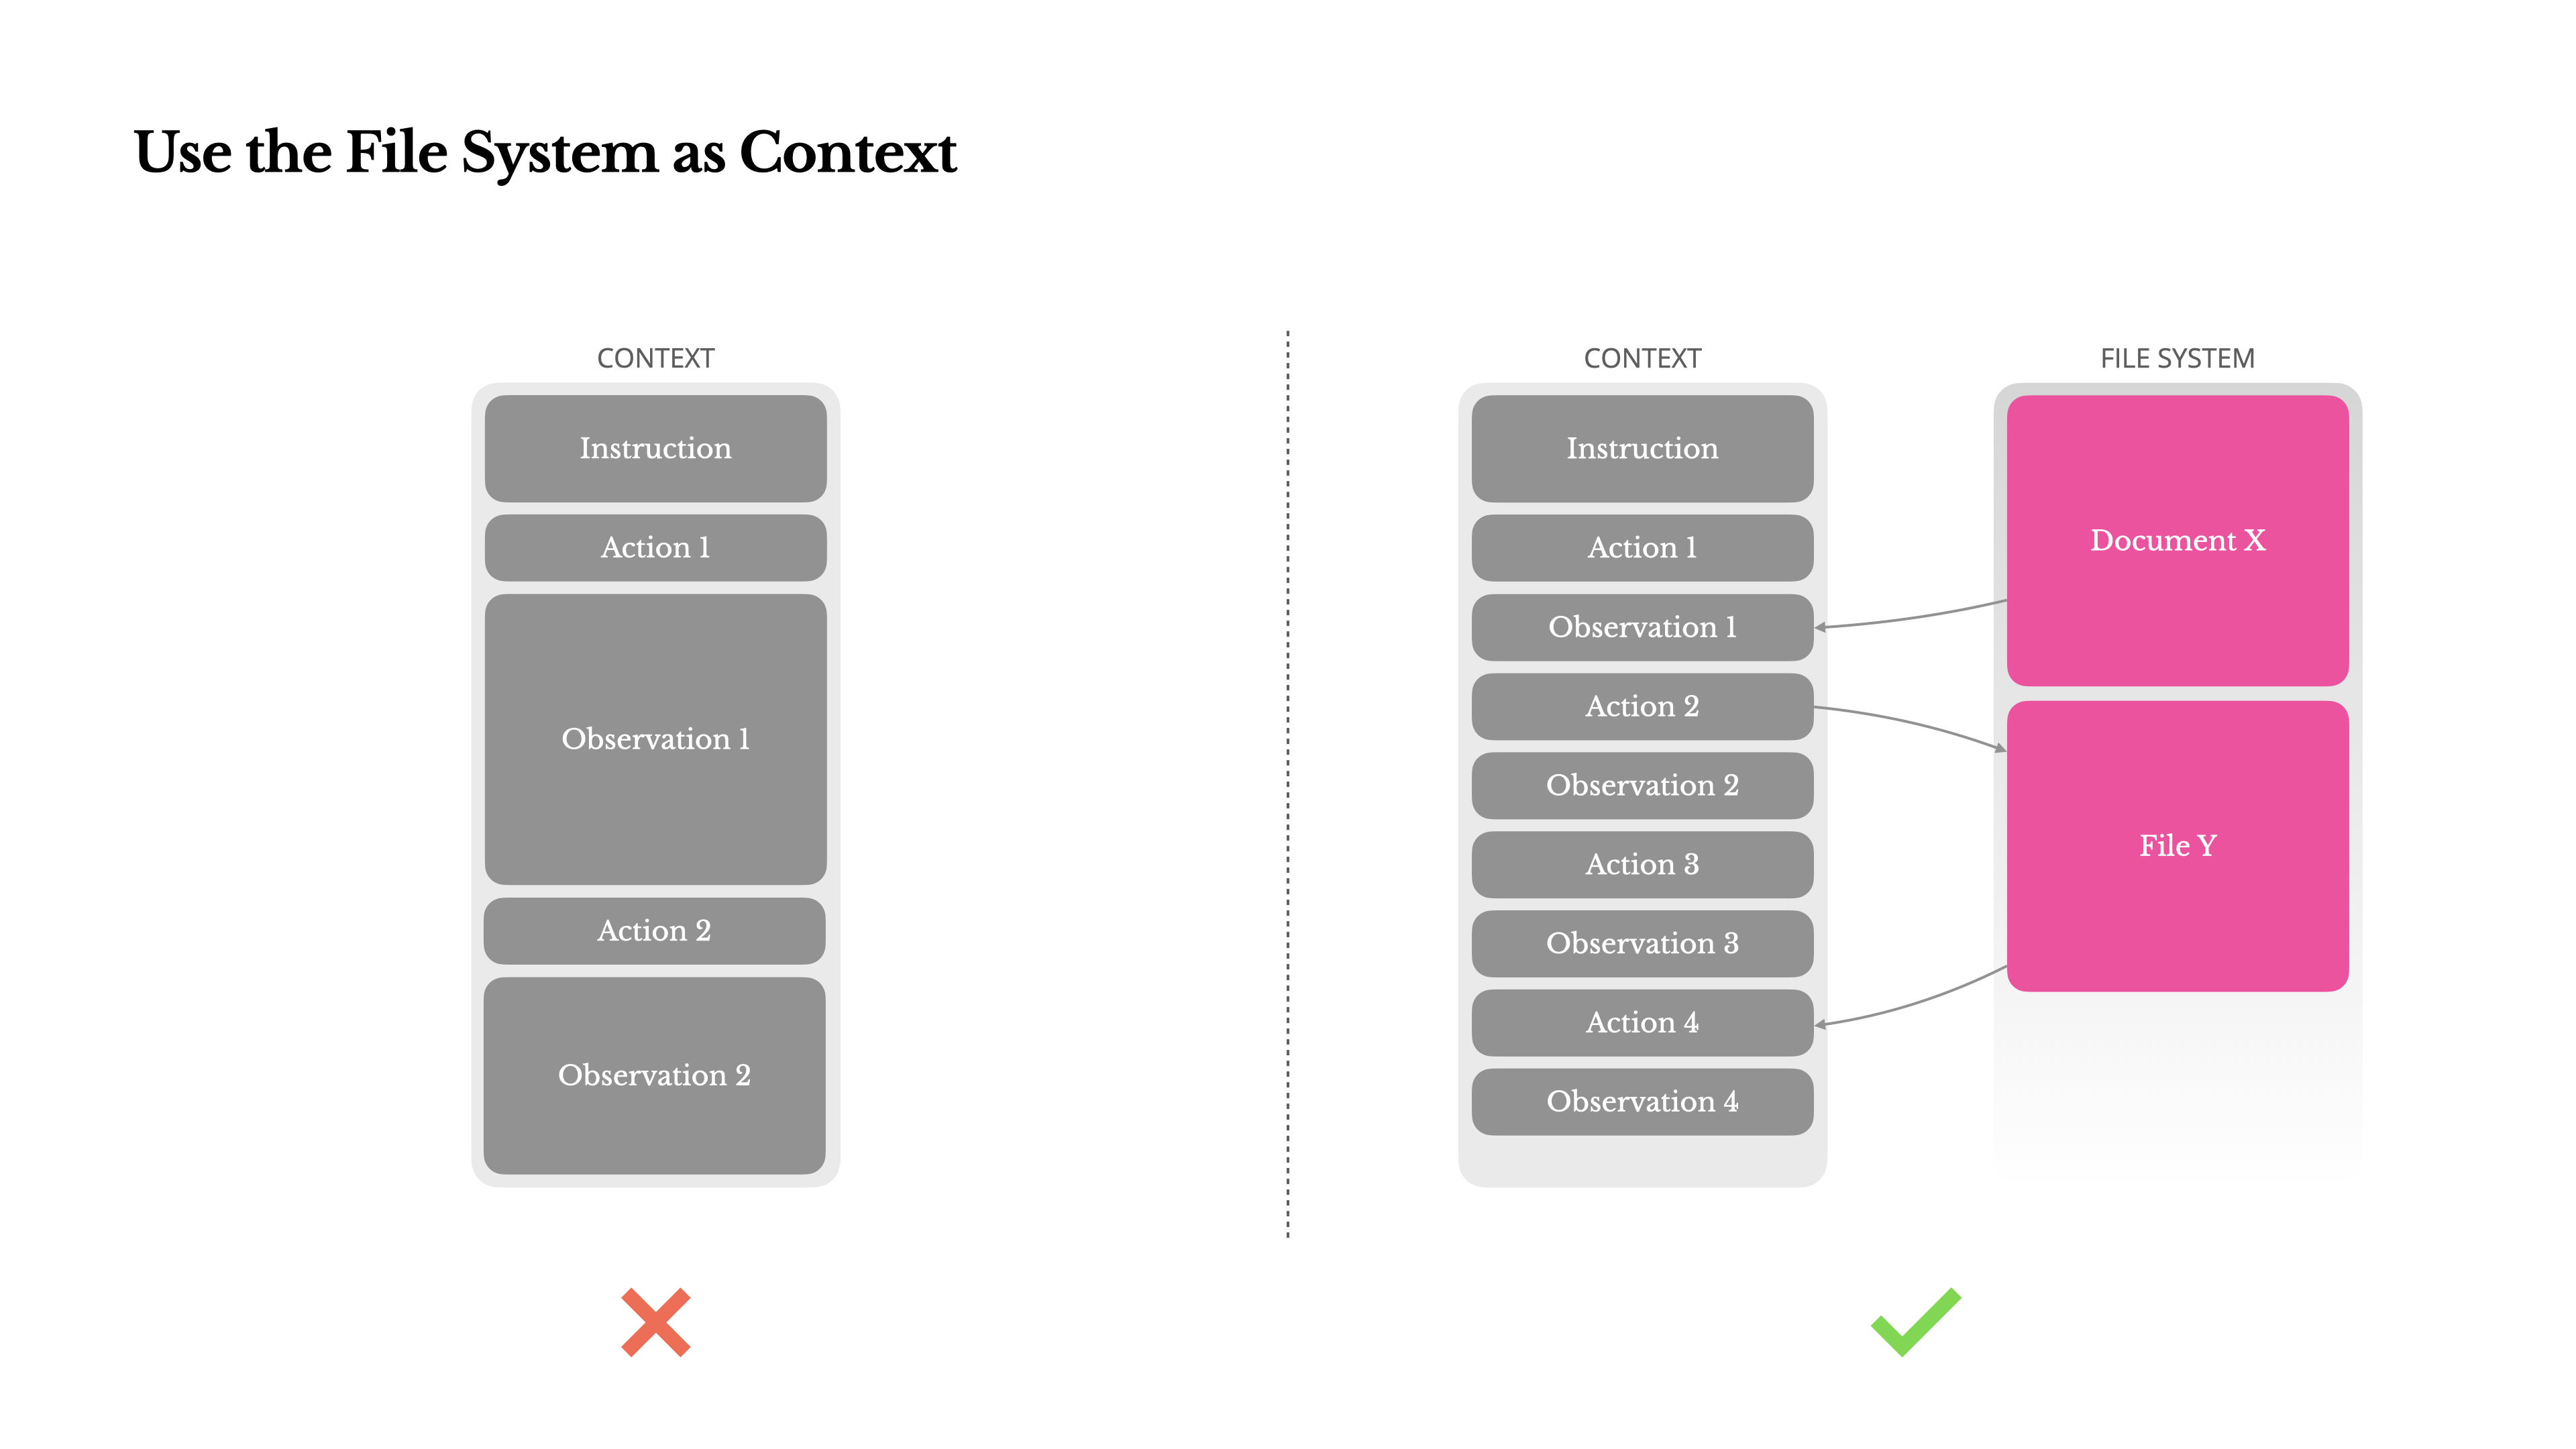
我们的压缩策略始终以可恢复为设计原则。例如,只要保留 URL,就可以将网页内容从上下文中移除;只要沙箱中仍有可用的文件路径,就可以省略文档内容。这样,Manus 能缩短上下文,同时避免永久丢失信息。
Our compression strategies are always designed to be restorable. For instance, the content of a web page can be dropped from the context as long as the URL is preserved, and a document's contents can be omitted if its path remains available in the sandbox. This allows Manus to shrink context length without permanently losing information.
开发这项功能时,我不禁设想:要让状态空间模型(SSM)在 Agent 场景中有效工作,需要什么条件?与 Transformer 不同,SSM 缺少全注意力机制,难以处理远距离的历史依赖。但如果它们能够掌握基于文件的记忆,将长期状态外置,而不是放在上下文中,那么其速度和效率或许能催生一类全新的 Agent。具备 Agent 能力的 SSM,可能才是神经图灵机真正的继承者。
While developing this feature, I found myself imagining what it would take for a State Space Model (SSM) to work effectively in an agentic setting. Unlike Transformers, SSMs lack full attention and struggle with long-range backward dependencies. But if they could master file-based memory—externalizing long-term state instead of holding it in context—then their speed and efficiency might unlock a new class of agents. Agentic SSMs could be the real successors to Neural Turing Machines.
通过复述调控注意力
Manipulate Attention Through Recitation
如果使用过 Manus,你可能注意到一个有趣现象:处理复杂任务时,它往往会创建一个 todo.md 文件,并随着任务推进逐步更新,勾选已经完成的事项。
If you've worked with Manus, you've probably noticed something curious: when handling complex tasks, it tends to create a todo.md file—and update it step-by-step as the task progresses, checking off completed items.
这不只是一个讨巧的行为,而是一种有意设计的注意力调控机制。
That's not just cute behavior—it's a deliberate mechanism to manipulate attention.
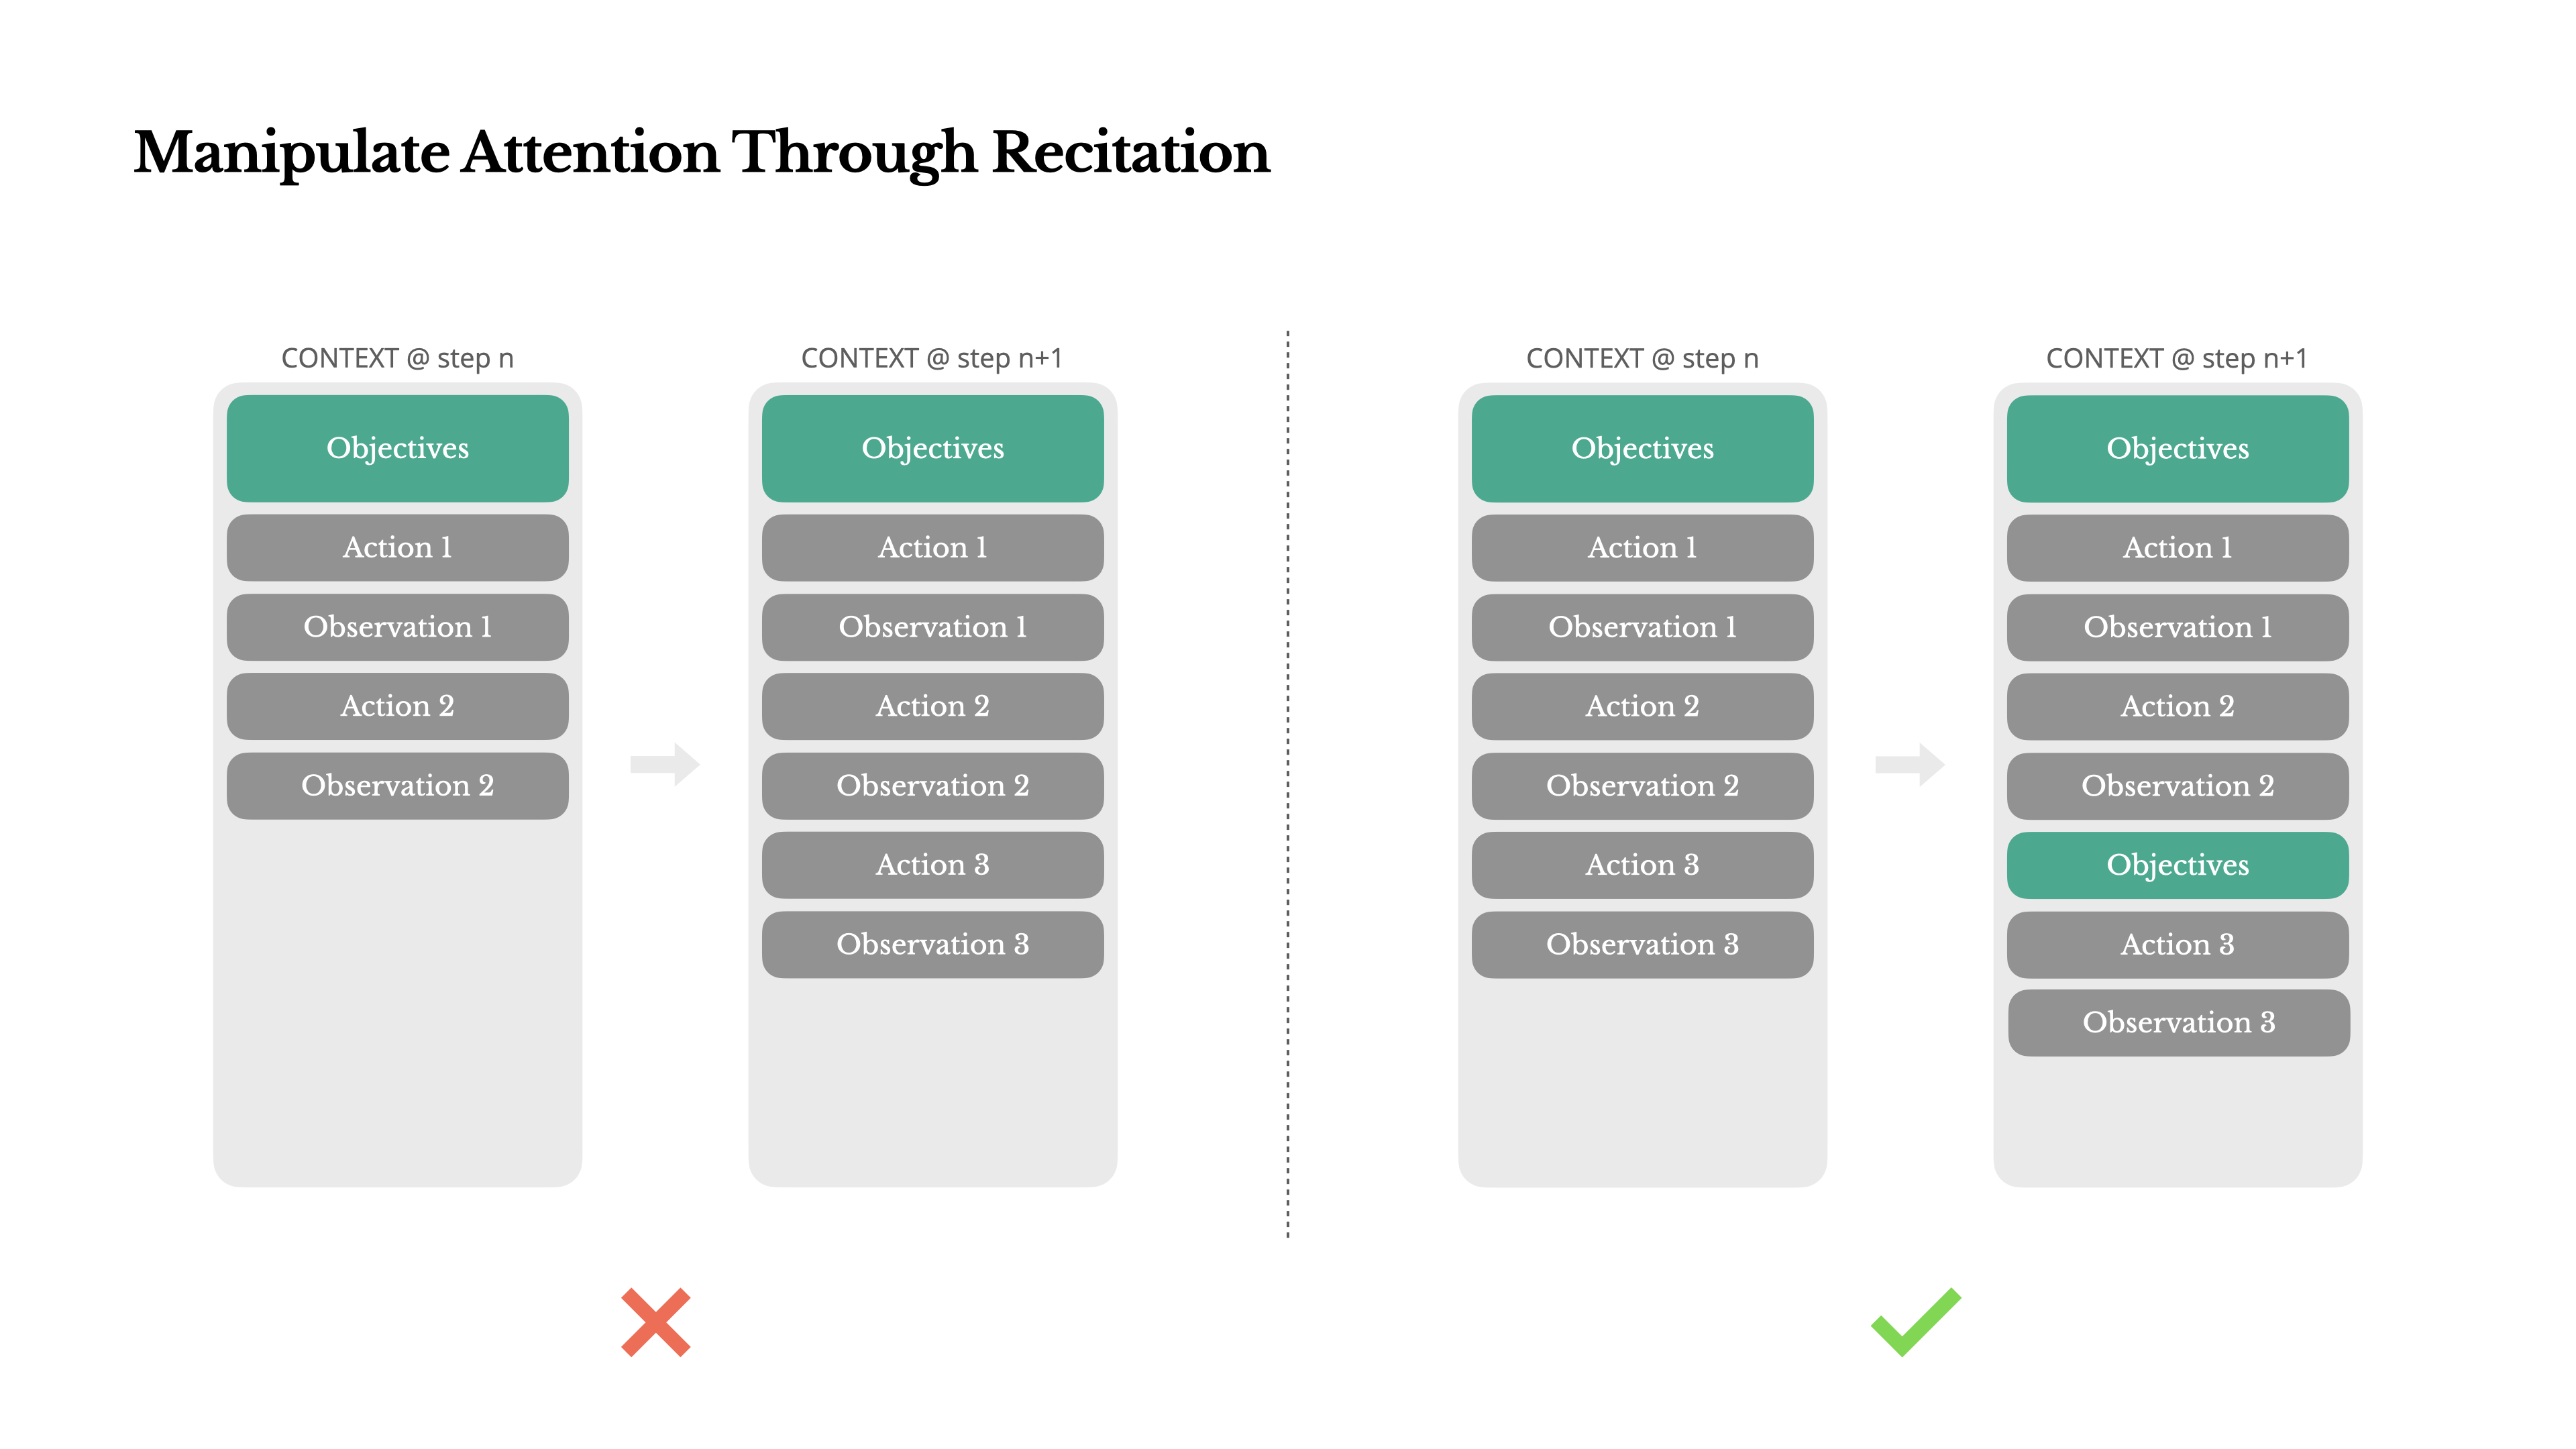
Manus 的典型任务平均需要大约 50 次工具调用。这是一个很长的循环。由于 Manus 依赖大语言模型作决策,它容易偏离主题或忘记早先的目标,尤其是在上下文很长、任务很复杂时。
A typical task in Manus requires around 50 tool calls on average. That's a long loop—and since Manus relies on LLMs for decision-making, it's vulnerable to drifting off-topic or forgetting earlier goals, especially in long contexts or complicated tasks.
通过不断重写待办清单,Manus 正在将目标反复复述到上下文末尾。这会把全局计划推入模型近期注意力覆盖的范围,避免“中间信息丢失”(lost-in-the-middle)问题,减少与目标的偏离。实质上,它是在用自然语言,将自身的关注点引向任务目标,而无需对架构进行特别改动。
By constantly rewriting the todo list, Manus is reciting its objectives into the end of the context. This pushes the global plan into the model's recent attention span, avoiding "lost-in-the-middle" issues and reducing goal misalignment. In effect, it's using natural language to bias its own focus toward the task objective—without needing special architectural changes.
把错误也留在上下文中
Keep the Wrong Stuff In
Agent 会犯错。这不是某个缺陷,而是现实。语言模型会产生幻觉,环境会返回错误,外部工具会行为异常,意料之外的边界情况也会不断出现。在多步骤任务中,失败不是例外,而是循环的一部分。
Agents make mistakes. That's not a bug—it's reality. Language models hallucinate, environments return errors, external tools misbehave, and unexpected edge cases show up all the time. In multi-step tasks, failure is not the exception; it's part of the loop.
然而,人们常常本能地想隐藏这些错误:清理执行轨迹、重试动作,或者重置模型状态,把一切交给神奇的“温度”。这似乎更安全、更可控。但代价是:抹去失败,也就移除了证据。没有证据,模型就无法调整。
And yet, a common impulse is to hide these errors: clean up the trace, retry the action, or reset the model's state and leave it to the magical "temperature". That feels safer, more controlled. But it comes at a cost: Erasing failure removes evidence. And without evidence, the model can't adapt.
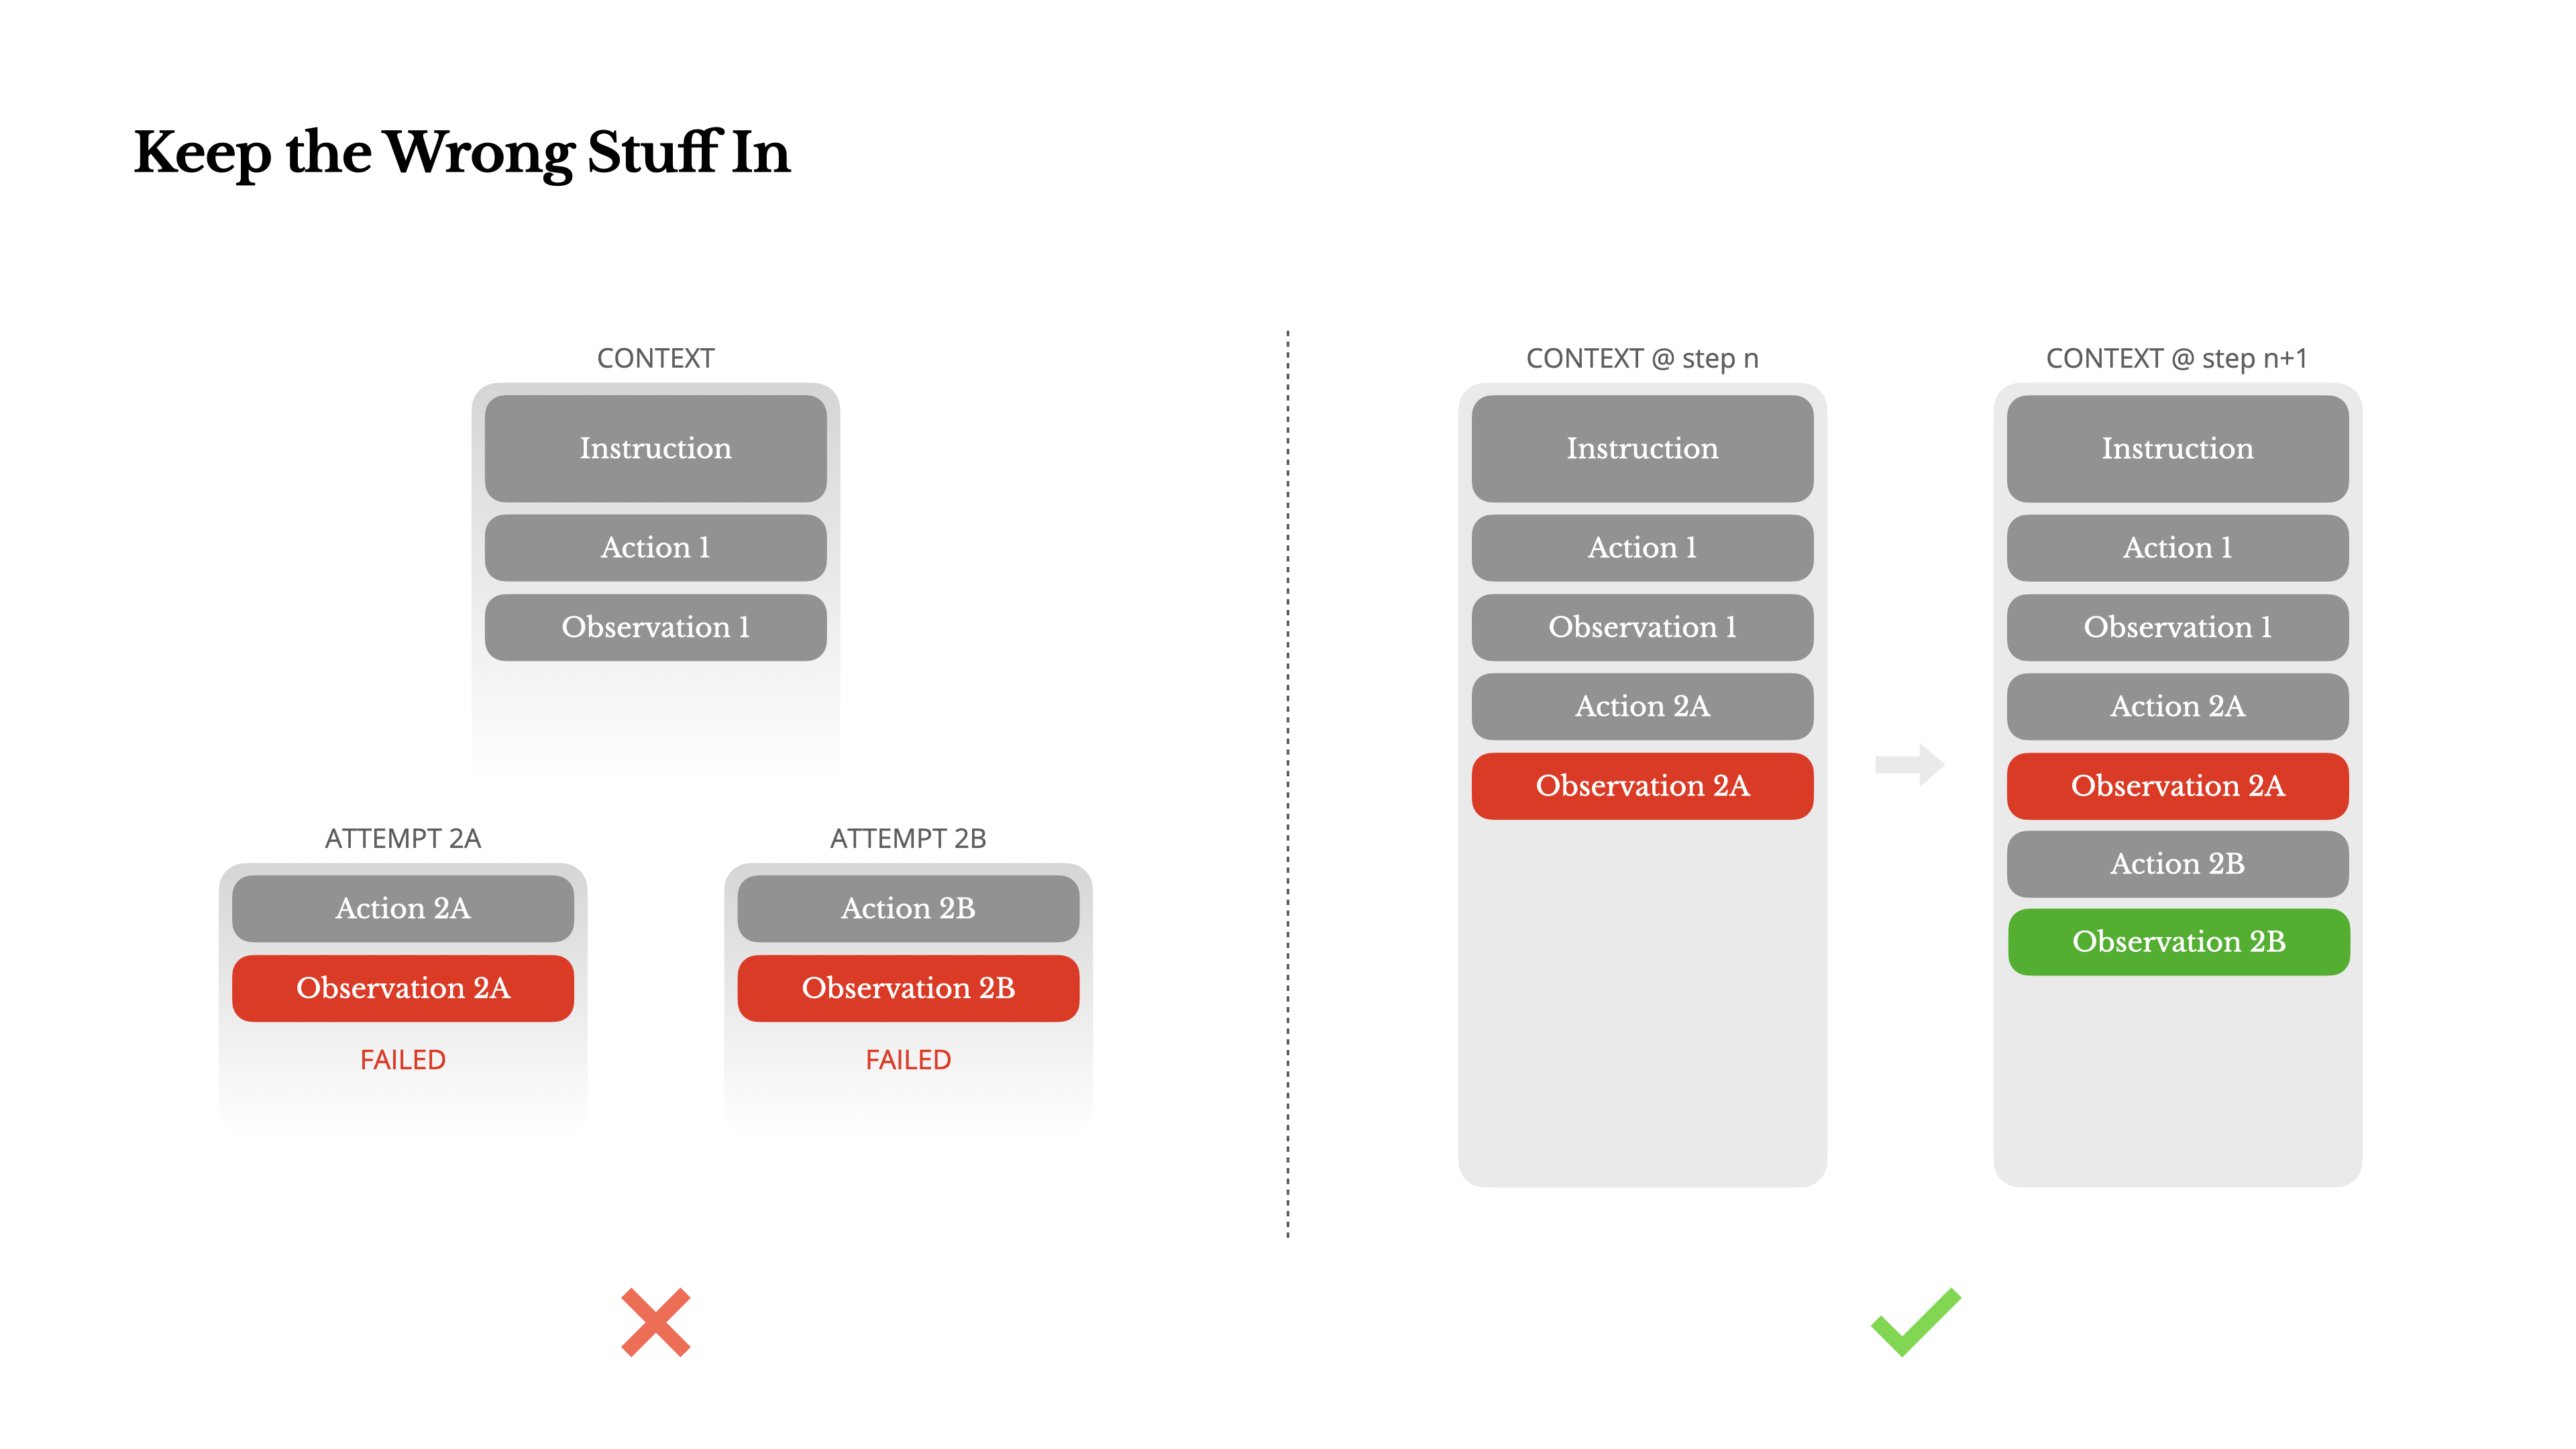
根据我们的经验,改善 Agent 行为最有效的方法之一,简单得出人意料:把走错的路留在上下文中。当模型看到失败的动作,以及由此产生的观测或堆栈轨迹时,它会隐式更新内部判断。这使它的先验倾向远离类似动作,降低重复同一错误的概率。事实上,我们认为,错误恢复是最能清楚体现真正 Agent 行为的指标之一。但多数学术工作和公开基准对此仍然关注不足,往往只聚焦于理想条件下的任务成功。
In our experience, one of the most effective ways to improve agent behavior is deceptively simple: leave the wrong turns in the context. When the model sees a failed action—and the resulting observation or stack trace—it implicitly updates its internal beliefs. This shifts its prior away from similar actions, reducing the chance of repeating the same mistake. In fact, we believe error recovery is one of the clearest indicators of true agentic behavior. Yet it's still underrepresented in most academic work and public benchmarks, which often focus on task success under ideal conditions.
别被少样本示例带进套路
Don't Get Few-Shotted
少样本提示是改善大语言模型输出的常见技术。但在 Agent 系统中,它可能以微妙的方式适得其反。
Few-shot prompting is a common technique for improving LLM outputs. But in agent systems, it can backfire in subtle ways.
语言模型是出色的模仿者,会模仿上下文中的行为模式。如果上下文充斥着以往相似的动作—观测对,模型就会倾向于遵循这种模式,即使这种模式已不再最优。
Language models are excellent mimics; they imitate the pattern of behavior in the context. If your context is full of similar past action-observation pairs, the model will tend to follow that pattern, even when it's no longer optimal.
对于涉及重复决策或动作的任务,这可能很危险。例如,用 Manus 帮助审阅一批 20 份简历时,Agent 往往会进入某种固定节奏:仅仅因为上下文中出现过类似动作,就不断重复。这会导致偏移、过度泛化,有时还会产生幻觉。
This can be dangerous in tasks that involve repetitive decisions or actions. For example, when using Manus to help review a batch of 20 resumes, the agent often falls into a rhythm—repeating similar actions simply because that's what it sees in the context. This leads to drift, overgeneralization, or sometimes hallucination.
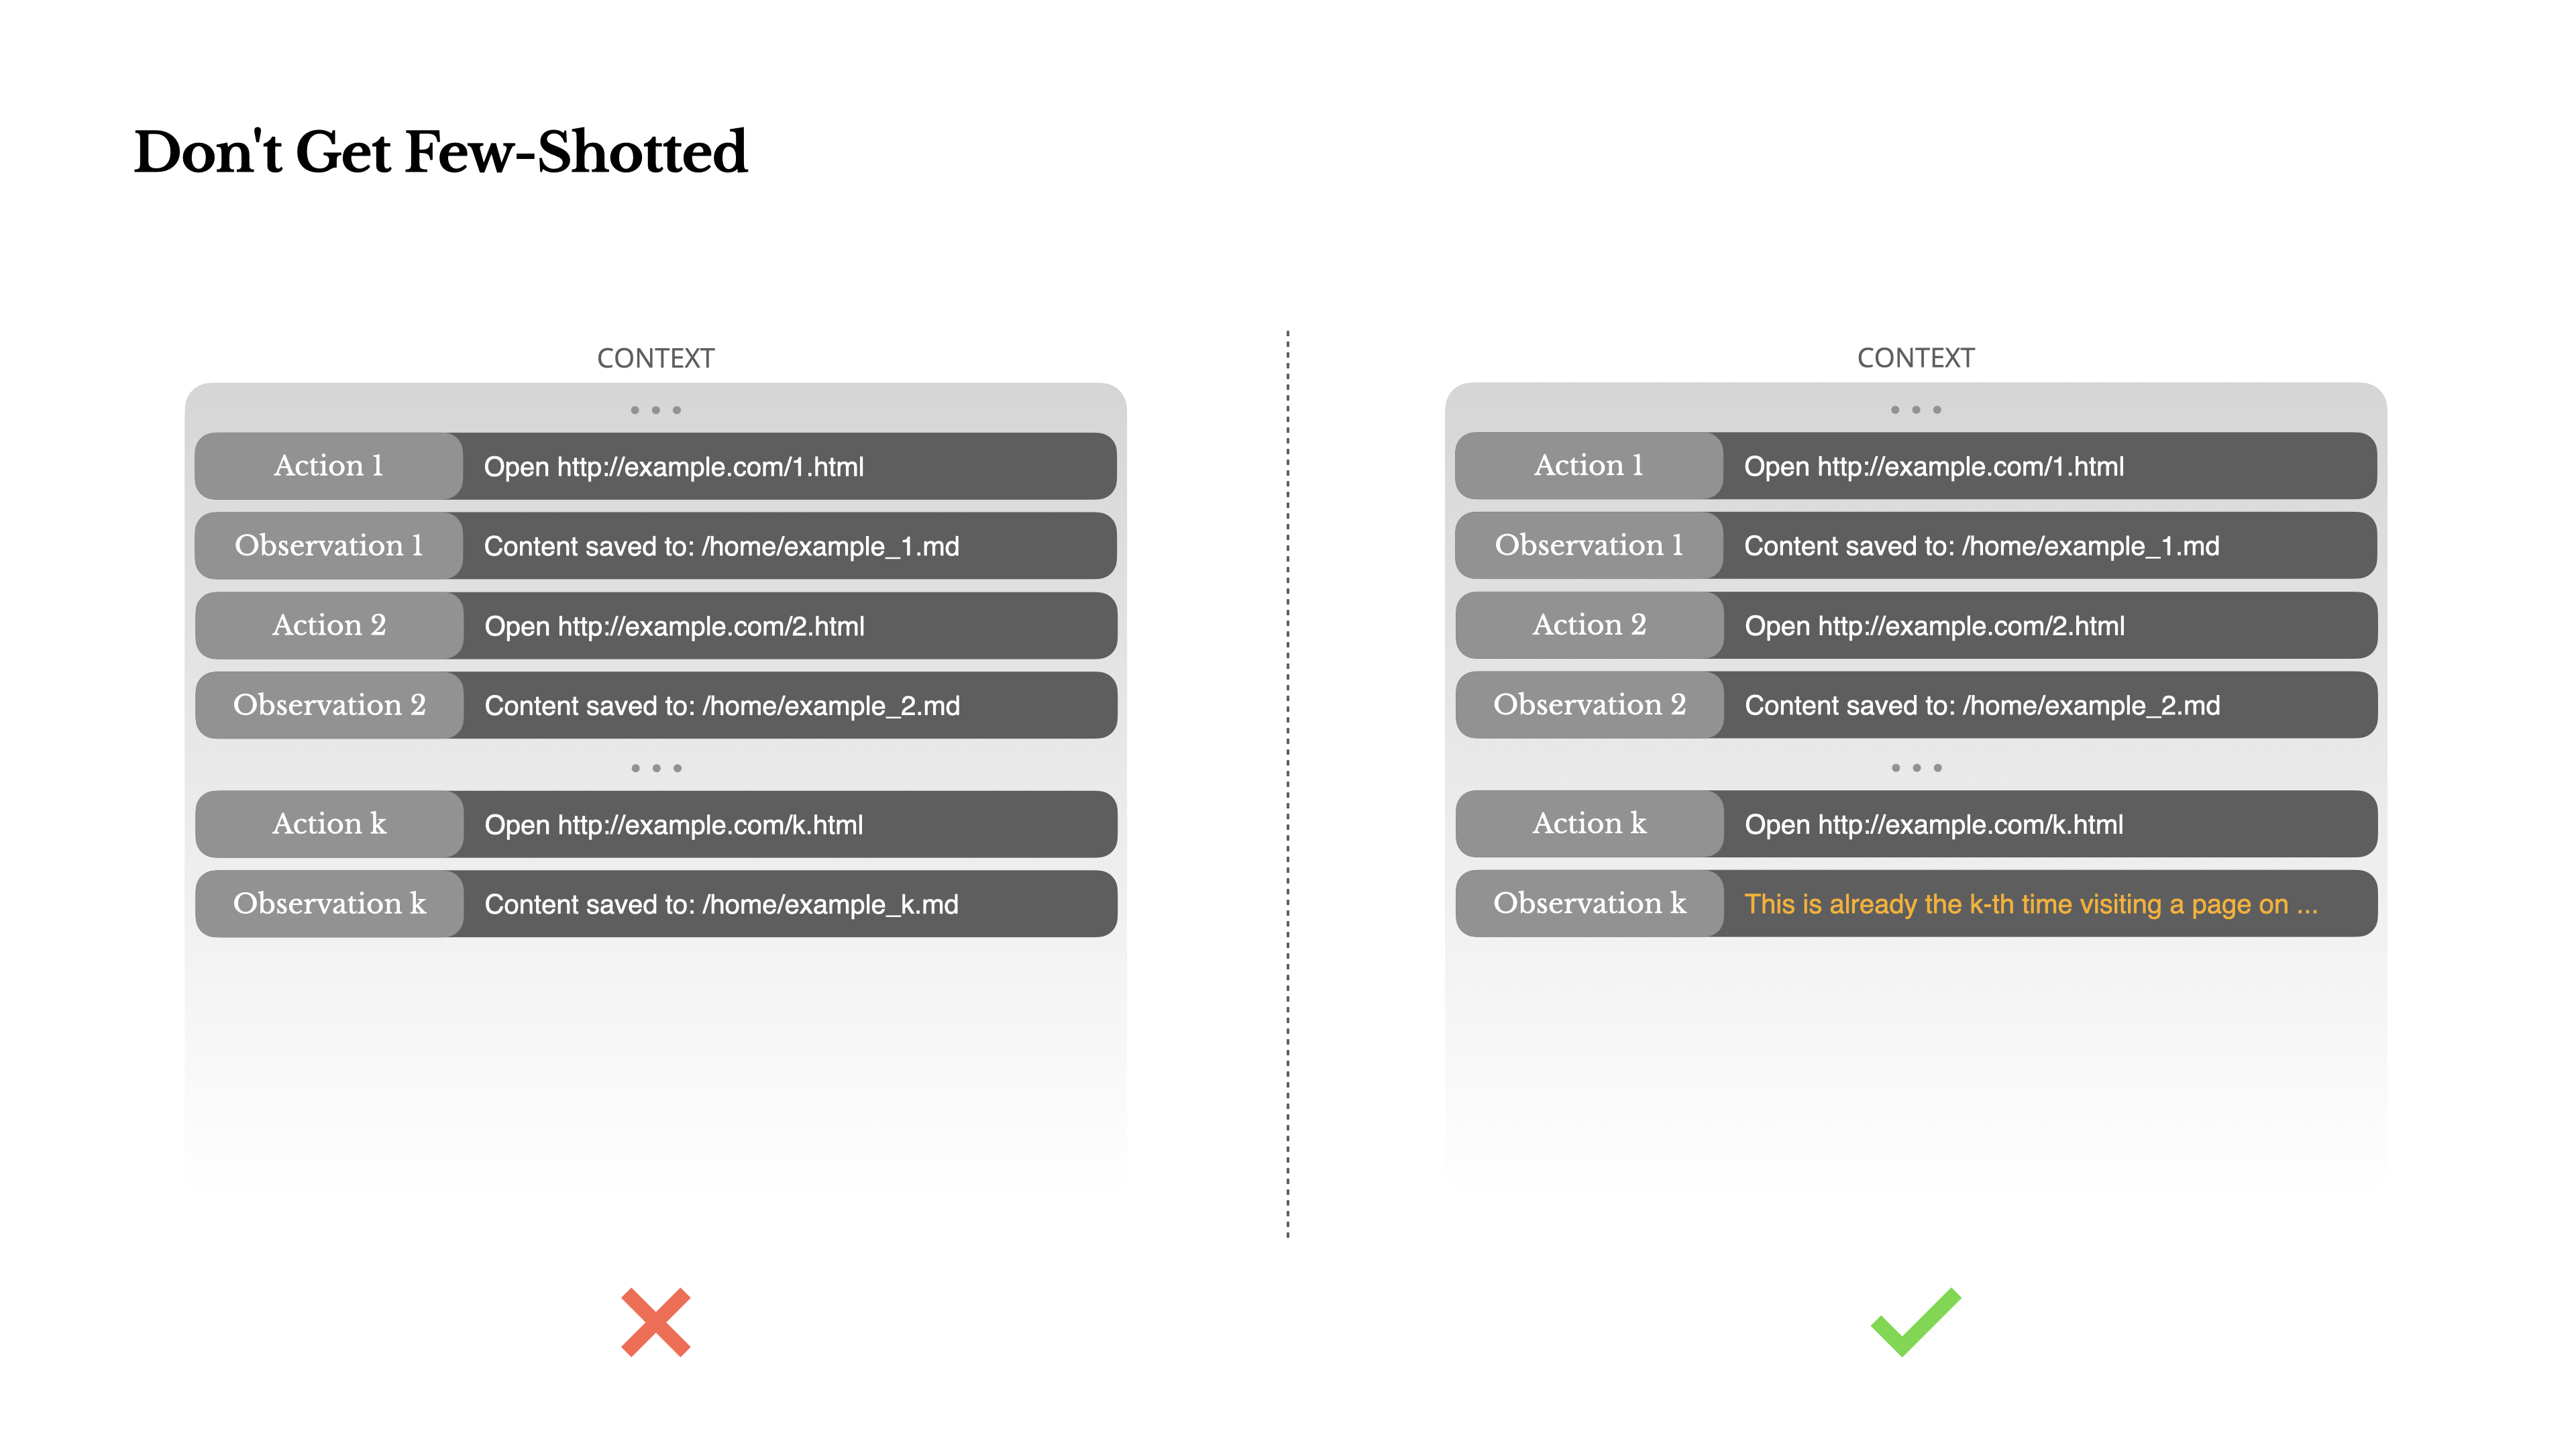
解决办法是增加多样性。Manus 会在动作和观测中加入少量有结构的变化:采用不同的序列化模板、替换措辞,或在顺序和格式上加入轻微扰动。这种受控的随机性,有助于打破固定模式,调整模型的注意力。换句话说,别让少样本示例把自己困在套路里。上下文越单一,Agent 就越脆弱。
The fix is to increase diversity. Manus introduces small amounts of structured variation in actions and observations—different serialization templates, alternate phrasing, minor noise in order or formatting. This controlled randomness helps break the pattern and tweaks the model's attention. In other words, don't few-shot yourself into a rut. The more uniform your context, the more brittle your agent becomes.
结语
Conclusion
上下文工程仍是一门新兴科学,但对 Agent 系统来说,它已经不可或缺。模型或许正在变得更强、更快、更便宜,但无论基础能力多强,都不能取代对记忆、环境和反馈的需求。你如何塑造上下文,最终决定了 Agent 如何行动:运行得多快、恢复得多好,以及能扩展到多大规模。
Context engineering is still an emerging science—but for agent systems, it's already essential. Models may be getting stronger, faster, and cheaper, but no amount of raw capability replaces the need for memory, environment, and feedback. How you shape the context ultimately defines how your agent behaves: how fast it runs, how well it recovers, and how far it scales.
在 Manus,我们通过一次次重写、走入死胡同,以及面向数百万用户的真实环境测试,学到了这些经验。本文分享的内容都不是普遍真理,但它们是对我们有效的模式。如果这些经验能帮你少经历哪怕一次痛苦的迭代,这篇文章就达到了目的。
At Manus, we've learned these lessons through repeated rewrites, dead ends, and real-world testing across millions of users. None of what we've shared here is universal truth—but these are the patterns that worked for us. If they help you avoid even one painful iteration, then this post did its job.
Agent 的未来,将由一个又一个上下文构建起来。请认真设计它们。
The agentic future will be built one context at a time. Engineer them well.
— 全文完 —
原文来自 Manus,中文为非官方学习译文。
查看原始出处 ↗