我们的 Research 功能使用多个 Claude Agent,更有效地探索复杂主题。本文分享我们构建这个系统时遇到的工程挑战,以及从中学到的经验。
Our Research feature uses multiple Claude agents to explore complex topics more effectively. We share the engineering challenges and the lessons we learned from building this system.
Claude 现在具备了 Research 能力,可以在网络、Google Workspace 及各种集成服务中搜索,以完成复杂任务。
Claude now has Research capabilities that allow it to search across the web, Google Workspace, and any integrations to accomplish complex tasks.
这个多 Agent 系统从原型走向生产的过程,让我们在系统架构、工具设计和提示词工程方面积累了重要经验。多 Agent 系统由多个协同工作的 Agent 组成,这些 Agent 是在循环中自主使用工具的大语言模型。我们的 Research 功能中有一个 Agent,会根据用户查询规划研究过程,然后通过工具创建并行 Agent,让它们同时搜索信息。引入多个 Agent,也给 Agent 之间的协调、评测和可靠性带来了新的挑战。
The journey of this multi-agent system from prototype to production taught us critical lessons about system architecture, tool design, and prompt engineering. A multi-agent system consists of multiple agents (LLMs autonomously using tools in a loop) working together. Our Research feature involves an agent that plans a research process based on user queries, and then uses tools to create parallel agents that search for information simultaneously. Systems with multiple agents introduce new challenges in agent coordination, evaluation, and reliability.
本文将逐一介绍对我们行之有效的原则,希望这些经验也能帮助你构建自己的多 Agent 系统。
This post breaks down the principles that worked for us—we hope you'll find them useful to apply when building your own multi-agent systems.
多 Agent 系统的优势
Benefits of a multi-agent system
研究工作涉及开放式问题,所需步骤很难事先预测。探索复杂主题时,无法把一条固定路径硬编码下来,因为这个过程本质上是动态的,而且依赖此前走过的路径。人们开展研究时,往往会根据新发现不断调整方法,追踪调查过程中浮现的线索。
Research work involves open-ended problems where it’s very difficult to predict the required steps in advance. You can’t hardcode a fixed path for exploring complex topics, as the process is inherently dynamic and path-dependent. When people conduct research, they tend to continuously update their approach based on discoveries, following leads that emerge during investigation.
这种不可预测性使 AI Agent 特别适合研究任务。随着调查推进,研究需要灵活改变方向,或探索旁支联系。模型必须连续自主运行许多轮,根据中间发现决定下一步追踪哪些方向。线性的、一次性执行的流水线无法应对这些任务。
This unpredictability makes AI agents particularly well-suited for research tasks. Research demands the flexibility to pivot or explore tangential connections as the investigation unfolds. The model must operate autonomously for many turns, making decisions about which directions to pursue based on intermediate findings. A linear, one-shot pipeline cannot handle these tasks.
搜索的本质是压缩:从庞大的资料库中提炼洞见。子 Agent 分别使用自己的上下文窗口并行运行,同时探索问题的不同方面,再把最重要的 token 凝练后交给主研究 Agent,从而帮助实现压缩。每个子 Agent 也实现了关注点分离,拥有不同的工具、提示词和探索轨迹。这减少了路径依赖,使深入、独立的调查成为可能。
The essence of search is compression: distilling insights from a vast corpus. Subagents facilitate compression by operating in parallel with their own context windows, exploring different aspects of the question simultaneously before condensing the most important tokens for the lead research agent. Each subagent also provides separation of concerns—distinct tools, prompts, and exploration trajectories—which reduces path dependency and enables thorough, independent investigations.
当智能达到某个门槛后,多 Agent 系统就成了提升性能的重要途径。例如,尽管过去 10 万年间人类个体变得更聪明了,但在信息时代,人类社会能力的指数级增长,靠的是我们的集体智慧与协调能力。即便具备通用智能,Agent 独自行动时仍然会受到限制;一组 Agent 能完成的事情要多得多。
Once intelligence reaches a threshold, multi-agent systems become a vital way to scale performance. For instance, although individual humans have become more intelligent in the last 100,000 years, human societies have become exponentially more capable in the information age because of our collective intelligence and ability to coordinate. Even generally-intelligent agents face limits when operating as individuals; groups of agents can accomplish far more.
我们的内部评测表明,多 Agent 研究系统尤其擅长广度优先的查询,这类查询需要同时推进多个相互独立的方向。我们发现,在内部研究评测中,以 Claude Opus 4 为主 Agent、Claude Sonnet 4 为子 Agent 的多 Agent 系统,性能比单 Agent 的 Claude Opus 4 高出 90.2%。例如,面对“找出标普 500 指数中信息技术板块所有公司的全部董事会成员”这一要求,多 Agent 系统把它拆成子 Agent 的任务后找到了正确答案;而单 Agent 系统以缓慢、串行的方式搜索,未能找到答案。
Our internal evaluations show that multi-agent research systems excel especially for breadth-first queries that involve pursuing multiple independent directions simultaneously. We found that a multi-agent system with Claude Opus 4 as the lead agent and Claude Sonnet 4 subagents outperformed single-agent Claude Opus 4 by 90.2% on our internal research eval. For example, when asked to identify all the board members of the companies in the Information Technology S&P 500, the multi-agent system found the correct answers by decomposing this into tasks for subagents, while the single agent system failed to find the answer with slow, sequential searches.
多 Agent 系统之所以有效,主要是因为它们有助于投入足够的 token 来解决问题。在我们的分析中,三个因素解释了 BrowseComp 评测中 95% 的性能方差。该评测测试的是浏览 Agent 找到难以获取的信息的能力。我们发现,仅 token 用量就能解释 80% 的方差,另外两个具有解释力的因素是工具调用次数和模型选择。这一发现验证了我们的架构:把工作分配给具有独立上下文窗口的多个 Agent,从而增加并行推理的容量。最新的 Claude 模型极大地提高了 token 使用效率,因为升级到 Claude Sonnet 4 带来的性能提升,比把 Claude Sonnet 3.7 的 token 预算翻倍还要大。对于超出单个 Agent 能力上限的任务,多 Agent 架构能够有效扩大 token 投入。
Multi-agent systems work mainly because they help spend enough tokens to solve the problem. In our analysis, three factors explained 95% of the performance variance in the BrowseComp evaluation (which tests the ability of browsing agents to locate hard-to-find information). We found that token usage by itself explains 80% of the variance, with the number of tool calls and the model choice as the two other explanatory factors. This finding validates our architecture that distributes work across agents with separate context windows to add more capacity for parallel reasoning. The latest Claude models act as large efficiency multipliers on token use, as upgrading to Claude Sonnet 4 is a larger performance gain than doubling the token budget on Claude Sonnet 3.7. Multi-agent architectures effectively scale token usage for tasks that exceed the limits of single agents.
但也有一个缺点:在实际运行中,这类架构消耗 token 的速度很快。我们的数据显示,Agent 的 token 用量通常约为聊天交互的 4 倍,多 Agent 系统则约为聊天的 15 倍。要在经济上可行,任务本身的价值必须足够高,才能覆盖多 Agent 系统提升性能所增加的成本。此外,某些领域要求所有 Agent 共享同一份上下文,或 Agent 之间存在大量依赖关系,目前并不适合采用多 Agent 系统。例如,与研究相比,大多数编程任务中真正可以并行开展的工作较少,而且大语言模型 Agent 目前还不擅长实时协调其他 Agent 并向其委派任务。我们发现,多 Agent 系统擅长处理那些价值较高、需要大量并行工作、信息量超出单个上下文窗口、并且要对接众多复杂工具的任务。
There is a downside: in practice, these architectures burn through tokens fast. In our data, agents typically use about 4× more tokens than chat interactions, and multi-agent systems use about 15× more tokens than chats. For economic viability, multi-agent systems require tasks where the value of the task is high enough to pay for the increased performance. Further, some domains that require all agents to share the same context or involve many dependencies between agents are not a good fit for multi-agent systems today. For instance, most coding tasks involve fewer truly parallelizable tasks than research, and LLM agents are not yet great at coordinating and delegating to other agents in real time. We’ve found that multi-agent systems excel at valuable tasks that involve heavy parallelization, information that exceeds single context windows, and interfacing with numerous complex tools.
Research 架构概览
Architecture overview for Research
我们的 Research 系统采用多 Agent 架构,使用编排者—工作者模式:由主 Agent 协调整个过程,同时把工作委派给并行运行的专门子 Agent。
Our Research system uses a multi-agent architecture with an orchestrator-worker pattern, where a lead agent coordinates the process while delegating to specialized subagents that operate in parallel.
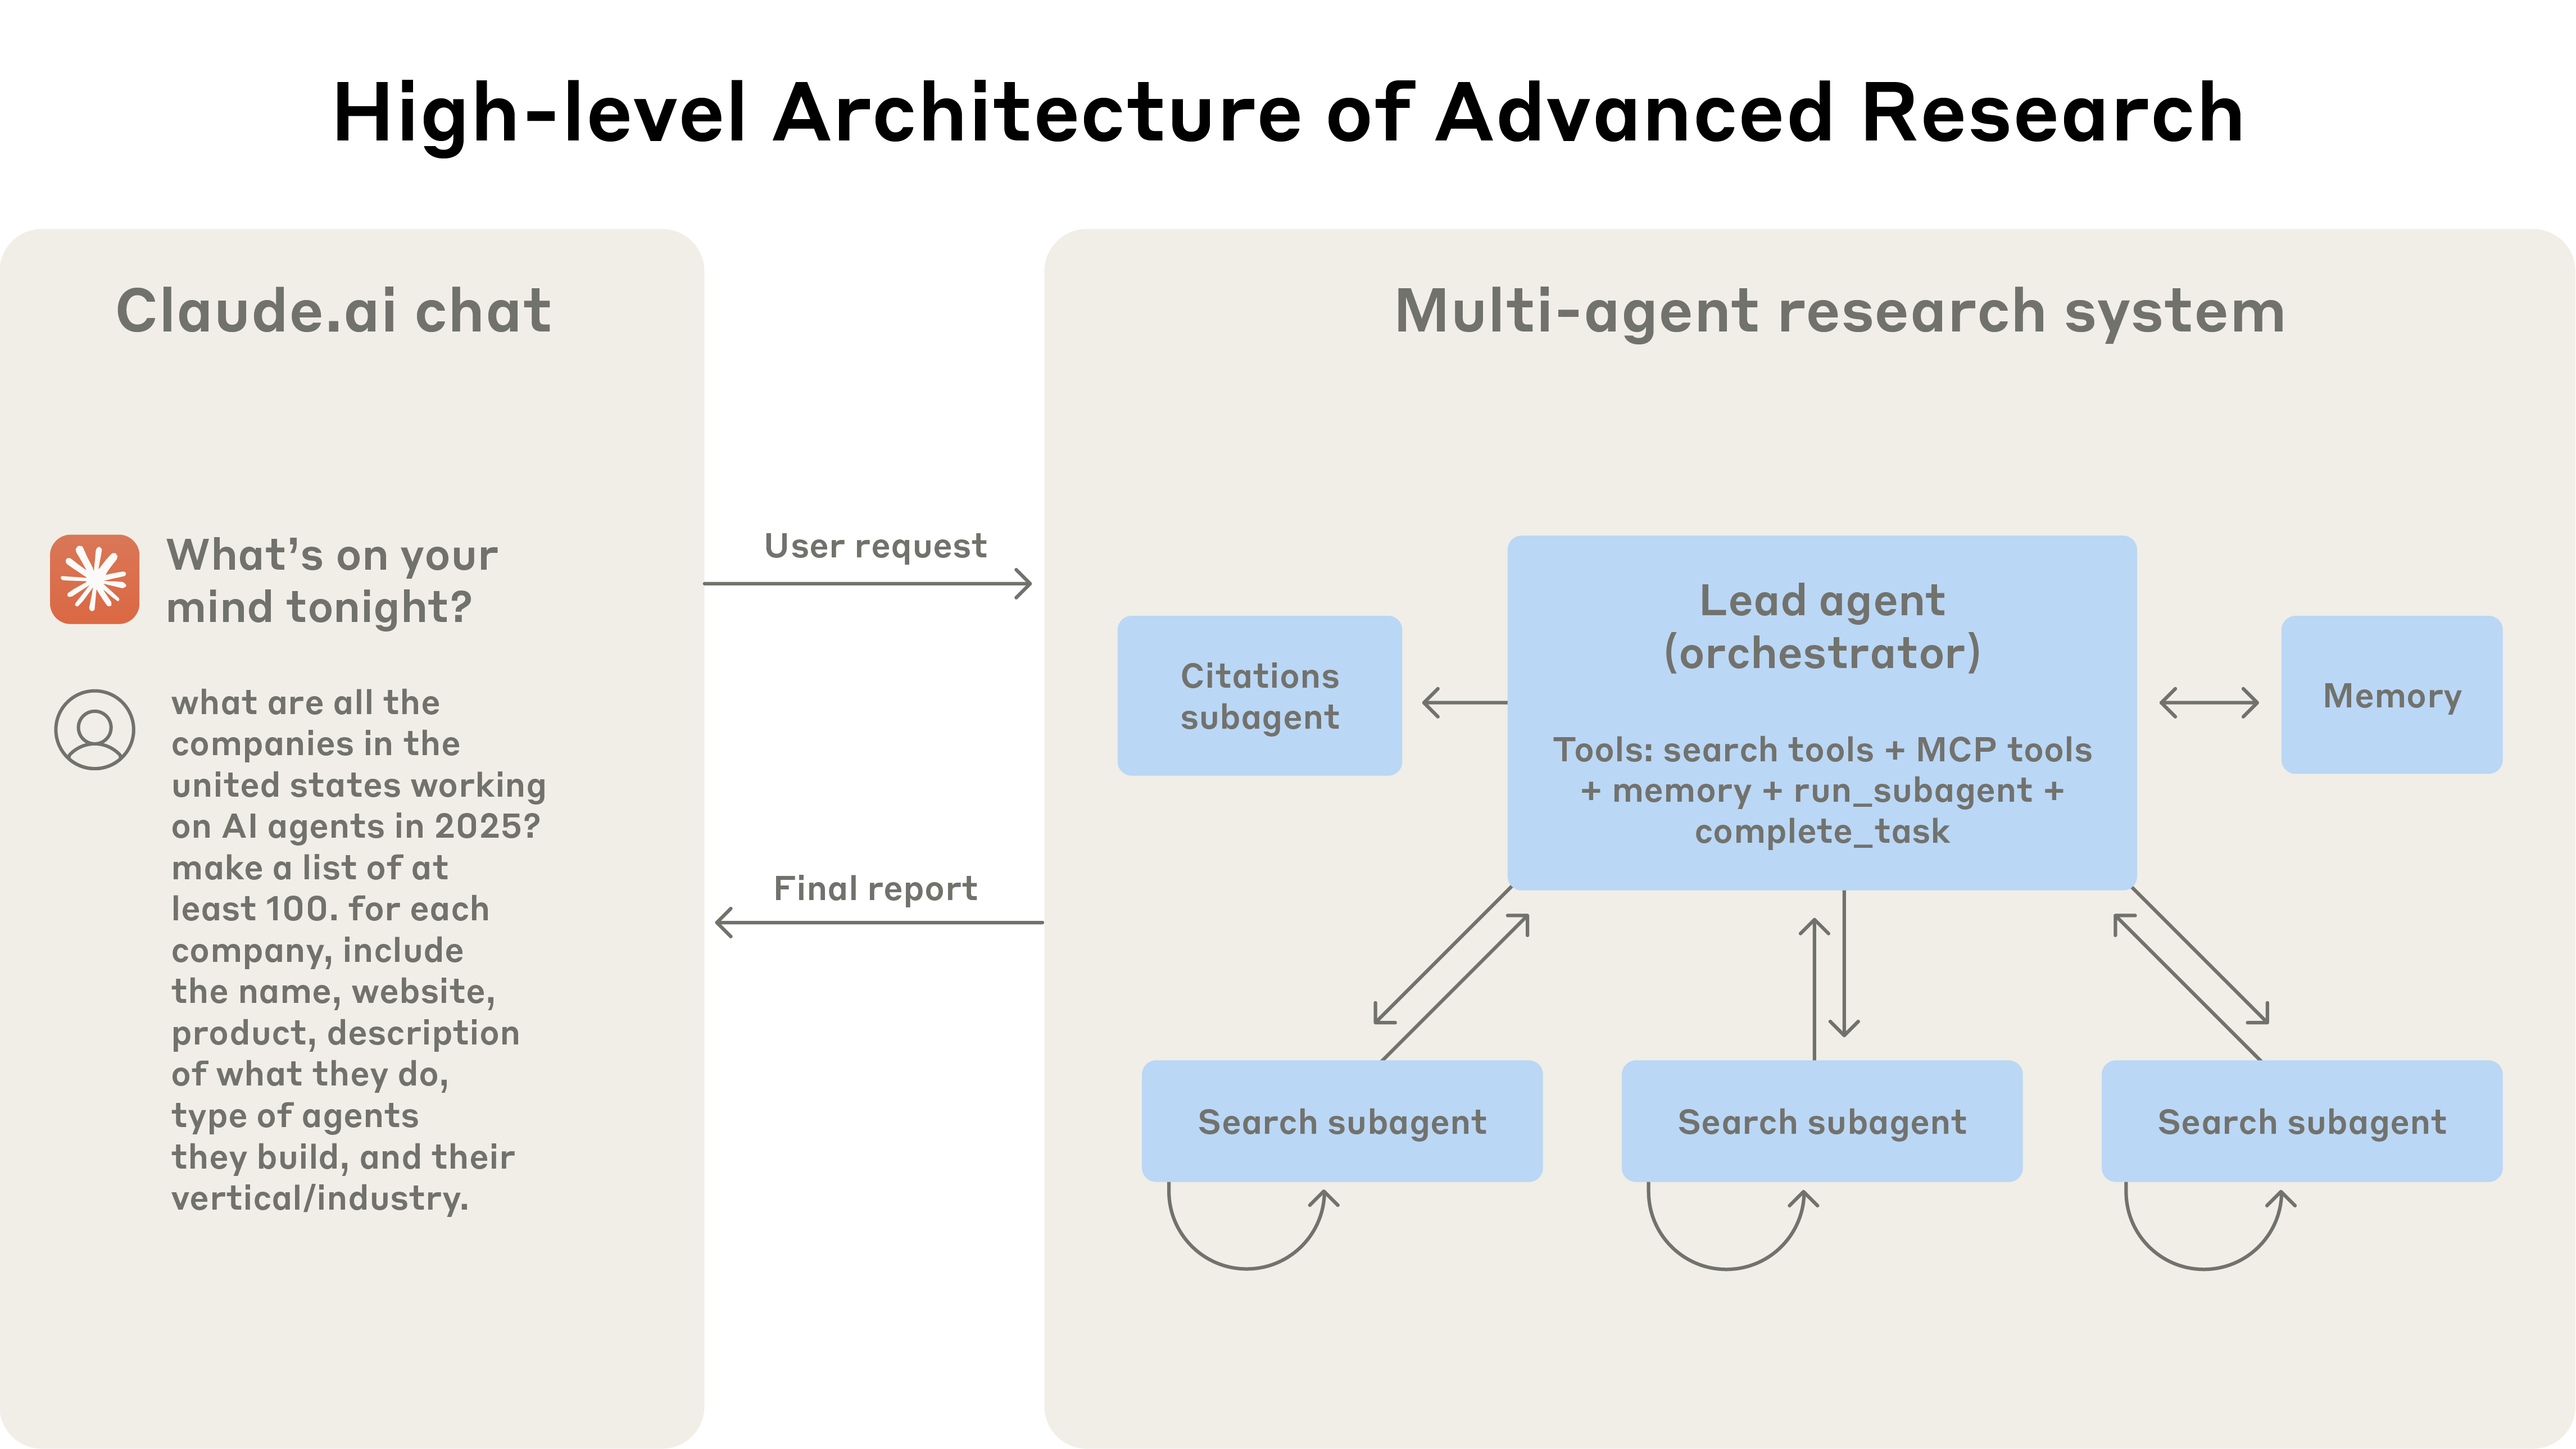
用户提交查询后,主 Agent 会分析查询、制定策略,并创建子 Agent,让它们同时探索不同方面。如上图所示,子 Agent 充当智能过滤器,反复使用搜索工具收集信息。在这个例子中,它们收集的是 2025 年 AI Agent 公司的信息,然后把公司名单返回给主 Agent,由主 Agent 汇总成最终答案。
When a user submits a query, the lead agent analyzes it, develops a strategy, and spawns subagents to explore different aspects simultaneously. As shown in the diagram above, the subagents act as intelligent filters by iteratively using search tools to gather information, in this case on AI agent companies in 2025, and then returning a list of companies to the lead agent so it can compile a final answer.
传统的检索增强生成(RAG)方法采用静态检索:获取与输入查询最相似的一组文本片段,再利用这些片段生成回答。我们的架构则采用多步搜索,动态发现相关信息,根据新发现调整方向,并分析结果以形成高质量答案。
Traditional approaches using Retrieval Augmented Generation (RAG) use static retrieval. That is, they fetch some set of chunks that are most similar to an input query and use these chunks to generate a response. In contrast, our architecture uses a multi-step search that dynamically finds relevant information, adapts to new findings, and analyzes results to formulate high-quality answers.
研究 Agent 的提示词工程与评测
Prompt engineering and evaluations for research agents
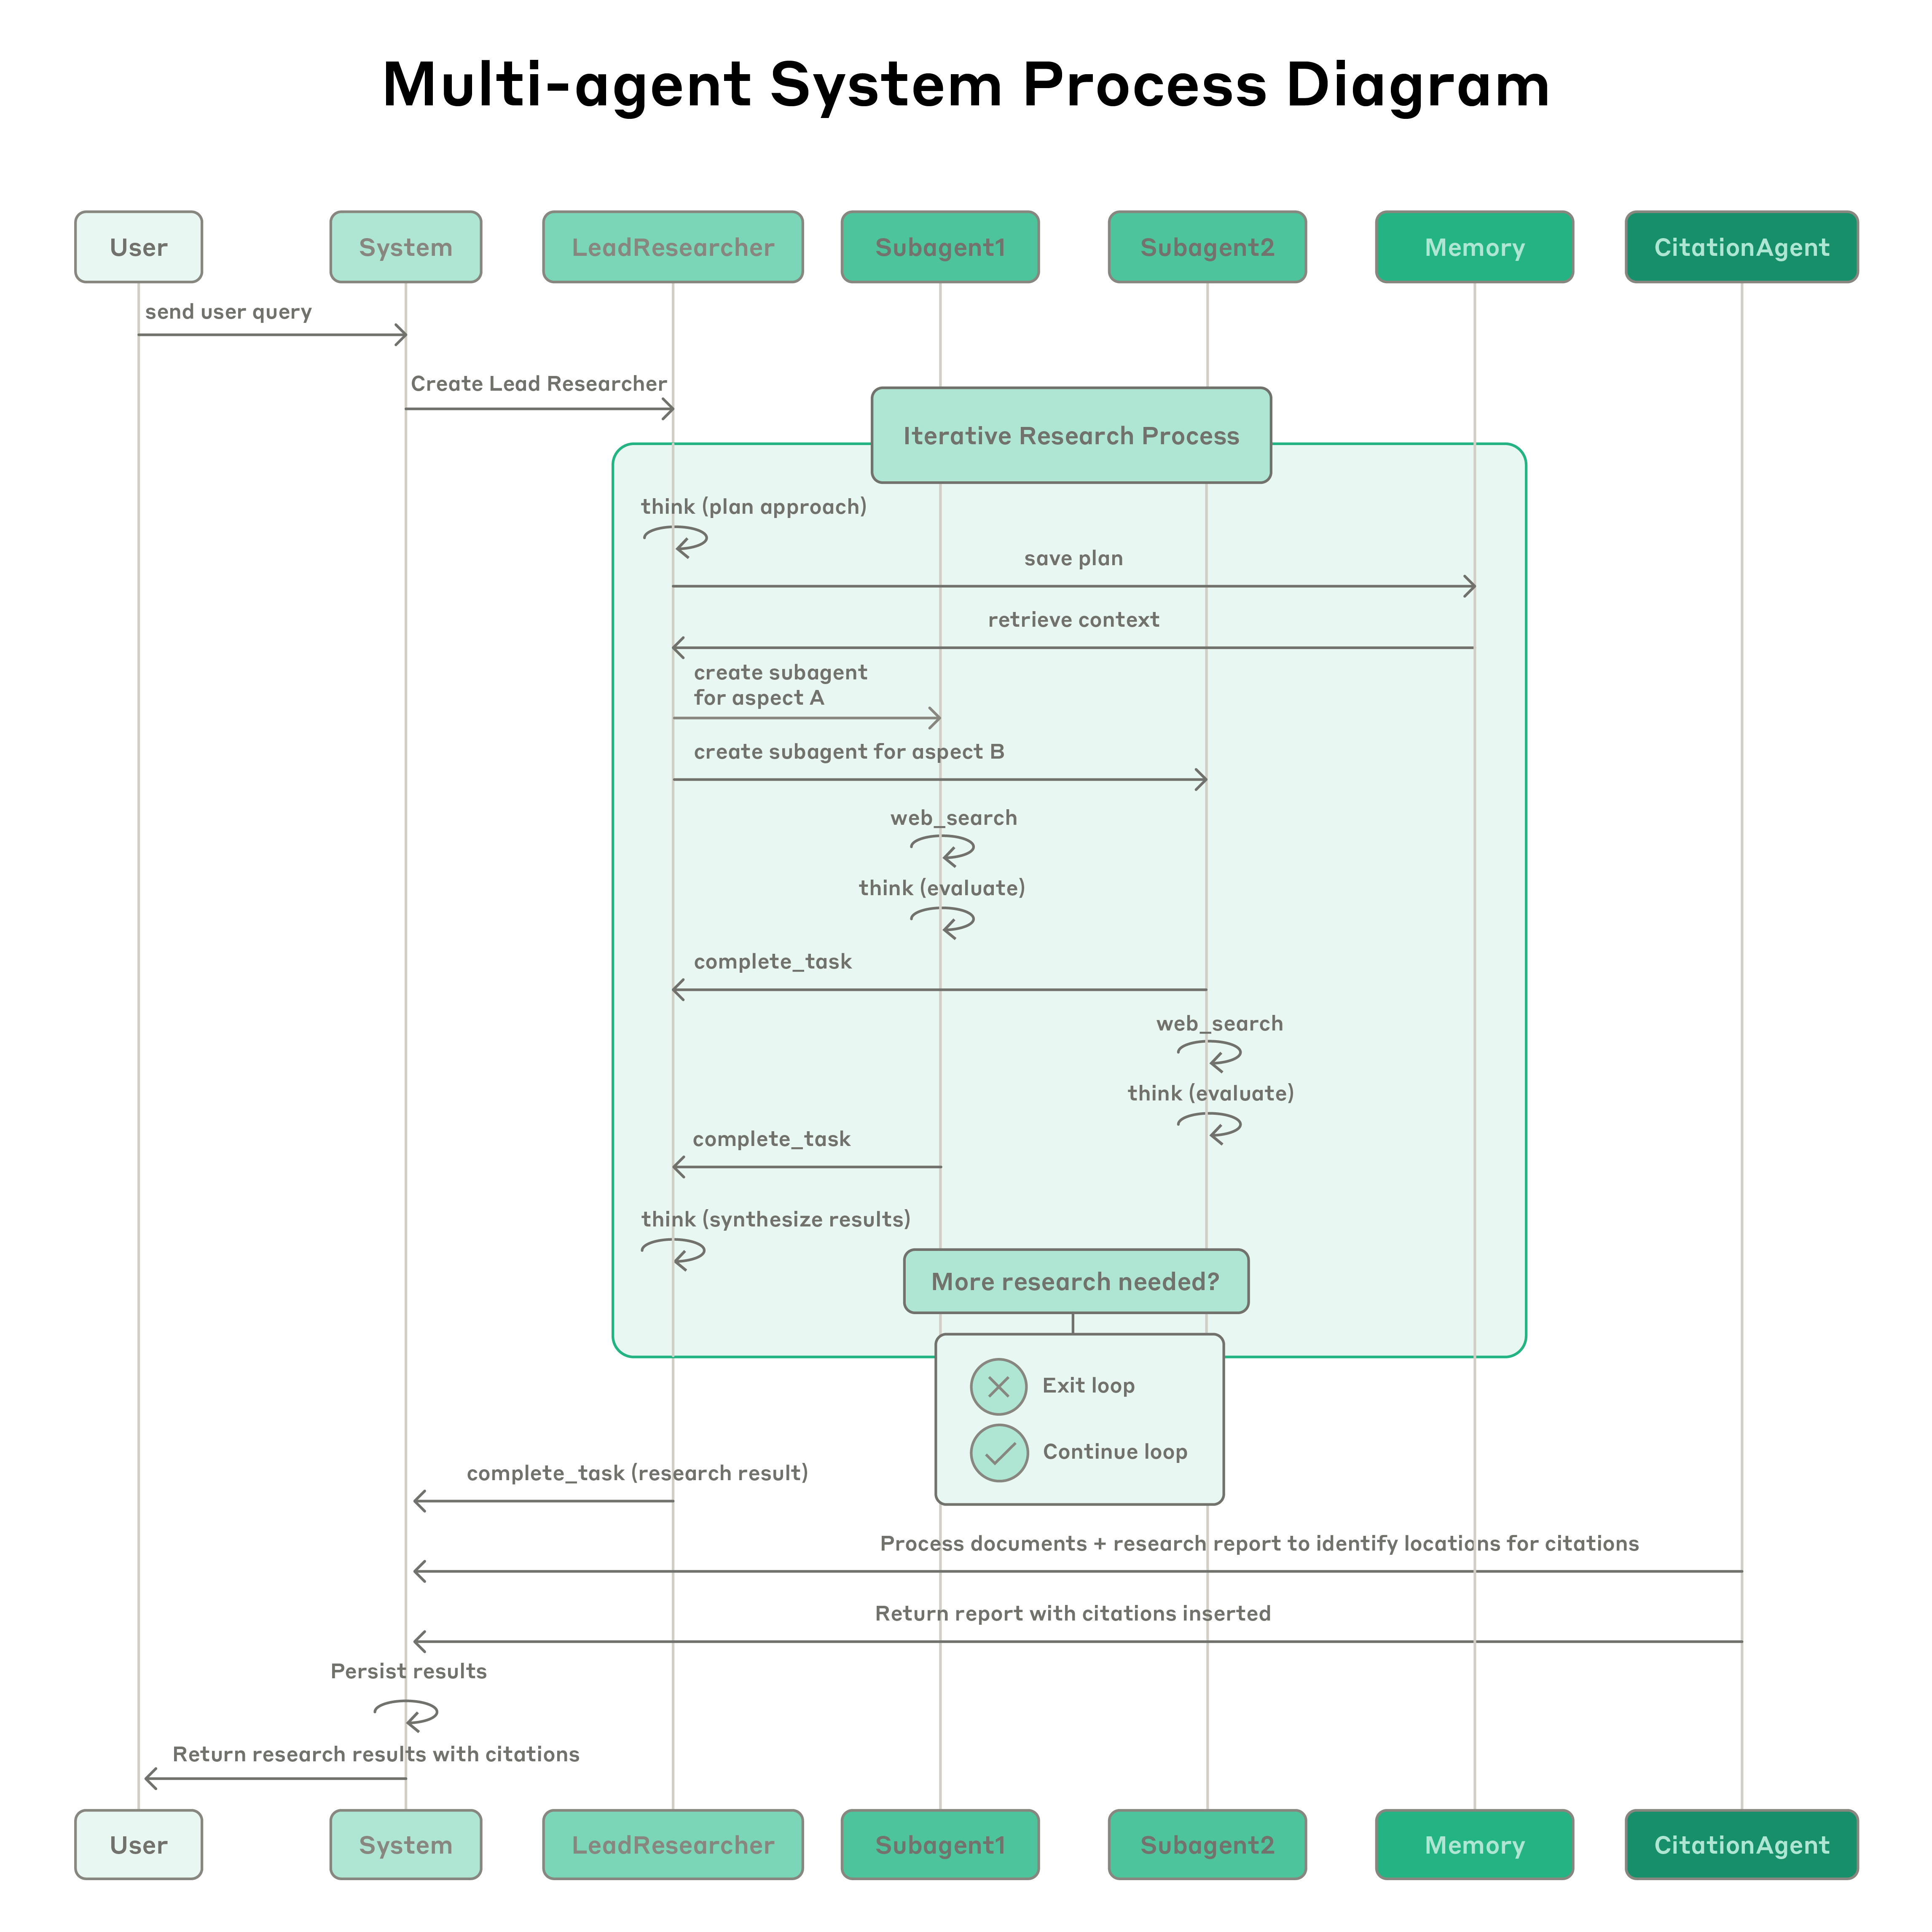
多 Agent 系统与单 Agent 系统存在一些关键差异,其中之一就是协调复杂度会迅速增长。早期的 Agent 曾出现这样的错误:为一个简单查询创建 50 个子 Agent,为寻找根本不存在的来源而无休止地搜索网络,以及用过多的进展更新干扰彼此。由于每个 Agent 都受提示词引导,提示词工程成了我们改善这些行为的主要手段。下面是我们在为 Agent 编写提示词时学到的一些原则:
Multi-agent systems have key differences from single-agent systems, including a rapid growth in coordination complexity. Early agents made errors like spawning 50 subagents for simple queries, scouring the web endlessly for nonexistent sources, and distracting each other with excessive updates. Since each agent is steered by a prompt, prompt engineering was our primary lever for improving these behaviors. Below are some principles we learned for prompting agents:
- 像你的 Agent 一样思考。要迭代提示词,必须理解它们的实际影响。为此,我们使用 Console 搭建了模拟环境,采用与系统完全相同的提示词和工具,然后逐步观察 Agent 如何工作。这立刻暴露出一些失败模式:已经获得足够结果却还在继续、搜索查询过于冗长,或选择了错误工具。有效的提示词依赖于对 Agent 建立准确的心智模型,这能让最有影响力的改动变得显而易见。
- 教会编排者如何委派任务。在我们的系统中,主 Agent 会把查询拆分成子任务,并向子 Agent 描述这些任务。每个子 Agent 都需要明确的目标、输出格式、对工具和信息来源的使用指导,以及清晰的任务边界。缺少详细的任务描述,Agent 就会重复劳动、遗漏工作,或无法找到必要信息。最初,我们允许主 Agent 给出简短的指令,例如“研究半导体短缺”,但发现这些指令往往过于模糊,导致子 Agent 误解任务,或与其他 Agent 执行完全相同的搜索。例如,一个子 Agent 调查的是 2021 年汽车芯片危机,另外两个则重复调查当前的 2025 年供应链,未能形成有效分工。
- 让投入规模与查询复杂度相匹配。Agent 难以判断不同任务应投入多少精力,因此我们在提示词中加入了投入规模规则。简单的事实查找只需 1 个 Agent,调用工具 3—10 次;直接比较可能需要 2—4 个子 Agent,每个调用工具 10—15 次;复杂研究则可能需要超过 10 个职责明确的子 Agent。这些明确指引帮助主 Agent 高效分配资源,避免在简单查询上投入过多,而后者是早期版本中常见的失败模式。
- 工具设计与选择至关重要。Agent 与工具之间的接口,与人机界面同样关键。使用正确的工具能提高效率,而且往往是必不可少的。例如,如果所需上下文只存在于 Slack 中,Agent 却去搜索网络,那么它从一开始就注定会失败。通过 MCP 服务器让模型访问外部工具后,这个问题会更加突出,因为 Agent 会遇到从未见过的工具,而工具描述的质量参差不齐。我们为 Agent 提供了明确的启发式方法,例如先检查所有可用工具,让工具使用方式匹配用户意图,进行广泛的外部探索时搜索网络,以及优先使用专用工具而非通用工具。糟糕的工具描述可能把 Agent 引向完全错误的方向,因此每个工具都需要有独特的用途和清晰的描述。
- 让 Agent 自我改进。我们发现,Claude 4 系列模型可以成为出色的提示词工程师。给它们一段提示词和一种失败模式,它们就能诊断 Agent 失败的原因,并提出改进建议。我们甚至创建了一个工具测试 Agent:给它一个有缺陷的 MCP 工具后,它会尝试使用这个工具,然后重写工具描述以避免失败。通过数十次测试,它发现了一些关键细节和缺陷。这个改善工具易用性的过程,让后续使用新描述的 Agent 将任务完成时间缩短了 40%,因为它们能够避免大多数错误。
- 先广泛探索,再逐步聚焦。搜索策略应当效仿研究专家:先了解全貌,再深入具体问题。Agent 往往默认使用过长、过于具体的查询,结果很少。为克服这一倾向,我们在提示词中要求 Agent 先用简短、宽泛的查询起步,评估可获得的信息,再逐渐缩小范围。
- 引导思考过程。扩展思考模式会让 Claude 在可见的思考过程中输出额外 token,可以充当一块可控的草稿板。主 Agent 利用思考来规划方法,评估哪些工具适合任务、确定查询复杂度和子 Agent 数量,并定义各个子 Agent 的职责。我们的测试表明,扩展思考改善了指令遵循、推理和效率。子 Agent 也会先规划,再在工具返回结果后使用交错思考来评估质量、识别缺口并改进下一次查询。这使子 Agent 能更有效地适应各种任务。
- 并行工具调用显著改善速度与性能。复杂研究任务天然需要探索许多来源。早期 Agent 采用串行搜索,速度慢得令人难以忍受。为加快速度,我们引入了两种并行化方式:(1)主 Agent 并行启动 3—5 个子 Agent,而非串行启动;(2)子 Agent 并行使用至少 3 个工具。对于复杂查询,这些改动将研究时间最多缩短了 90%,让 Research 能在几分钟而非几小时内完成更多工作,同时覆盖比其他系统更多的信息。
- Think like your agents. To iterate on prompts, you must understand their effects. To help us do this, we built simulations using our Console with the exact prompts and tools from our system, then watched agents work step-by-step. This immediately revealed failure modes: agents continuing when they already had sufficient results, using overly verbose search queries, or selecting incorrect tools. Effective prompting relies on developing an accurate mental model of the agent, which can make the most impactful changes obvious.
- Teach the orchestrator how to delegate. In our system, the lead agent decomposes queries into subtasks and describes them to subagents. Each subagent needs an objective, an output format, guidance on the tools and sources to use, and clear task boundaries. Without detailed task descriptions, agents duplicate work, leave gaps, or fail to find necessary information. We started by allowing the lead agent to give simple, short instructions like 'research the semiconductor shortage,' but found these instructions often were vague enough that subagents misinterpreted the task or performed the exact same searches as other agents. For instance, one subagent explored the 2021 automotive chip crisis while 2 others duplicated work investigating current 2025 supply chains, without an effective division of labor.
- Scale effort to query complexity. Agents struggle to judge appropriate effort for different tasks, so we embedded scaling rules in the prompts. Simple fact-finding requires just 1 agent with 3-10 tool calls, direct comparisons might need 2-4 subagents with 10-15 calls each, and complex research might use more than 10 subagents with clearly divided responsibilities. These explicit guidelines help the lead agent allocate resources efficiently and prevent overinvestment in simple queries, which was a common failure mode in our early versions.
- Tool design and selection are critical. Agent-tool interfaces are as critical as human-computer interfaces. Using the right tool is efficient—often, it’s strictly necessary. For instance, an agent searching the web for context that only exists in Slack is doomed from the start. With MCP servers that give the model access to external tools, this problem compounds, as agents encounter unseen tools with descriptions of wildly varying quality. We gave our agents explicit heuristics: for example, examine all available tools first, match tool usage to user intent, search the web for broad external exploration, or prefer specialized tools over generic ones. Bad tool descriptions can send agents down completely wrong paths, so each tool needs a distinct purpose and a clear description.
- Let agents improve themselves. We found that the Claude 4 models can be excellent prompt engineers. When given a prompt and a failure mode, they are able to diagnose why the agent is failing and suggest improvements. We even created a tool-testing agent—when given a flawed MCP tool, it attempts to use the tool and then rewrites the tool description to avoid failures. By testing the tool dozens of times, this agent found key nuances and bugs. This process for improving tool ergonomics resulted in a 40% decrease in task completion time for future agents using the new description, because they were able to avoid most mistakes.
- Start wide, then narrow down. Search strategy should mirror expert human research: explore the landscape before drilling into specifics. Agents often default to overly long, specific queries that return few results. We counteracted this tendency by prompting agents to start with short, broad queries, evaluate what’s available, then progressively narrow focus.
- Guide the thinking process. Extended thinking mode, which leads Claude to output additional tokens in a visible thinking process, can serve as a controllable scratchpad. The lead agent uses thinking to plan its approach, assessing which tools fit the task, determining query complexity and subagent count, and defining each subagent’s role. Our testing showed that extended thinking improved instruction-following, reasoning, and efficiency. Subagents also plan, then use interleaved thinking after tool results to evaluate quality, identify gaps, and refine their next query. This makes subagents more effective in adapting to any task.
- Parallel tool calling transforms speed and performance. Complex research tasks naturally involve exploring many sources. Our early agents executed sequential searches, which was painfully slow. For speed, we introduced two kinds of parallelization: (1) the lead agent spins up 3-5 subagents in parallel rather than serially; (2) the subagents use 3+ tools in parallel. These changes cut research time by up to 90% for complex queries, allowing Research to do more work in minutes instead of hours while covering more information than other systems.
我们的提示词策略着重于让 Agent 掌握有效的启发式方法,而非僵硬的规则。我们研究了熟练的人类研究者如何处理研究任务,并将这些策略写入提示词,例如把难题拆成较小的任务、仔细评估来源质量、根据新信息调整搜索方法,以及判断何时应该重视深度(详细调查一个主题),何时应该重视广度(并行探索多个主题)。我们也通过设置明确的约束,主动减轻意外副作用,防止 Agent 失控。最后,我们着力建立由可观测性和测试用例支持的快速迭代循环。
Our prompting strategy focuses on instilling good heuristics rather than rigid rules. We studied how skilled humans approach research tasks and encoded these strategies in our prompts—strategies like decomposing difficult questions into smaller tasks, carefully evaluating the quality of sources, adjusting search approaches based on new information, and recognizing when to focus on depth (investigating one topic in detail) vs. breadth (exploring many topics in parallel). We also proactively mitigated unintended side effects by setting explicit guardrails to prevent the agents from spiraling out of control. Finally, we focused on a fast iteration loop with observability and test cases.
有效评测 Agent
Effective evaluation of agents
构建可靠的 AI 应用离不开良好的评测,Agent 也不例外。不过,评测多 Agent 系统面临独特挑战。传统评测往往假定 AI 每次都遵循相同的步骤:给定输入 X,系统应沿着路径 Y 产生输出 Z。但多 Agent 系统并不是这样运行的。即使起点完全一致,Agent 也可能通过截然不同但同样有效的路径达成目标。一个 Agent 可能搜索三个来源,另一个则搜索十个;它们也可能使用不同工具找到同一个答案。由于我们并不总是知道哪些步骤才是正确的,通常不能仅仅检查 Agent 是否遵循了预先规定的“正确”步骤。我们需要灵活的评测方法,既判断 Agent 是否取得正确结果,也判断它是否遵循了合理的过程。
Good evaluations are essential for building reliable AI applications, and agents are no different. However, evaluating multi-agent systems presents unique challenges. Traditional evaluations often assume that the AI follows the same steps each time: given input X, the system should follow path Y to produce output Z. But multi-agent systems don't work this way. Even with identical starting points, agents might take completely different valid paths to reach their goal. One agent might search three sources while another searches ten, or they might use different tools to find the same answer. Because we don’t always know what the right steps are, we usually can't just check if agents followed the “correct” steps we prescribed in advance. Instead, we need flexible evaluation methods that judge whether agents achieved the right outcomes while also following a reasonable process.
立即从小样本开始评测。在 Agent 开发早期,由于存在大量容易取得的改进,改动往往会带来显著影响。一次提示词调整可能把成功率从 30% 提高到 80%。效果差异如此之大时,只需几个测试用例就能看出变化。我们最初使用了一组大约 20 个查询,代表真实的使用模式。测试这些查询,往往就能清楚看到改动的影响。我们经常听到 AI 开发团队说,他们推迟建立评测,是因为认为只有包含数百个测试用例的大规模评测才有用。不过,最好立即用几个示例开展小规模测试,而不是等到能够建立更全面的评测时再开始。
Start evaluating immediately with small samples. In early agent development, changes tend to have dramatic impacts because there is abundant low-hanging fruit. A prompt tweak might boost success rates from 30% to 80%. With effect sizes this large, you can spot changes with just a few test cases. We started with a set of about 20 queries representing real usage patterns. Testing these queries often allowed us to clearly see the impact of changes. We often hear that AI developer teams delay creating evals because they believe that only large evals with hundreds of test cases are useful. However, it’s best to start with small-scale testing right away with a few examples, rather than delaying until you can build more thorough evals.
方法得当时,以大语言模型为裁判的评测可以扩展规模。研究输出是自由形式的文本,而且很少只有一个正确答案,因此很难用程序评测。大语言模型天然适合为输出评分。我们使用一个大语言模型裁判,按照评分标准评估每份输出:事实准确性(主张是否与来源一致?)、引用准确性(引用的来源是否对应所述主张?)、完整性(是否涵盖了用户要求的所有方面?)、来源质量(是否优先使用一手来源,而非质量较低的二手来源?),以及工具效率(是否以合理的次数使用了正确工具?)。我们曾尝试用多个裁判分别评估各个部分,但发现,用一个提示词进行一次大语言模型调用,输出 0.0—1.0 的分数和通过或不通过的判定,结果最一致,也最符合人类判断。当评测用例确实有明确答案时,这种方法尤其有效,因为只需让大语言模型裁判检查答案是否正确即可,例如是否准确列出了研发预算最高的三家制药公司。使用大语言模型作为裁判,使我们能够规模化评估数百份输出。
LLM-as-judge evaluation scales when done well. Research outputs are difficult to evaluate programmatically, since they are free-form text and rarely have a single correct answer. LLMs are a natural fit for grading outputs. We used an LLM judge that evaluated each output against criteria in a rubric: factual accuracy (do claims match sources?), citation accuracy (do the cited sources match the claims?), completeness (are all requested aspects covered?), source quality (did it use primary sources over lower-quality secondary sources?), and tool efficiency (did it use the right tools a reasonable number of times?). We experimented with multiple judges to evaluate each component, but found that a single LLM call with a single prompt outputting scores from 0.0-1.0 and a pass-fail grade was the most consistent and aligned with human judgements. This method was especially effective when the eval test cases did have a clear answer, and we could use the LLM judge to simply check if the answer was correct (i.e. did it accurately list the pharma companies with the top 3 largest R&D budgets?). Using an LLM as a judge allowed us to scalably evaluate hundreds of outputs.
人工评测能发现自动化遗漏的问题。测试 Agent 的人会发现评测没有覆盖的边界情况,包括异常查询上的幻觉回答、系统故障,或信息来源选择中细微的偏差。在我们的案例中,人工测试人员发现,早期 Agent 总是选择经过搜索引擎优化的内容农场,而不选择学术 PDF 或个人博客等权威但搜索排名较低的来源。在提示词中加入评估来源质量的启发式方法,有助于解决这个问题。即便自动化评测已经普及,手动测试依然不可或缺。
Human evaluation catches what automation misses. People testing agents find edge cases that evals miss. These include hallucinated answers on unusual queries, system failures, or subtle source selection biases. In our case, human testers noticed that our early agents consistently chose SEO-optimized content farms over authoritative but less highly-ranked sources like academic PDFs or personal blogs. Adding source quality heuristics to our prompts helped resolve this issue. Even in a world of automated evaluations, manual testing remains essential.
多 Agent 系统会产生涌现行为,也就是未经专门编程却自行出现的行为。例如,对主 Agent 的微小改动,就可能以不可预测的方式改变子 Agent 的行为。要取得成功,需要理解交互模式,而不只是单个 Agent 的行为。因此,对这些 Agent 最有效的提示词,不只是严格的指令,更是规定了分工、解决问题的方法和投入预算的协作框架。做好这件事,需要精心设计提示词和工具、可靠的启发式方法、可观测性,以及紧密的反馈循环。 我们系统中的提示词示例,参见 Cookbook 中的开源提示词。
Multi-agent systems have emergent behaviors, which arise without specific programming. For instance, small changes to the lead agent can unpredictably change how subagents behave. Success requires understanding interaction patterns, not just individual agent behavior. Therefore, the best prompts for these agents are not just strict instructions, but frameworks for collaboration that define the division of labor, problem-solving approaches, and effort budgets. Getting this right relies on careful prompting and tool design, solid heuristics, observability, and tight feedback loops. See the open-source prompts in our Cookbook for example prompts from our system.
生产可靠性与工程挑战
Production reliability and engineering challenges
在传统软件中,一个缺陷可能破坏某项功能、降低性能,或导致服务中断。在 Agent 系统中,微小改动会层层传导,最终引起巨大的行为变化,因此,为必须在长期运行的进程中维持状态的复杂 Agent 编写代码,会变得格外困难。
In traditional software, a bug might break a feature, degrade performance, or cause outages. In agentic systems, minor changes cascade into large behavioral changes, which makes it remarkably difficult to write code for complex agents that must maintain state in a long-running process.
Agent 有状态,而且错误会累积。Agent 可以运行很长时间,并在大量工具调用之间持续维护状态。这意味着我们需要让代码能够持久可靠地执行,并处理沿途发生的错误。如果没有有效的缓解措施,轻微的系统故障对 Agent 也可能是灾难性的。出错后,我们不能简单地从头重启:重新开始既昂贵,也会令用户沮丧。因此,我们构建了能够从 Agent 出错时所在位置继续运行的系统。我们还利用模型的智能来妥善处理问题:例如,告知 Agent 某个工具正在发生故障,并让它自行调整,效果出乎意料地好。我们把基于 Claude 的 AI Agent 所具有的适应能力,与重试逻辑、定期检查点等确定性的保障机制结合起来。
Agents are stateful and errors compound. Agents can run for long periods of time, maintaining state across many tool calls. This means we need to durably execute code and handle errors along the way. Without effective mitigations, minor system failures can be catastrophic for agents. When errors occur, we can't just restart from the beginning: restarts are expensive and frustrating for users. Instead, we built systems that can resume from where the agent was when the errors occurred. We also use the model’s intelligence to handle issues gracefully: for instance, letting the agent know when a tool is failing and letting it adapt works surprisingly well. We combine the adaptability of AI agents built on Claude with deterministic safeguards like retry logic and regular checkpoints.
新方法有助于调试。Agent 会动态决策,即使提示词完全相同,各次运行也不具有确定性。这让调试更加困难。例如,用户会反馈 Agent“找不到显而易见的信息”,但我们看不到原因。是搜索查询写得不好?选择的来源质量差?还是工具发生了故障?加入完整的生产执行轨迹记录后,我们才能诊断 Agent 为什么失败,并系统地修复问题。除了标准的可观测性,我们还监测 Agent 的决策模式和交互结构,同时不监测单次对话的内容,以维护用户隐私。这种较高层次的可观测性,帮助我们诊断根因、发现意外行为,并修复常见故障。
Debugging benefits from new approaches. Agents make dynamic decisions and are non-deterministic between runs, even with identical prompts. This makes debugging harder. For instance, users would report agents “not finding obvious information,” but we couldn't see why. Were the agents using bad search queries? Choosing poor sources? Hitting tool failures? Adding full production tracing let us diagnose why agents failed and fix issues systematically. Beyond standard observability, we monitor agent decision patterns and interaction structures—all without monitoring the contents of individual conversations, to maintain user privacy. This high-level observability helped us diagnose root causes, discover unexpected behaviors, and fix common failures.
部署需要谨慎协调。Agent 系统由提示词、工具和执行逻辑组成,是高度依赖状态、几乎持续运行的网络。这意味着,每次部署更新时,Agent 都可能处于执行过程中的任意位置。因此,我们需要避免出于好意的代码改动破坏正在运行的 Agent。我们无法同时把每个 Agent 都更新到新版本,而是采用彩虹部署:让新旧版本同时运行,并逐步将流量从旧版本切换到新版本,以避免干扰正在运行的 Agent。
Deployment needs careful coordination. Agent systems are highly stateful webs of prompts, tools, and execution logic that run almost continuously. This means that whenever we deploy updates, agents might be anywhere in their process. We therefore need to prevent our well-meaning code changes from breaking existing agents. We can’t update every agent to the new version at the same time. Instead, we use rainbow deployments to avoid disrupting running agents, by gradually shifting traffic from old to new versions while keeping both running simultaneously.
同步执行会造成瓶颈。目前,主 Agent 以同步方式执行子 Agent,每次都要等一组子 Agent 全部完成后才继续。这简化了协调,但也在 Agent 之间的信息流动上造成了瓶颈。例如,主 Agent 无法引导子 Agent,子 Agent 之间无法协调,整个系统还可能因为等待某一个子 Agent 完成搜索而阻塞。异步执行可以进一步提高并行度:让 Agent 并发工作,并在需要时创建新的子 Agent。但这种异步性也会增加子 Agent 之间结果协调、状态一致性和错误传播方面的挑战。随着模型能够处理时间更长、更复杂的研究任务,我们预计性能收益将足以抵偿这些复杂性。
Synchronous execution creates bottlenecks. Currently, our lead agents execute subagents synchronously, waiting for each set of subagents to complete before proceeding. This simplifies coordination, but creates bottlenecks in the information flow between agents. For instance, the lead agent can’t steer subagents, subagents can’t coordinate, and the entire system can be blocked while waiting for a single subagent to finish searching. Asynchronous execution would enable additional parallelism: agents working concurrently and creating new subagents when needed. But this asynchronicity adds challenges in result coordination, state consistency, and error propagation across the subagents. As models can handle longer and more complex research tasks, we expect the performance gains will justify the complexity.
结语
Conclusion
构建 AI Agent 时,最后一段路往往占据了整个旅程的大部分。在开发者机器上能运行的代码库,需要大量工程工作才能变成可靠的生产系统。Agent 系统中的错误具有累积效应,因此在传统软件中只是小问题的状况,也可能让 Agent 彻底偏离轨道。一个步骤失败,就可能使 Agent 探索完全不同的路径,带来不可预测的结果。出于本文所述的种种原因,原型与生产系统之间的差距,往往比预想的更大。
When building AI agents, the last mile often becomes most of the journey. Codebases that work on developer machines require significant engineering to become reliable production systems. The compound nature of errors in agentic systems means that minor issues for traditional software can derail agents entirely. One step failing can cause agents to explore entirely different trajectories, leading to unpredictable outcomes. For all the reasons described in this post, the gap between prototype and production is often wider than anticipated.
尽管存在这些挑战,多 Agent 系统已证明自己在开放式研究任务中的价值。用户表示,Claude 帮助他们发现了此前未曾考虑的商业机会,理清了复杂的医疗选择,解决了棘手的技术缺陷,还通过发现他们独自研究时找不到的联系,最多节省了数天的工作。借助精心的工程设计、全面测试、注重细节的提示词与工具设计、稳健的运维实践,以及研究、产品和工程团队之间的紧密协作,多 Agent 研究系统可以在大规模运行中保持可靠;而这些团队需要深入理解当前 Agent 的能力。我们已经看到,这类系统正在改变人们解决复杂问题的方式。
Despite these challenges, multi-agent systems have proven valuable for open-ended research tasks. Users have said that Claude helped them find business opportunities they hadn’t considered, navigate complex healthcare options, resolve thorny technical bugs, and save up to days of work by uncovering research connections they wouldn't have found alone. Multi-agent research systems can operate reliably at scale with careful engineering, comprehensive testing, detail-oriented prompt and tool design, robust operational practices, and tight collaboration between research, product, and engineering teams who have a strong understanding of current agent capabilities. We're already seeing these systems transform how people solve complex problems.
致谢
Acknowlegements
本文由 Jeremy Hadfield、Barry Zhang、Kenneth Lien、Florian Scholz、Jeremy Fox 和 Daniel Ford 撰写。这项工作凝聚了 Anthropic 多个团队的共同努力,是他们让 Research 功能成为现实。特别感谢 Anthropic 应用工程团队,他们的投入让这个复杂的多 Agent 系统得以投入生产。我们也感谢早期用户提供的宝贵反馈。
Written by Jeremy Hadfield, Barry Zhang, Kenneth Lien, Florian Scholz, Jeremy Fox, and Daniel Ford. This work reflects the collective efforts of several teams across Anthropic who made the Research feature possible. Special thanks go to the Anthropic apps engineering team, whose dedication brought this complex multi-agent system to production. We're also grateful to our early users for their excellent feedback.
附录
Appendix
下面补充一些关于多 Agent 系统的实用建议。
Below are some additional miscellaneous tips for multi-agent systems.
对经过多轮交互修改状态的 Agent 进行最终状态评测。评测在多轮对话中修改持久状态的 Agent,面临独特的挑战。与只读研究任务不同,每个动作都可能改变后续步骤所处的环境,产生传统评测方法难以处理的依赖关系。我们发现,把重点放在最终状态评测而非逐轮分析上,效果很好。与其判断 Agent 是否遵循了某个特定过程,不如评估它是否达到了正确的最终状态。这种方法承认 Agent 可能通过不同路径实现同一目标,同时仍然确保它交付预期结果。对于复杂工作流,应把评测拆成若干独立检查点,检查到这些位置时是否已发生特定状态变化,而不是试图验证每一个中间步骤。
End-state evaluation of agents that mutate state over many turns. Evaluating agents that modify persistent state across multi-turn conversations presents unique challenges. Unlike read-only research tasks, each action can change the environment for subsequent steps, creating dependencies that traditional evaluation methods struggle to handle. We found success focusing on end-state evaluation rather than turn-by-turn analysis. Instead of judging whether the agent followed a specific process, evaluate whether it achieved the correct final state. This approach acknowledges that agents may find alternative paths to the same goal while still ensuring they deliver the intended outcome. For complex workflows, break evaluation into discrete checkpoints where specific state changes should have occurred, rather than attempting to validate every intermediate step.
长程对话管理。生产环境中的 Agent 经常参与长达数百轮的对话,需要周密的上下文管理策略。随着对话延长,标准上下文窗口会不够用,因而需要智能压缩和记忆机制。我们实现了这样的模式:Agent 先总结已完成的工作阶段,将关键信息存入外部记忆,然后再推进新任务。接近上下文上限时,Agent 可以创建上下文干净的新子 Agent,并通过精心交接保持工作连续性。此外,它们还可以从记忆中检索研究计划等已存储的上下文,而不会在到达上下文上限时丢失之前的工作。这种分布式方法既能防止上下文溢出,也能在长时间交互中维持对话的连贯性。
Long-horizon conversation management. Production agents often engage in conversations spanning hundreds of turns, requiring careful context management strategies. As conversations extend, standard context windows become insufficient, necessitating intelligent compression and memory mechanisms. We implemented patterns where agents summarize completed work phases and store essential information in external memory before proceeding to new tasks. When context limits approach, agents can spawn fresh subagents with clean contexts while maintaining continuity through careful handoffs. Further, they can retrieve stored context like the research plan from their memory rather than losing previous work when reaching the context limit. This distributed approach prevents context overflow while preserving conversation coherence across extended interactions.
让子 Agent 把输出写入文件系统,尽量减少“传话游戏”造成的信息失真。对于某些类型的结果,子 Agent 可以直接输出,绕过主协调者,同时提高保真度和性能。不要要求子 Agent 通过主 Agent 传递所有内容,而应实现产物系统,让专门的 Agent 创建能够独立持久保存的输出。子 Agent 调用工具,把工作成果存储到外部系统,再将轻量的引用传回协调者。这可以避免多阶段处理中的信息损失,并减少在对话历史中复制大段输出所带来的 token 开销。这种模式尤其适用于代码、报告或数据可视化等结构化输出:子 Agent 的专用提示词所产生的结果,比经过通用协调者再处理后的结果更好。
Subagent output to a filesystem to minimize the ‘game of telephone.’ Direct subagent outputs can bypass the main coordinator for certain types of results, improving both fidelity and performance. Rather than requiring subagents to communicate everything through the lead agent, implement artifact systems where specialized agents can create outputs that persist independently. Subagents call tools to store their work in external systems, then pass lightweight references back to the coordinator. This prevents information loss during multi-stage processing and reduces token overhead from copying large outputs through conversation history. The pattern works particularly well for structured outputs like code, reports, or data visualizations where the subagent's specialized prompt produces better results than filtering through a general coordinator.
想了解更多?
Want to learn more?
探索课程
Explore courses
— 全文完 —
原文来自 Anthropic,中文为非官方学习译文。
查看原始出处 ↗