核心要点
Key Takeaways
- 许多任务并不需要前沿级别的智能。在我们的实验中,相比基线,模型路由将每项编程任务的成本中位数降低了 64%,同时质量没有明显变化。
- 有效的模型路由器应当位于运行框架中,而不是通用网关中。选择正确的模型,需要领域与任务上下文。这些上下文已经由运行框架组织起来,而网关通常并不具备。
- 有效的路由器设计,以可观测性和评测为基础。它要求我们理解 Agent 的任务空间,研究模型表现,并明确成功标准。
- Many tasks don't need frontier intelligence. In our experiments, model routing cut median cost per coding task by 64% compared with the baseline, with no noticeable change in quality.
- An effective model router belongs in the harness, not a generic gateway. Choosing the right model requires domain and task context that the harness already assembles, and a gateway typically lacks.
- Effective router design is rooted in observability and evals. It requires an understanding of an agent's task space, model performance research, and clear success criteria.
前沿 LLM 的价格仍然高昂。随着 Agent 日益普及并大规模运行,这种成本将难以承受。好在,大多数 Agent 并不是每项任务都需要前沿级别的智能。模型实验室自己也这么说:Anthropic 的模型选择指南指出,“对于许多应用,从 Claude Haiku 4.5 这样的速度更快、成本效益更高的模型入手,可能是最优做法。”
Frontier LLMs continue to be expensive. As agents become ubiquitous and operate at massive scale, this is cost prohibitive. Luckily, most agents don't need frontier-level intelligence for every task. Model labs even say so: Anthropic's guide to choosing a model notes that "for many applications, starting with a faster, more cost-effective model like Claude Haiku 4.5 can be the optimal approach."
超过某个程度之后,就会出现收益递减:能力更强的模型带来的质量提升很少,成本和时延却持续上升。好的 Agent 需要实现模型、运行框架与任务之间的匹配:针对具体任务,提供正确的模型与正确的上下文。模型路由器为每项任务选择这样的模型。我们认为,这个路由决策应当属于 Agent 运行框架,而不是通用网关,因为选择正确模型所需的领域和任务上下文,恰恰是运行框架已经组织起来、而网关通常欠缺的内容。
Past a certain point, you hit diminishing returns: a more capable model adds little quality while cost and latency keep climbing. A good agent has model-harness-task fit: the right model with the right context for a given task. A model router picks that model for each task. We believe that routing decision belongs in the agent harness, not a generic gateway, because choosing the right model requires the same domain and task context the harness already assembles and that a gateway typically lacks.
最近,LangChain 每月在编程 Agent 上的开销开始快速上涨,我们切身感受到了这个问题。听到客户表达同样的担忧后,我们着手为开源编程 Agent Open SWE 构建有效的模型路由器。与此前始终使用顶级前沿模型的基线相比,它将每个会话的成本中位数降低了 64%,同时未测得质量变化。本文介绍我们如何构建这个路由器、从中学到了什么,以及你可以如何开始为自己的 Agent 加入模型路由。
We felt this pain recently at LangChain as our monthly coding agent spend started to climb rapidly. Hearing the same concern from customers, we set out to build an effective model router for Open SWE, our open source coding agent. Compared to our previous baseline of always using a top-tier frontier model, it cut median cost per thread by 64% with no measurable change in quality. This post covers how we built the router, what we learned, and how you can get started building model routing into your agents.
第 1 步:理解任务
Step 1: understand the tasks
我们的试验平台是 Open SWE。工程师通过 Slack 和网页界面,用它询问代码库相关问题,并提出代码修改请求。在构建路由器之前,我们需要了解开发者会用 Open SWE 处理哪些类型的任务。我们从 LangSmith 执行轨迹中提取了会话级别的数据:收到的请求类型,以及每个会话的成本和轮数,后两者作为复杂度的近似指标。我们在 LangSmith Custom Apps 中开展探索,直接基于 Open SWE 的执行轨迹构建了一个小型界面。
Our test bed was Open SWE, which our engineers use from Slack and a web UI to ask questions about our codebases and request code changes. Before building a router, we needed to understand the types of tasks that developers use Open SWE for. We pulled thread-level data from LangSmith traces: the kinds of requests coming in, plus the cost and turn count of each thread (as approximate measures of complexity). We did the exploration in LangSmith Custom Apps, with a small interface built directly on top of the Open SWE traces.
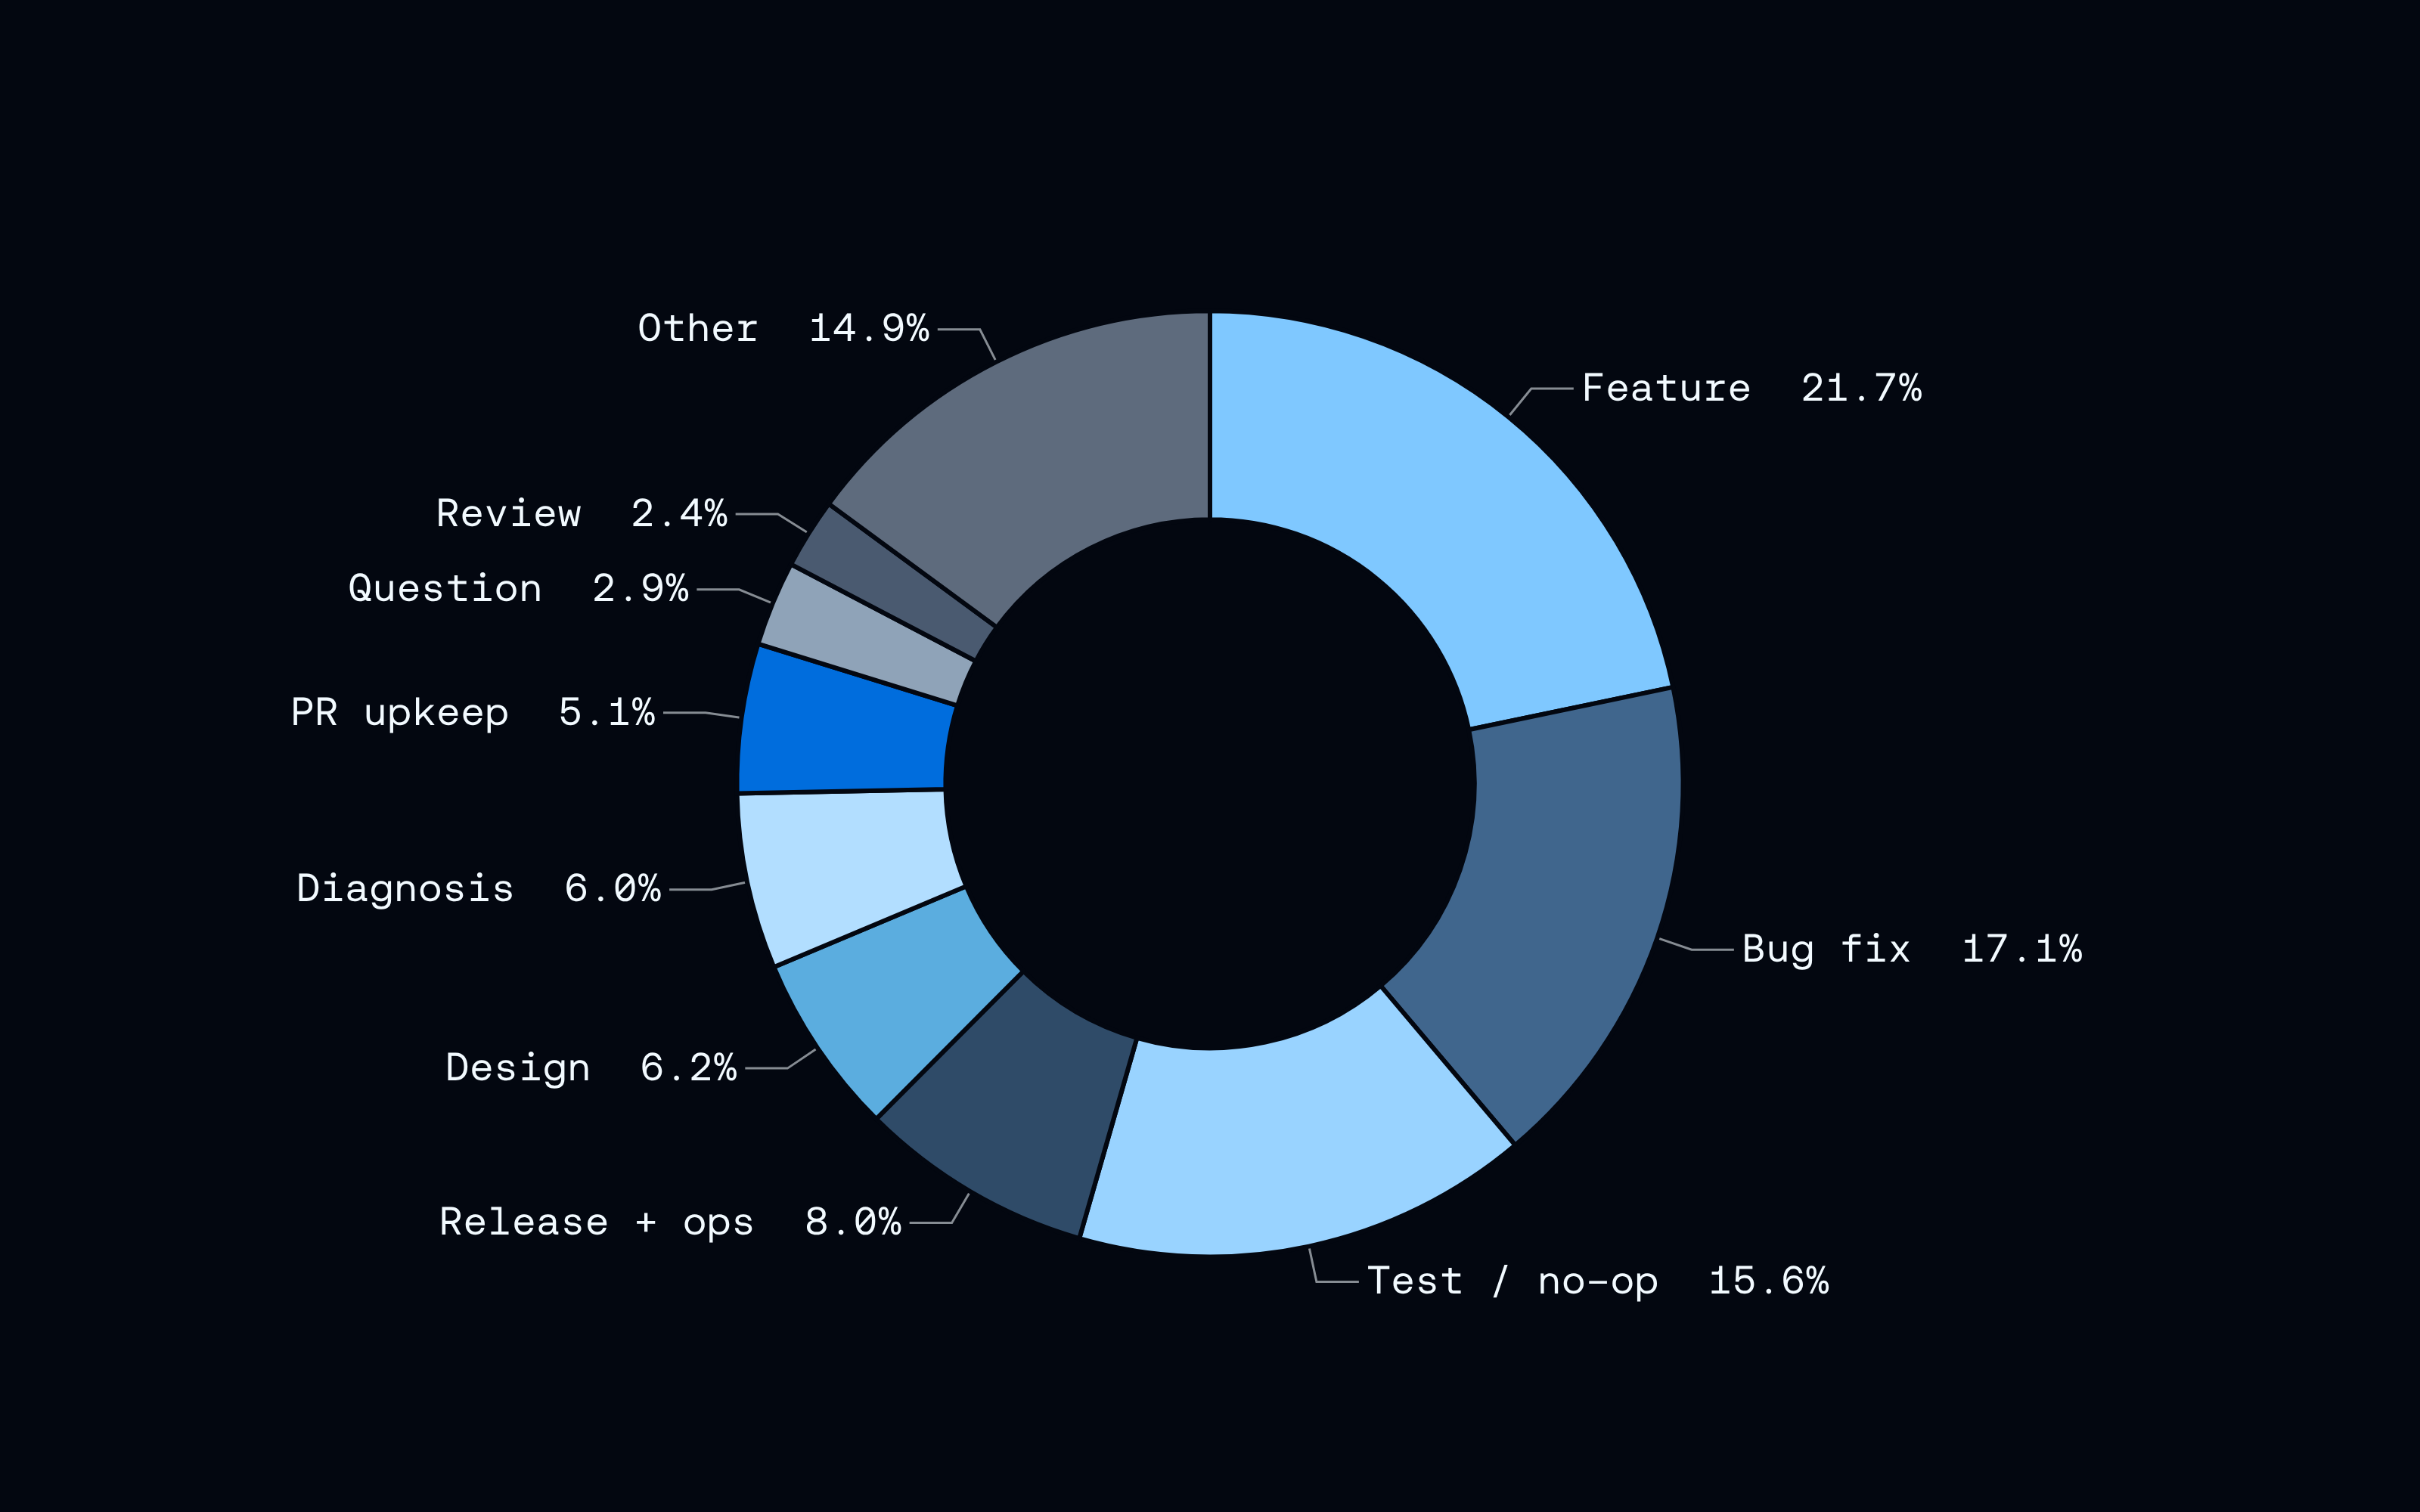
我们选取了一周的交互会话,使用 LLM 分类器为每个会话标注任务类型。LangSmith Insights 也可以帮你对执行轨迹进行这样的分组。代码修改占主导地位:新功能(22%)和缺陷修复(17%)是最大的两组,其次是测试或无实际操作的运行(16%)。分类是根据各会话的标题与元数据进行启发式判断的。
We took a week of interactive threads and labeled each one by task type using an LLM classifier. LangSmith Insights can also do this kind of grouping across your traces for you. Code changes dominated: new features (22%) and bug fixes (17%) were the two largest groups, followed by test or no-op runs (16%). Categories are heuristics based on each thread's title and metadata.
我们还研究了不同任务类型对应的 Agent 执行轨迹特征有何差异。我们发现,与功能开发调研相关的会话往往更长,成本和轮数中位数更高。与测试和发布流程相关的会话,则通常相对较短、成本较低。
We also investigated how agent trace characteristics differed based on task type. We discovered that threads associated with feature work investigations tended to be longer, with higher cost and median turn count. Threads associated with testing and release procedures tended to be relatively short and inexpensive.
为了判断“复杂度”,我们同时使用总成本和调用次数作为信号:成本较直接地反映复杂度,因为更大的任务会使用更多 token;调用次数则更需要具体分析,因为调用次数多,既可能意味着任务更难,也可能意味着模型需要后续交互才能完成任务。
In order to judge “complexity”, we used both total cost and invocation as signals: cost tracks complexity fairly directly, since bigger tasks use more tokens, while invocations are more nuanced, since a high count can mean a harder task or a model that needed follow-ups to accomplish the task.
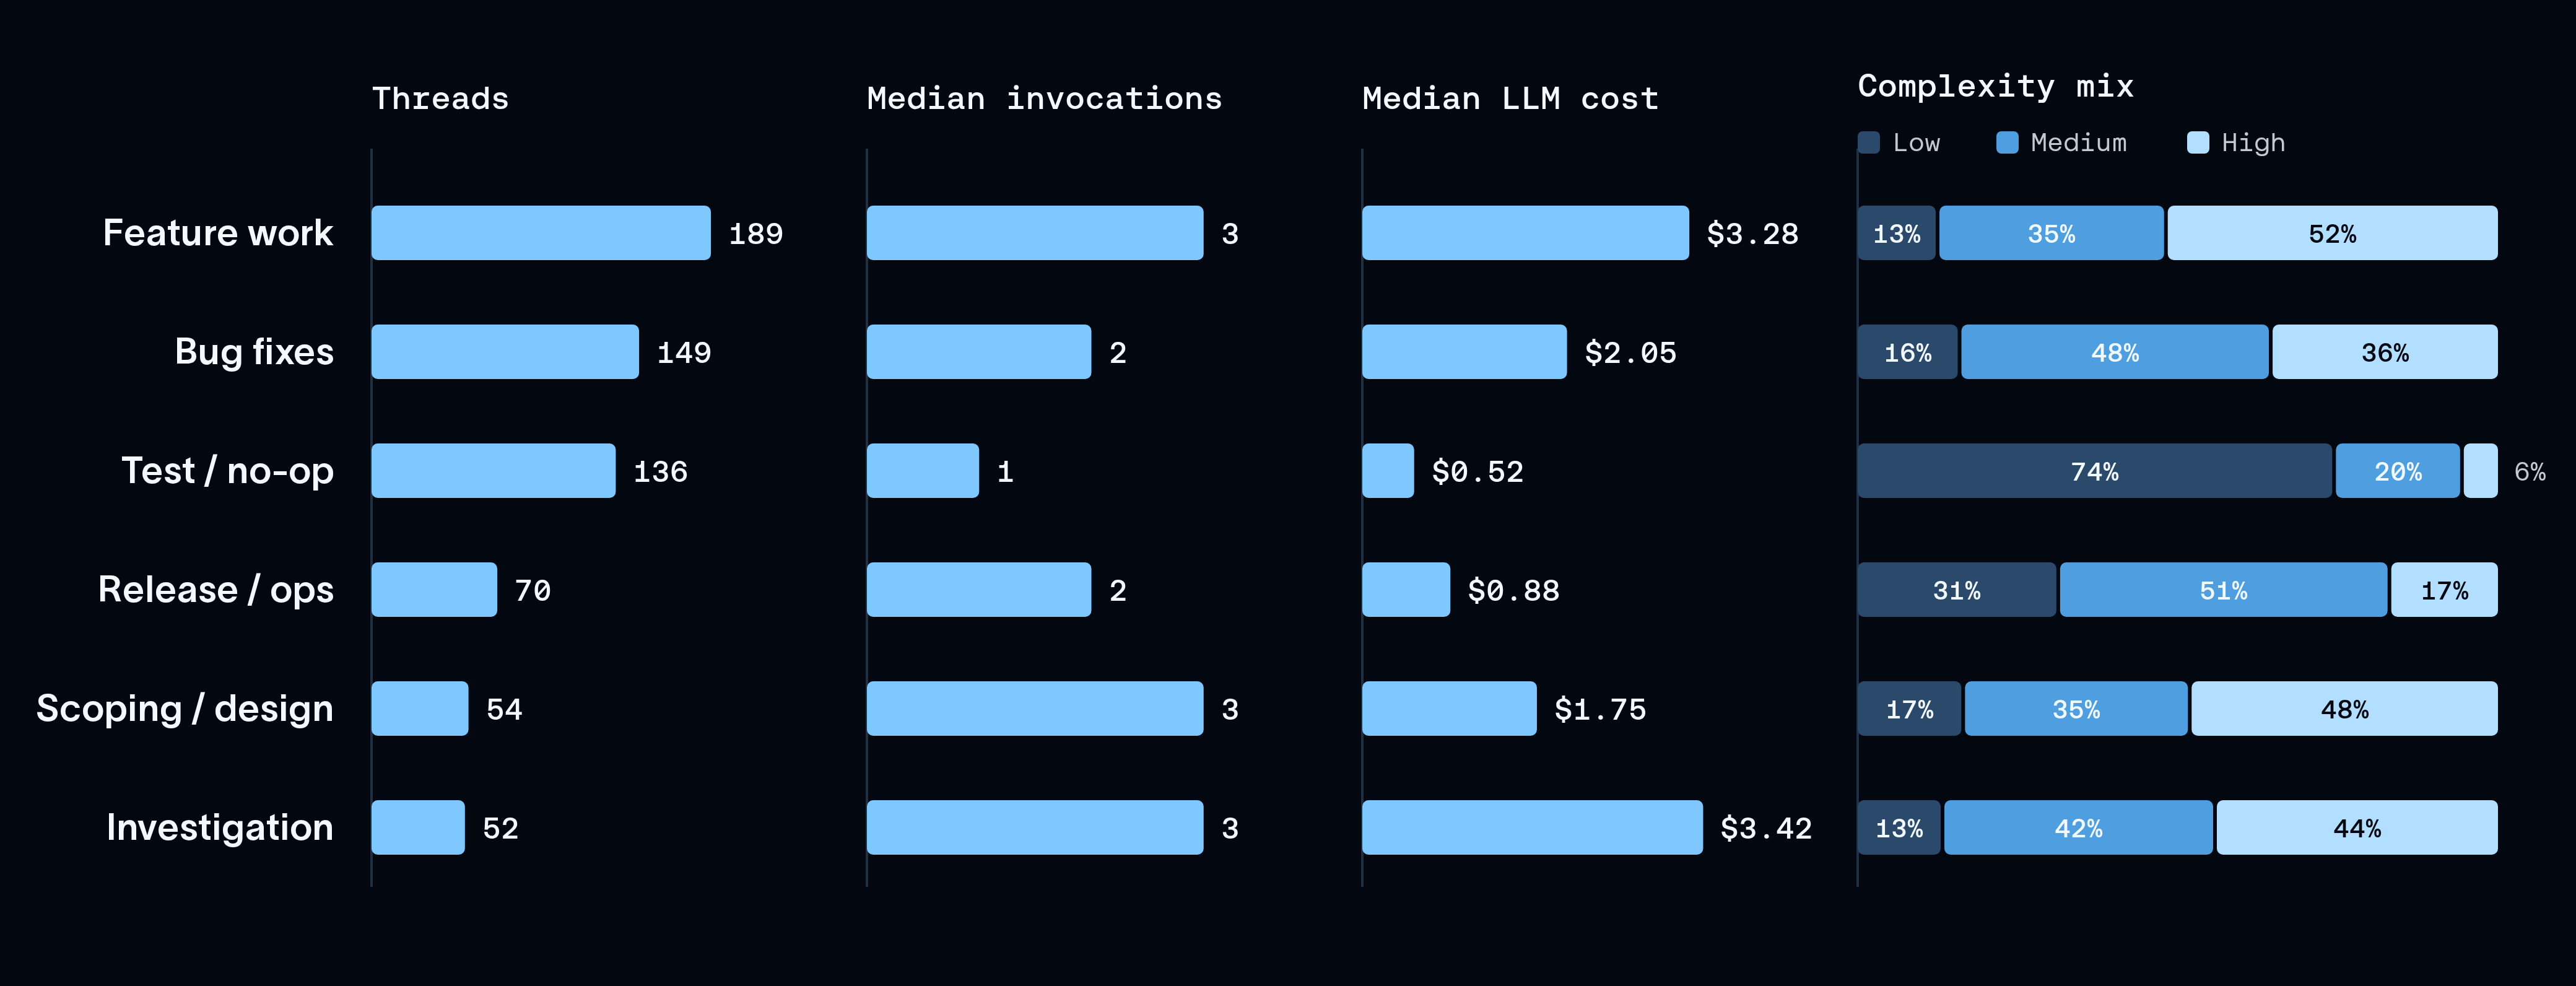
收集数据时,Open SWE 的所有会话都交给一个顶级前沿模型处理。上述数据表明,考虑到任务复杂度的差异,Open SWE 处理的许多任务可能并不需要前沿级别的智能。
At the time of data collection, all of the Open SWE threads were being routed through a top-tier frontier model. The above data suggested that many of the tasks Open SWE handled might not require frontier intelligence, given the range of complexities.
这种任务复杂度上的差异,让我们提出了一个值得检验的假设:路由器可以从初始请求中推断任务类型和难度,将任务发送给更便宜或更快的模型,同时不降低最终结果的质量。
This variation in task complexity gave us a hypothesis worth testing: a router could infer a task’s type and difficulty from the initial request and send it to a cheaper or faster model without degrading outcomes.
第 2 步:理解模型
Step 2: understand the models
Artificial Analysis 智能指数使用同一组任务对模型打分,并报告每项任务的成本,因此你可以把它们放到同一张智能水平与成本关系图上。帕累托前沿由那些在低成本与高智能之间处于最优权衡位置的模型构成。
The Artificial Analysis Intelligence Index scores models on a common set of tasks and reports the cost per task, so you can plot them all on one curve of intelligence against cost. The Pareto frontier is the set of models that are the cheapest and smartest.
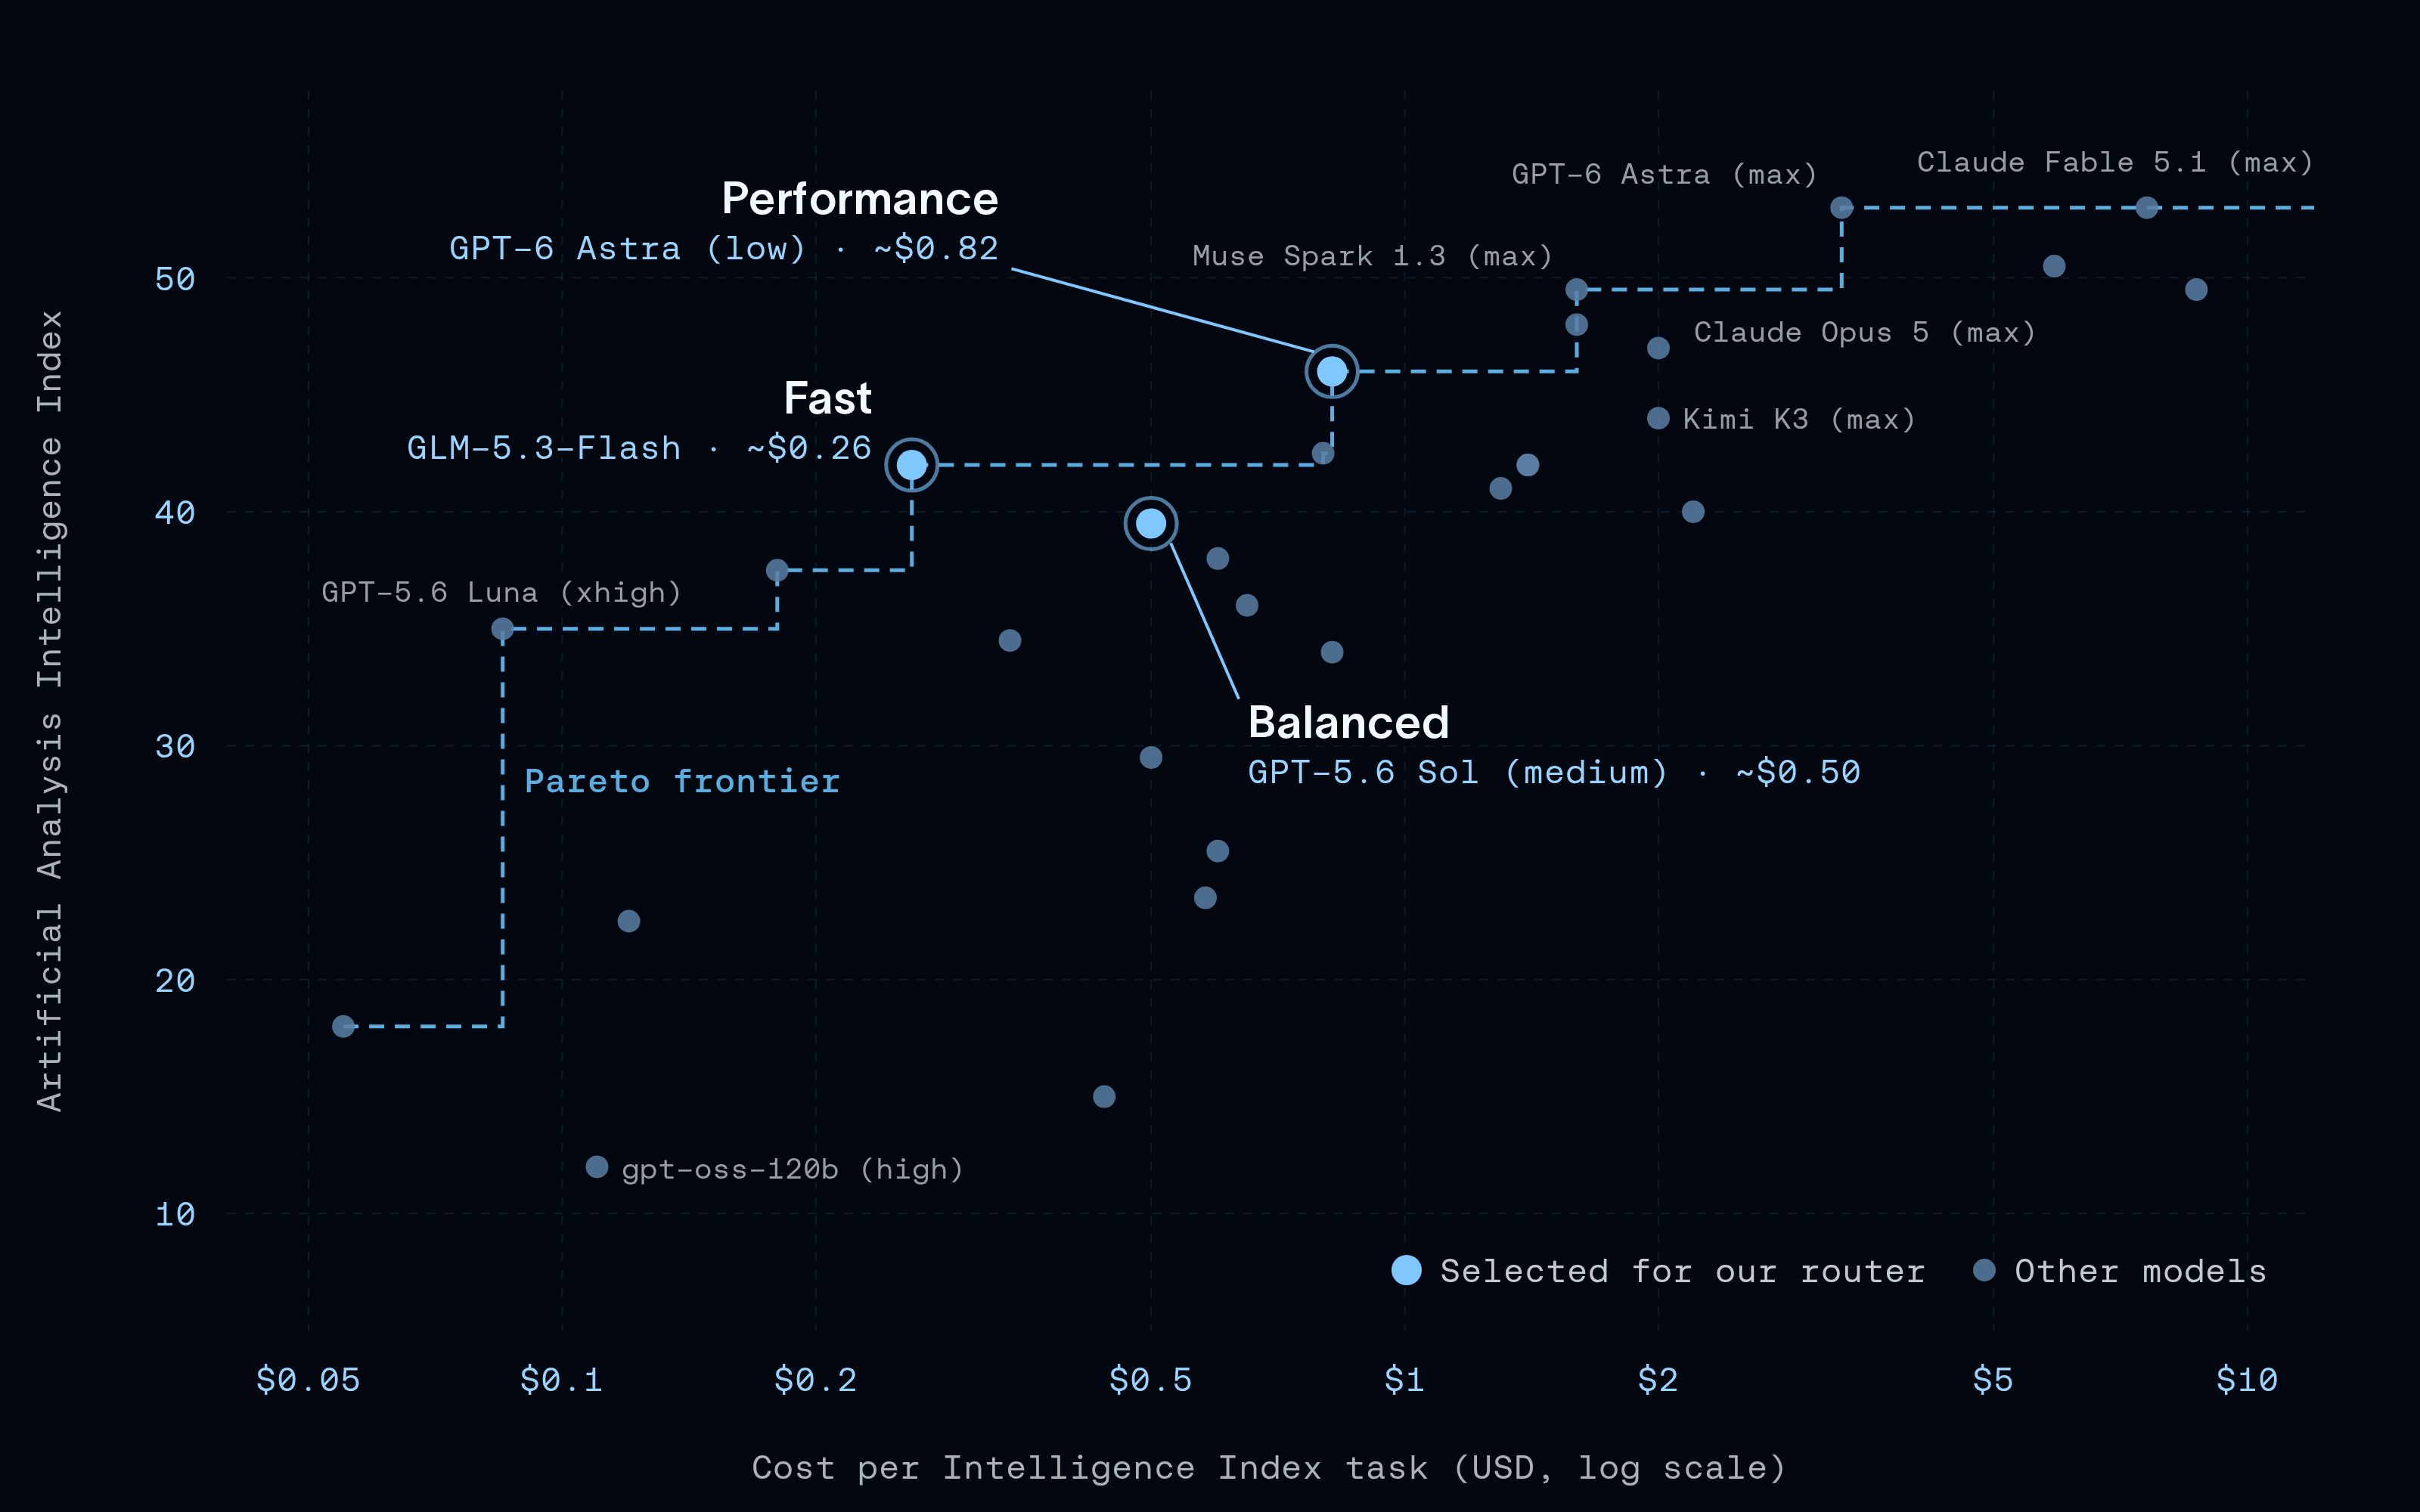
我们沿着这条曲线选定了三个模型,它们分别在成本、速度与智能之间取得不同的平衡:
We decided on three models along the curve, each with a different balance of cost, speed, and intelligence:
- 快速档:GLM-5.3-Flash(xhigh)
- 均衡档:GPT-5.6 Sol(medium)
- 高性能档:GPT-6 Astra(low)
- Fast: GLM-5.3-Flash (xhigh)
- Balanced: GPT-5.6 Sol (medium)
- Performance: GPT-6 Astra (low)
我们选择了不同供应商的模型,其中快速档采用开放模型。GLM-5.3-Flash 与闭源模型一起位于帕累托前沿,这又一次表明,开放模型已经跨越了一个门槛。LangChain 不绑定特定模型,它提供通用的模型接口,在不同供应商之间都以相同方式工作。因此,当更好的模型出现时,只需修改路由器中的一行代码,就能将其替换进来。
We selected models from different providers, and the fast tier is an open model. GLM-5.3-Flash sits on the Pareto frontier next to closed models, one more sign that open models have crossed a threshold. LangChain is model agnostic, with a generic model interface that works the same across providers, so when a better model lands, swapping it in is a one-line change to the router.
第 3 步:在运行框架中构建路由器
Step 3: build the router in the harness
在了解任务构成并选定三个档位之后,我们需要将任务与模型匹配:读取每个新请求,把它交给能够成功完成任务的最低成本档位。在 LangChain 中,这个决策天然适合放在中间件中。中间件可以替换 Agent 调用的模型,而无须改变 Agent 的其他任何部分,参见动态模型选择。
With the task mix mapped and three tiers picked, we then need to match the tasks to models by reading each incoming request and sending it to the cheapest tier that's able to address it successfully. In LangChain, that decision fits naturally in middleware, which can swap the model an agent calls without changing anything else about the agent (see dynamic model selection).
Open SWE 的路由器在收到会话中的第一条用户消息时运行。它有三个组成部分:
The router in Open SWE runs on the thread’s first human message. It has three parts:
- 基础提示词:告诉分类器它的工作是什么:选择可能完成任务的最低成本模型。
- 各档位的标准:用简短、通俗的语言,描述每个档位应当承担什么工作。
- 分类模型:读取请求,根据标准和提示词选择档位。
- A base prompt: tells the classifier its job: pick the least expensive model likely to complete the task.
- Criteria per tier: a short, plain-language description of the work each tier should take.
- A classifier model: reads the request and picks a tier according to the criteria and prompt.
通用基准只是一个起点。各档位的标准应根据两类信息编写:你自己的任务分析,以及各供应商对其模型最擅长工作的介绍。我们结合了第 1 步的任务分类,以及 GPT-5.6 Sol、GPT-6 Astra 和 GLM-5.3-Flash 的供应商指南,编写基础提示词与各档位标准。
A general benchmark is only a starting point. Write each tier's criteria from two sources: your own task analysis, and what each provider says its models are best at. We combined the task breakdown from step 1 with the provider guides for GPT-5.6 Sol, GPT-6 Astra, and GLM-5.3-Flash to write the base prompt and the criteria for each tier.
这些标准是针对 Open SWE 的任务集合编写的,因此路由器与 Open SWE 处理的任务深度耦合。这正是它应当放在运行框架中的原因:运行框架已经具备 Agent 特定任务所需的上下文,包括提示词、工具与领域知识,而通用网关并不具备。
Those criteria are written for Open SWE's task set, so the router is deeply coupled to the tasks Open SWE handles. That’s why it belongs in the harness, which already has the agent’s task-specific context (its prompt, tools, and domain knowledge) that a generic gateway lacks.
第一版使用支持结构化输出的 LLM,并以用户请求作为提示。如今,分类器运行在新发布的决策模型 Jev 上,使分类速度提高了近 50 倍。具体做法请参阅《借助 Jev 构建运行框架》。
Our first version used an LLM with structured output, prompted with the user's request. The classifier now runs on Jev, a newly released decision model, which made classification almost 50× faster. See how we did this in Building a Harness with Jev.
路由器在每个会话开始时只选择一次模型,整个会话都会使用该模型。一个自然的疑问是:如果会话中途改变了主题或复杂度,怎么办?这个简化版路由器尚未处理这一问题,但我们会在下方“下一步”一节讨论会话中途的路由。
The router picks a model once, at the start of each thread, and that model is used for the whole thread. The natural objection is: what if a thread changes topic or complexity mid-flight? Though not addressed in this naive router design, we cover mid-flight routing in the “what’s next” section below.
第 4 步:跟踪任务结果
Step 4: track task outcomes
路由器的价值在于降低成本,但前提是质量不能退步。路由器必须做好两件事:所选模型能够完成任务,而且应当是能完成任务的模型中最便宜、最快的那一个。这意味着你需要一种跟踪任务结果的方法。有两种做法:
The value in a router is lower cost, but only if quality doesn't regress. A router has to get two things right: the chosen model needs to be able to complete the task, and it should be the cheapest, fastest model that can. That means you need a way to track task outcomes. There are two ways to do this:
- 离线评测让路由器在固定数据集上运行,以便安全、可重复地比较不同版本。难点在于数据集:它必须贴近真实流量,并按照用户关心的标准评分。对于编程 Agent,这意味着 PR 的质量与可评审性,而这些很难离线评分。
- A/B 测试将实时会话分给路由器与单模型基线,并使用每个会话都能测量的成功指标进行比较。实时流量天然构成具有代表性的数据集,但缺点是用户可能会受到尚非最优的路由器影响。
- Offline evals run the router against a fixed dataset, so you can compare versions safely and repeatably. The catch is the dataset: it has to look like your real traffic and be graded on what your users care about. For a coding agent, that means PR quality and reviewability, which are hard to grade offline.
- An A/B test splits live threads between the router and a single-model baseline and compares them on a success metric you can measure for every thread. The live traffic is naturally a representative dataset, but the downside here is that users are subjected to a potentially non-optimal router.
我们运行了 A/B 测试,并使用两种结果信号:
We ran A/B tests with two outcome signals:
- 合并的 PR:Open SWE 现在会记录它创建的每个 PR,以及该 PR 最终被合并还是关闭。每个会话合并的 PR 数,成为我们的主要成功指标。
- 用户反馈:我们给 Open SWE 加入了点赞和点踩功能,让用户可以评价任何会话,包括那些不会产生 PR 的问答会话。每条评价都会作为反馈记录到该会话的 LangSmith 执行轨迹上。
- Merged PRs: Open SWE now records every PR it opens and whether it's merged or closed. Merged PRs per thread became our main success metric.
- User feedback: we added thumbs up and down to Open SWE, so users could rate any thread, including questions that never produce a PR. Each rating is logged as feedback on the thread's LangSmith trace.
我们在一个 LangSmith Custom App 中跟踪这两类信号。合并的 PR 是更有力的信号。用户反馈比较稀疏,因为只有少部分会话会得到评价;不过,我们正是通过这些反馈了解到路由错误,例如下面第一次测试中引用的那些评论。
We tracked both in a LangSmith Custom App. Merged PRs were the stronger signal. Feedback was sparse, since only a small share of threads get rated, but it's where we heard about routing mistakes, like the ones quoted in the first test below.
实验
The experiment
第一次 A/B 测试,将路由器与始终使用最强模型的策略进行比较:一半会话经过路由器,另一半始终使用 GPT-6 Astra,总计 973 个会话。
Our first A/B test compared the router against always using our strongest model: half of threads went through the router, and half always used GPT-6 Astra, across 973 threads in total.
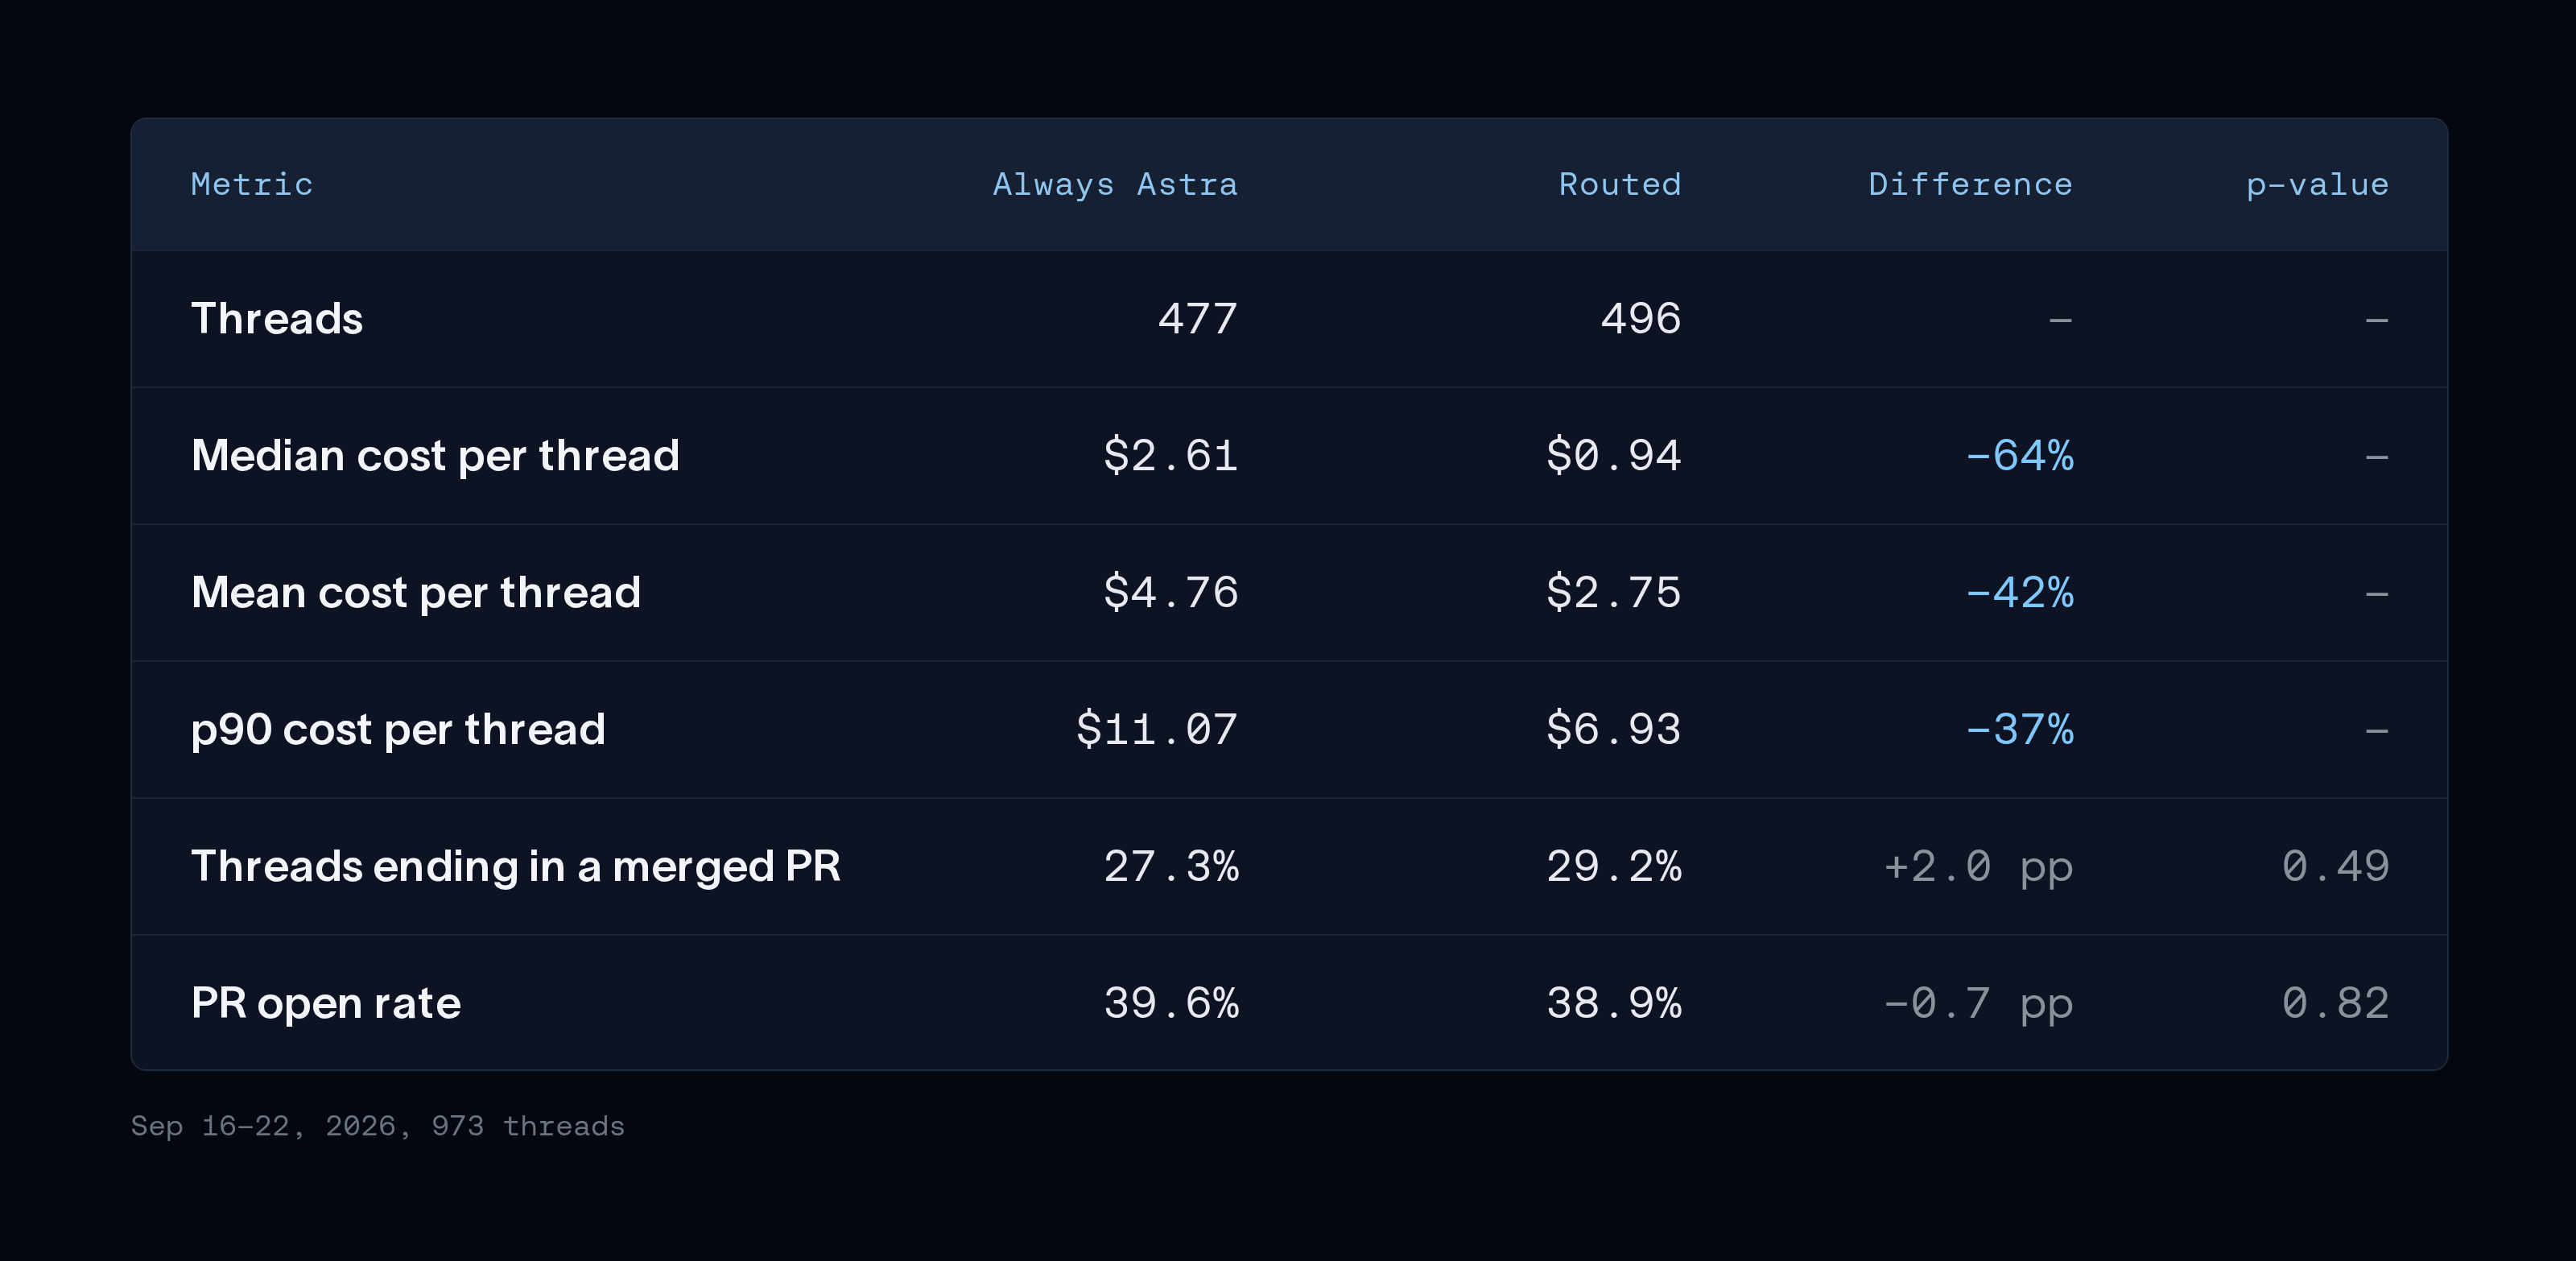
没有测得质量上的变化。经过路由的会话中,29.2% 最终产生了被合并的 PR,对照组为 27.3%(p = 0.49)。PR 创建率也基本持平:38.9% 对 39.6%,p = 0.82。
Quality didn't measurably change. 29.2% of routed threads ended in a merged PR vs. 27.3% of control (p = 0.49). PR open rates were also flat (38.9% vs. 39.6%, p = 0.82).
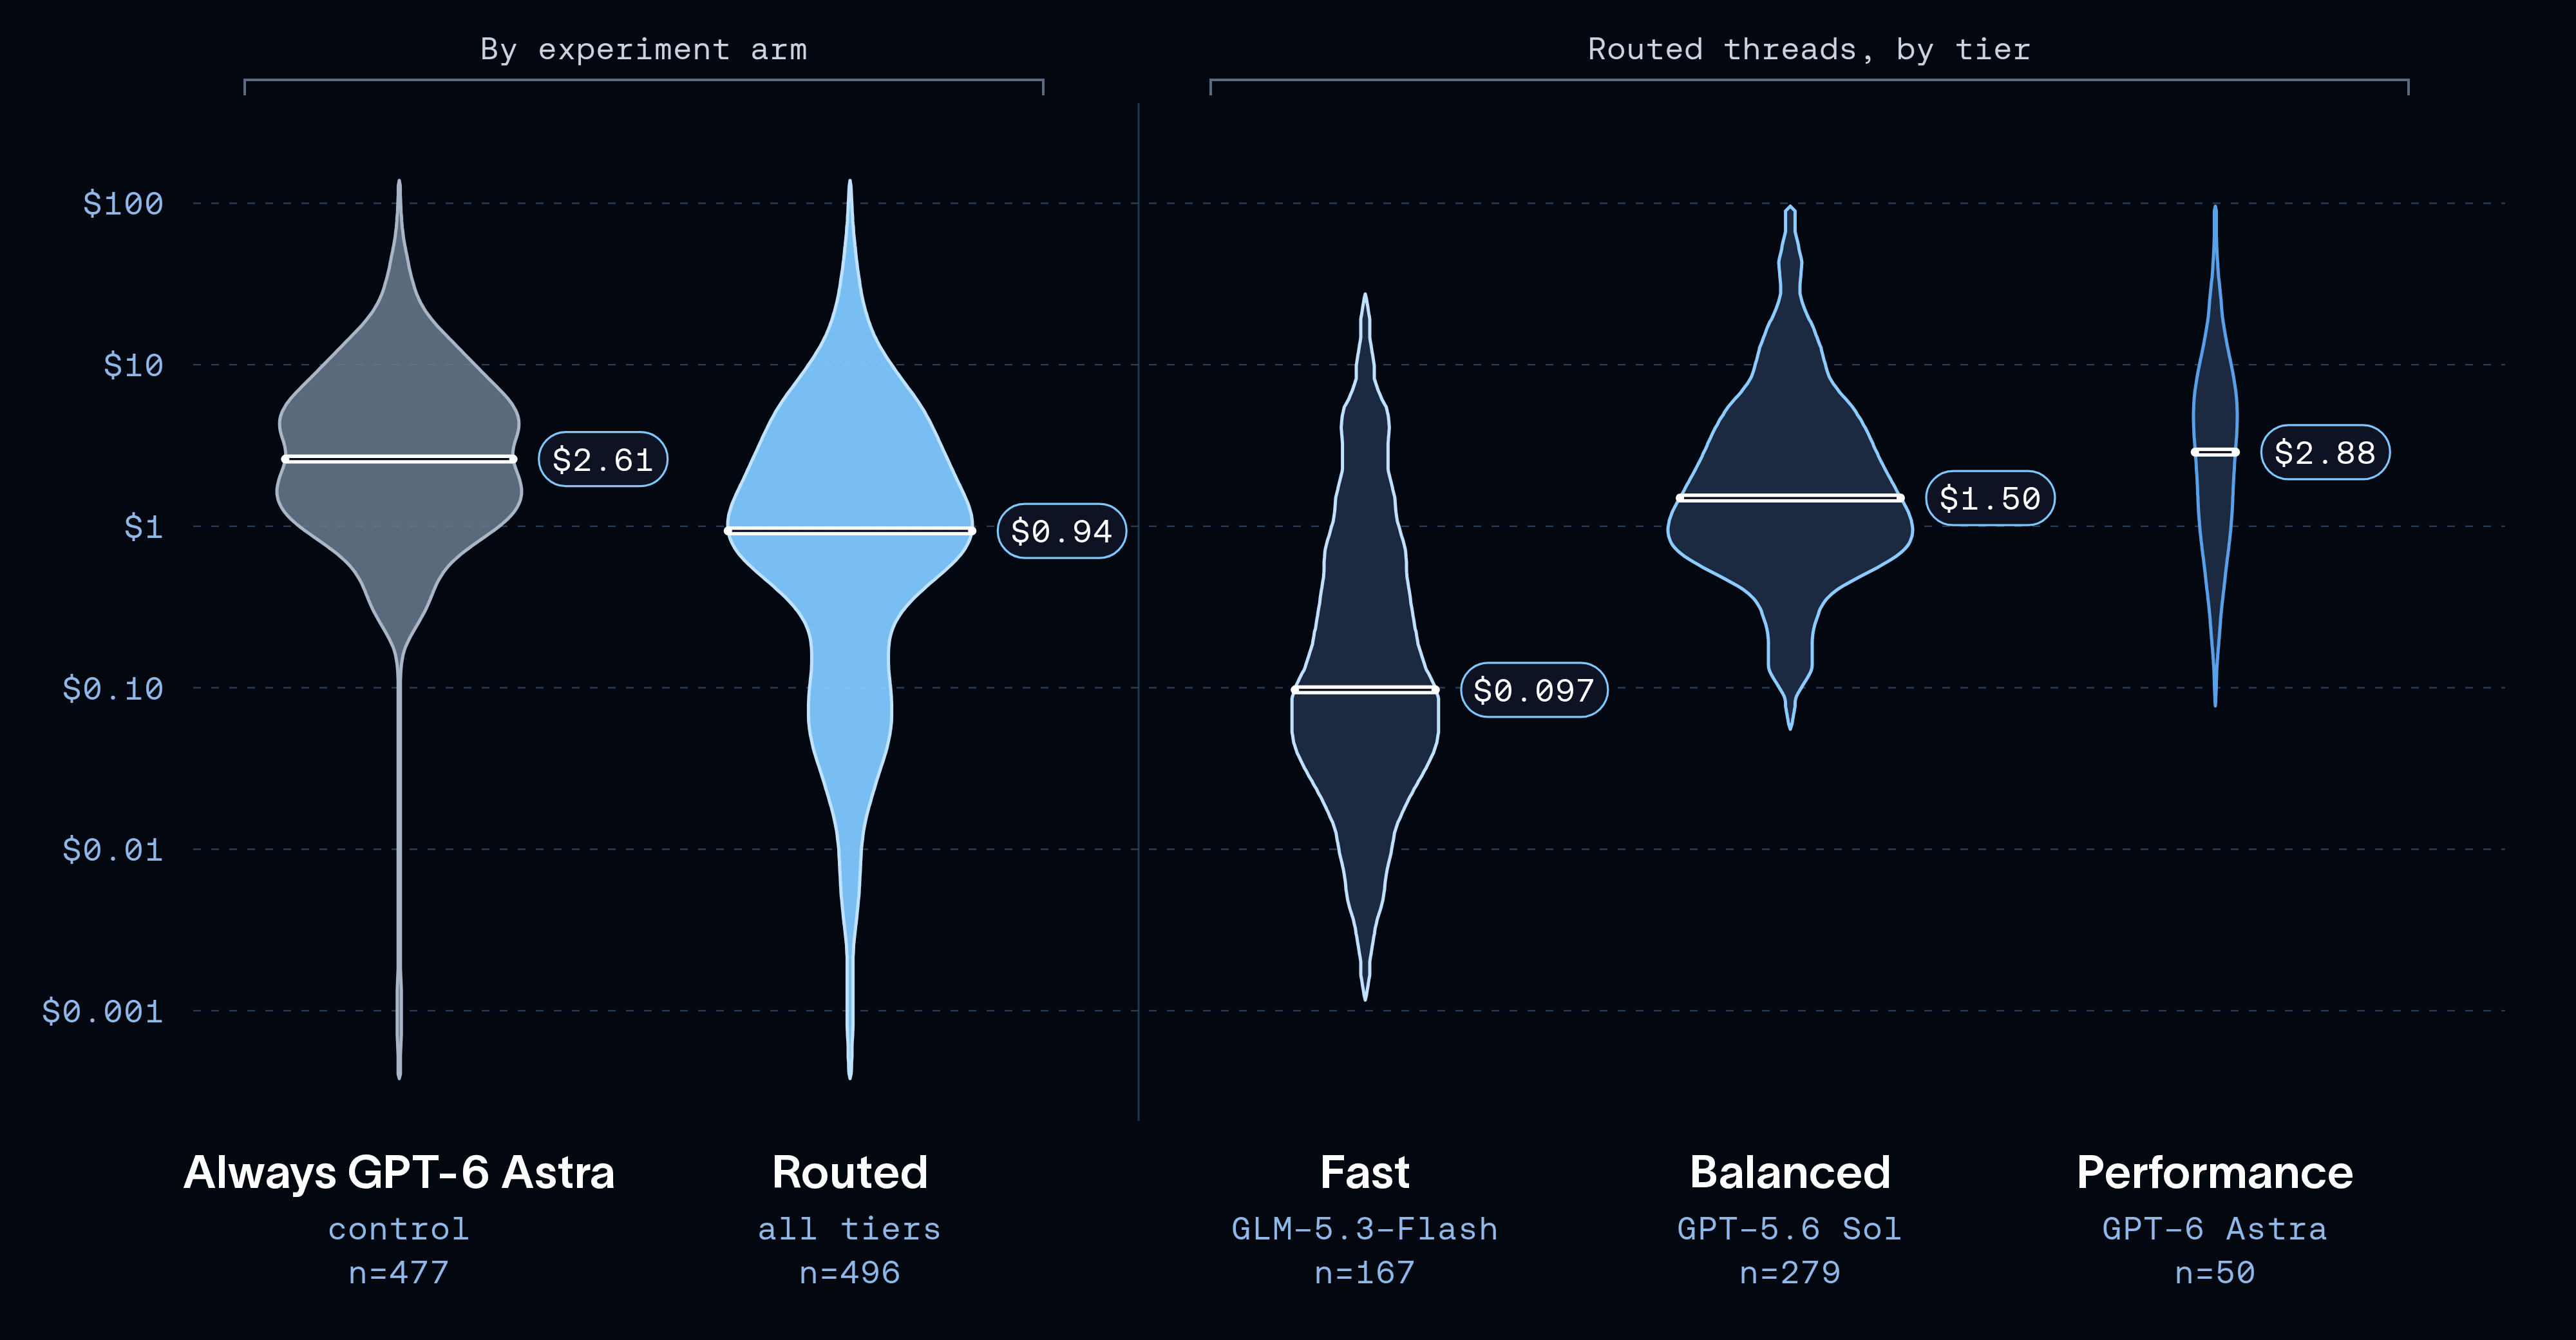
成本大幅下降。路由组的会话成本中位数为 0.94 美元,对照组为 2.61 美元,下降了 64%。平均成本下降 42%,第 90 百分位成本下降 37%,说明节省并不只是由少数极低成本的异常值带来的。
Cost dropped a lot. The median routed thread cost $0.94 vs. $2.61 on control, 64% less. The mean dropped 42% and the p90 dropped 37%, so the savings weren't just a few cheap outliers.
多数请求并不需要最强模型。在经过路由的会话中,56% 进入均衡档,34% 进入快速档,只有 10% 进入高性能档。各档位之间的成本差距很大:会话成本中位数分别为快速档 0.097 美元、均衡档 1.50 美元、高性能档 2.88 美元,相差约 30 倍。
Most requests didn't need the strongest model. Of routed threads, 56% went to balanced, 34% to fast, and only 10% to performance. The cost ladder between tiers is steep: the median thread cost $0.097 on fast, $1.50 on balanced, and $2.88 on performance, a 30× spread.
用户反馈也指向同样的结论。当一个简单请求由 GPT-6 Astra 处理时,工程师会直接指出成本过高,例如评论:“对这个查询来说太贵了”,以及“这个请求不该被路由到高性能模型”。
User feedback pointed the same way. When a simple request ran on GPT-6 Astra, engineers flagged the overspend directly with comments like: "pretty expensive for this query" and "this request should not have been routed to the performance model."
💡 考虑到对照组使用的是我们最昂贵的模型,这个结果并不令人意外。但许多 Agent 都会受益于这种改变:不少 Agent 过于偏重质量,最终花了过多的钱。对于任务类型多样的 Agent,路由尤其能够降低成本。
💡 This result isn't surprising, given the control was our most expensive model. But it's a change a lot of agents would benefit from: many over-rotate on quality and end up overspending. Especially for agents with a diverse set of tasks, routing can drive cost down.
我们还做了一个相反的对照实验:一半会话经过路由器,另一半始终使用快速模型。这个测试在一天之内就被终止了,尚未产生具有统计意义的结果。工程师几乎立刻就指出了只用快速模型的实验组存在问题;较低的输出质量正在干扰他们的工作效率。
We also tested the router against the opposite control: half of threads went through the router, and half always used the fast model. We ended this test within a day, before it could produce statistically meaningful results. Engineers flagged problems with the fast-only arm almost immediately, and it was disrupting their productivity due to low output quality.
下一步
What's next
这个模型路由器实现是一项概念验证,为构建最优路由器提供了基础。以下是可以进一步探索的改进方向:
This implementation of a model router is a proof of concept that serves as a foundation for building an optimal router. Here are a few areas we could explore to improve:
- 在 DeepSWE 或其他编程基准上测试路由器,这样我们就可以针对受控基线评测路由决策,而不必只依赖生产流量上的 A/B 测试。
- 为子 Agent选择模型。目前,子 Agent 的模型选择独立于路由器。如果也对子 Agent 进行路由,尤其是在长时间任务中,可能进一步降低成本。
- 在会话中途重新路由。当新消息与之前的内容差异足够大时,例如问答变成了缺陷修复,更换模型可能值得。代价在于提示词缓存:切换模型会丢弃缓存,因此新模型需要按完整价格重新读取会话。对于异步 Agent,这个成本往往可以忽略,因为当缓存有效期较短(例如 5 分钟)时,它通常本来就会在两轮用户交互之间过期。
- 利用更多信号优化路由标准,例如从执行轨迹中挖掘用户情绪:找出用户感到不满的会话,这可能意味着任务需要更强的模型。
- Benchmarking the router on DeepSWE or other coding benchmarks, so we can evaluate routing decisions against a controlled baseline instead of relying on A/B testing on production traffic alone.
- Model selection for subagents. Right now subagents pick their model independently of the router. Routing subagents too, especially on longer-running tasks, could cut costs further.
- Re-routing mid-thread. When a new message differs enough from earlier ones, like a question that turns into a bug fix, a model change might pay off. The cost is the prompt cache: switching models throws it away, so the new model re-reads the thread at full price. For async agents that cost is often negligible, since the cache often expires anyways between human turns when the TTL is short (like 5 minutes).
- Refining the routing criteria with more signals, such as mining for user sentiment in traces: finding threads where users are frustrated, which can mean the task needed a stronger model.
如何开始
Getting started
如果你要为自己的 Agent 增加路由,我们建议从以下几步开始:
If you're adding routing to your own agent, here's where we'd start:
- 理解任务。执行轨迹真实记录了用户要求 Agent 做什么,LangSmith Insights 则帮助你发现其中的模式,让你在选择档位之前先了解任务构成。
- 理解模型。参考当前的基准评测,沿着成本与智能水平曲线选取几个模型。LangChain 的模型接口适用于不同供应商,因此你可以随时更换模型,无须重新设计应用。
- 在运行框架中构建路由器。把路由视为上下文工程,它类似于经典的特征工程:根据 Agent 所处的领域,决定路由器需要看到哪些信息,才能对模型适配性做出最佳判断。
- 跟踪任务结果。在启用路由前,先建立衡量成功的方法:评测、在线评估器,或执行轨迹上的用户反馈。如果构建评测数据集的成本太高或难度太大,在实时流量上进行 A/B 测试也很有效。
- Understand the tasks. Your traces hold the real record of what your agent is asked to do, and LangSmith Insights helps you find the patterns in them, so you can see the task mix before you pick tiers.
- Understand the models. Pick a few models along the cost-intelligence curve, informed by modern benchmarks. LangChain's model interface works across providers, so you can swap models at any time without having to re-engineer your application.
- Build the router in the harness. Treat routing as context engineering, analogous to classical feature engineering: decide what information the router should see in order to make the best decision about model fit given your agent's domain.
- Track task outcomes. Put measures of success in place before you route: evals, online evaluators, or user feedback on traces. If building an eval dataset is too costly or difficult, an A/B test on live traffic works well.
随着新模型,包括开放权重模型,不断进入能力前沿,最适合某项任务的模型也在持续变化。由于 LangChain 不绑定特定模型,要获得这些进步带来的收益,只需替换一个档位的模型,无须重建 Agent。
The right model for a task keeps changing as new models, open-weight ones included, keep landing on the frontier. Because LangChain is model agnostic, picking up those gains means swapping a tier, not rebuilding your agent.
要为自己的 Agent 增加路由,你可以使用我们新发布的模型路由中间件。向它提供基础提示词、模型档位,以及各档位的标准,它就会在每个会话开始时选择模型。欢迎通过 X 或 LangChain 的 GitHub issues 向我们反馈。
To add routing to your own agent, you can add our newly released model routing middleware. Give it your base prompt, model tiers, and the criteria for each, and it picks a model at the start of every thread. We’d love your feedback on X or LangChain GitHub issues.
延伸阅读
Further reading
致谢
Acknowledgements
感谢 Mason Daugherty、Kevin Frank 和 Harrison Chase 为本文提供的细致反馈。也感谢支持本次实验的 OpenSWE 团队!
Thanks to Mason Daugherty, Kevin Frank, and Harrison Chase for their thoughtful feedback on this post. Also thanks to the OpenSWE team who supported this experiment!
— 全文完 —
原文来自 LangChain,中文为非官方学习译文。
查看原始出处 ↗