一种提升 Claude 复杂问题解决能力的新工具
A new tool that improves Claude's complex problem-solving performance
扩展思考功能更新
扩展思考能力自首次发布以来已有提升,因此,在大多数情况下,我们建议使用该功能,而非专门的 think 工具。扩展思考同样能为 Claude 提供推理复杂问题的空间,同时具备更好的集成方式和性能。实现细节请参阅扩展思考文档。
Extended thinking update
Extended thinking capabilities have improved since its initial release, such that we recommend using that feature instead of a dedicated think tool in most cases. Extended thinking provides similar benefits—giving Claude space to reason through complex problems—with better integration and performance. See our extended thinking documentation for implementation details.
在持续增强 Claude 解决复杂问题的能力时,我们发现了一种特别有效的方法:“think”工具。它为复杂任务中的结构化思考提供了专门的空间。
As we continue to enhance Claude's complex problem-solving abilities, we've discovered a particularly effective approach: a "think" tool that creates dedicated space for structured thinking during complex tasks.
这个简单而强大的技巧,与 Claude 新推出的“扩展思考”能力并不相同,后文会解释两者的区别(扩展思考的实现细节见此处)。它显著改善了 Claude 在 Agent 工作中的工具使用能力,包括遵循规则、作出一致的决策和处理多步骤问题,而实现开销很小。
This simple yet powerful technique—which, as we’ll explain below, is different from Claude’s new “extended thinking” capability (see here for extended thinking implementation details)—has resulted in remarkable improvements in Claude's agentic tool use ability. This includes following policies, making consistent decisions, and handling multi-step problems, all with minimal implementation overhead.
本文将探讨如何在不同应用中实现“think”工具,并根据经过验证的基准测试结果,为开发者提供实用指导。
In this post, we'll explore how to implement the “think” tool on different applications, sharing practical guidance for developers based on verified benchmark results.
什么是“think”工具?
What is the "think" tool?
通过“think”工具,我们让 Claude 能够在得出最终答案的过程中,加入一个额外的思考步骤,并为其配备专用空间。
With the "think" tool, we're giving Claude the ability to include an additional thinking step—complete with its own designated space—as part of getting to its final answer.
虽然听起来与扩展思考类似,但这是不同的概念。扩展思考关注的是 Claude 开始生成回答之前所做的事情。在扩展思考中,Claude 会在采取行动前深入考虑并迭代自己的计划。“think”工具则让 Claude 在已经开始生成回答之后,增加一个停下来思考的步骤,判断自己是否已经掌握了继续推进所需的全部信息。当执行很长的工具调用链,或与用户进行漫长的多步骤对话时,这尤其有帮助。
While it sounds similar to extended thinking, it's a different concept. Extended thinking is all about what Claude does before it starts generating a response. With extended thinking, Claude deeply considers and iterates on its plan before taking action. The "think" tool is for Claude, once it starts generating a response, to add a step to stop and think about whether it has all the information it needs to move forward. This is particularly helpful when performing long chains of tool calls or in long multi-step conversations with the user.
因此,“think”工具更适合这样的场景:Claude 仅凭用户查询还无法获得形成回答所需的全部信息,并且需要处理外部信息,例如工具调用结果中的信息。Claude 使用“think”工具时进行的推理,不像扩展思考所能提供的那样全面,而是更聚焦于模型发现的新信息。
This makes the “think” tool more suitable for cases where Claude does not have all the information needed to formulate its response from the user query alone, and where it needs to process external information (e.g. information in tool call results). The reasoning Claude performs with the “think” tool is less comprehensive than what can be obtained with extended thinking, and is more focused on new information that the model discovers.
对于不依赖先后顺序的工具调用、直接的指令遵循等较简单的工具使用场景,我们建议使用扩展思考。在编程、数学、物理等不需要 Claude 调用工具的用例中,扩展思考也很有用。“think”工具则更适合以下情况:Claude 需要调用复杂工具,在长工具调用链中仔细分析工具输出,处理有详细指导规则的复杂制度环境,或连续作出每一步都依赖此前步骤、而且出错代价很高的决策。
We recommend using extended thinking for simpler tool use scenarios like non-sequential tool calls or straightforward instruction following. Extended thinking is also useful for use cases, like coding, math, and physics, when you don’t need Claude to call tools. The “think” tool is better suited for when Claude needs to call complex tools, analyze tool outputs carefully in long chains of tool calls, navigate policy-heavy environments with detailed guidelines, or make sequential decisions where each step builds on previous ones and mistakes are costly.
下面是一个使用标准工具规格格式的实现示例,来自 τ-Bench:
Here's a sample implementation using the standard tool specification format that comes from τ-Bench:
在 τ-Bench 上的表现
Performance on τ-Bench
我们使用 τ-bench(tau-bench)评估了“think”工具。这是一项综合性基准测试,旨在测试模型在真实客服场景中的工具使用能力;“think”工具是该评测标准环境的一部分。
We evaluated the "think" tool using τ-bench (tau-bench), a comprehensive benchmark designed to test a model’s ability to use tools in realistic customer service scenarios, where the "think" tool is part of the evaluation’s standard environment.
τ-bench 评估 Claude 的以下能力:
τ-bench evaluates Claude's ability to:
- 与模拟用户开展贴近真实情况的对话
- 始终如一地遵循复杂的客服 Agent 规则与指导要求
- 使用多种工具访问和操作环境中的数据库
- Navigate realistic conversations with simulated users
- Follow complex customer service agent policy guidelines consistently
- Use a variety of tools to access and manipulate the environment database
τ-bench 使用的主要评测指标是 pass^k,它衡量的是:对于给定任务,k 次独立尝试全部成功的概率,再对所有任务取平均。其他大语言模型评测中常见的 pass@k 指标,衡量的是 k 次尝试中是否至少有一次成功;与之不同,pass^k 评估的是一致性与可靠性。这些品质对客服应用至关重要,因为这类应用必须始终遵守规则。
The primary evaluation metric used in τ-bench is pass^k, which measures the probability that all k independent task trials are successful for a given task, averaged across all tasks. Unlike the pass@k metric that is common for other LLM evaluations (which measures if at least one of k trials succeeds), pass^k evaluates consistency and reliability—critical qualities for customer service applications where consistent adherence to policies is essential.
性能分析
Performance Analysis
我们的评测比较了几种不同配置:
Our evaluation compared several different configurations:
- 基线配置(不使用“think”工具,也不开启扩展思考模式)
- 仅使用扩展思考模式
- 仅使用“think”工具
- “think”工具搭配优化后的提示词(针对航空业务场景)
- Baseline (no "think" tool, no extended thinking mode)
- Extended thinking mode alone
- "Think" tool alone
- "Think" tool with optimized prompt (for airline domain)
结果表明,当 Claude 3.7 有效使用“think”工具时,在该基准测试的“航空”和“零售”客服场景中都取得了显著提升:
The results showed dramatic improvements when Claude 3.7 effectively used the "think" tool in both the “airline” and “retail” customer service domains of the benchmark:
- 航空业务场景:“think”工具搭配优化后的提示词,在 pass^1 指标上取得了 0.570 的成绩,而基线只有 0.370,相对提升了 54%;
- 零售业务场景:仅使用“think”工具就达到了 0.812,基线则为 0.783。
- Airline domain: The "think" tool with an optimized prompt achieved 0.570 on the pass^1 metric, compared to just 0.370 for the baseline—a 54% relative improvement;
- Retail domain: The "think" tool alone achieves 0.812, compared to 0.783 for the baseline.
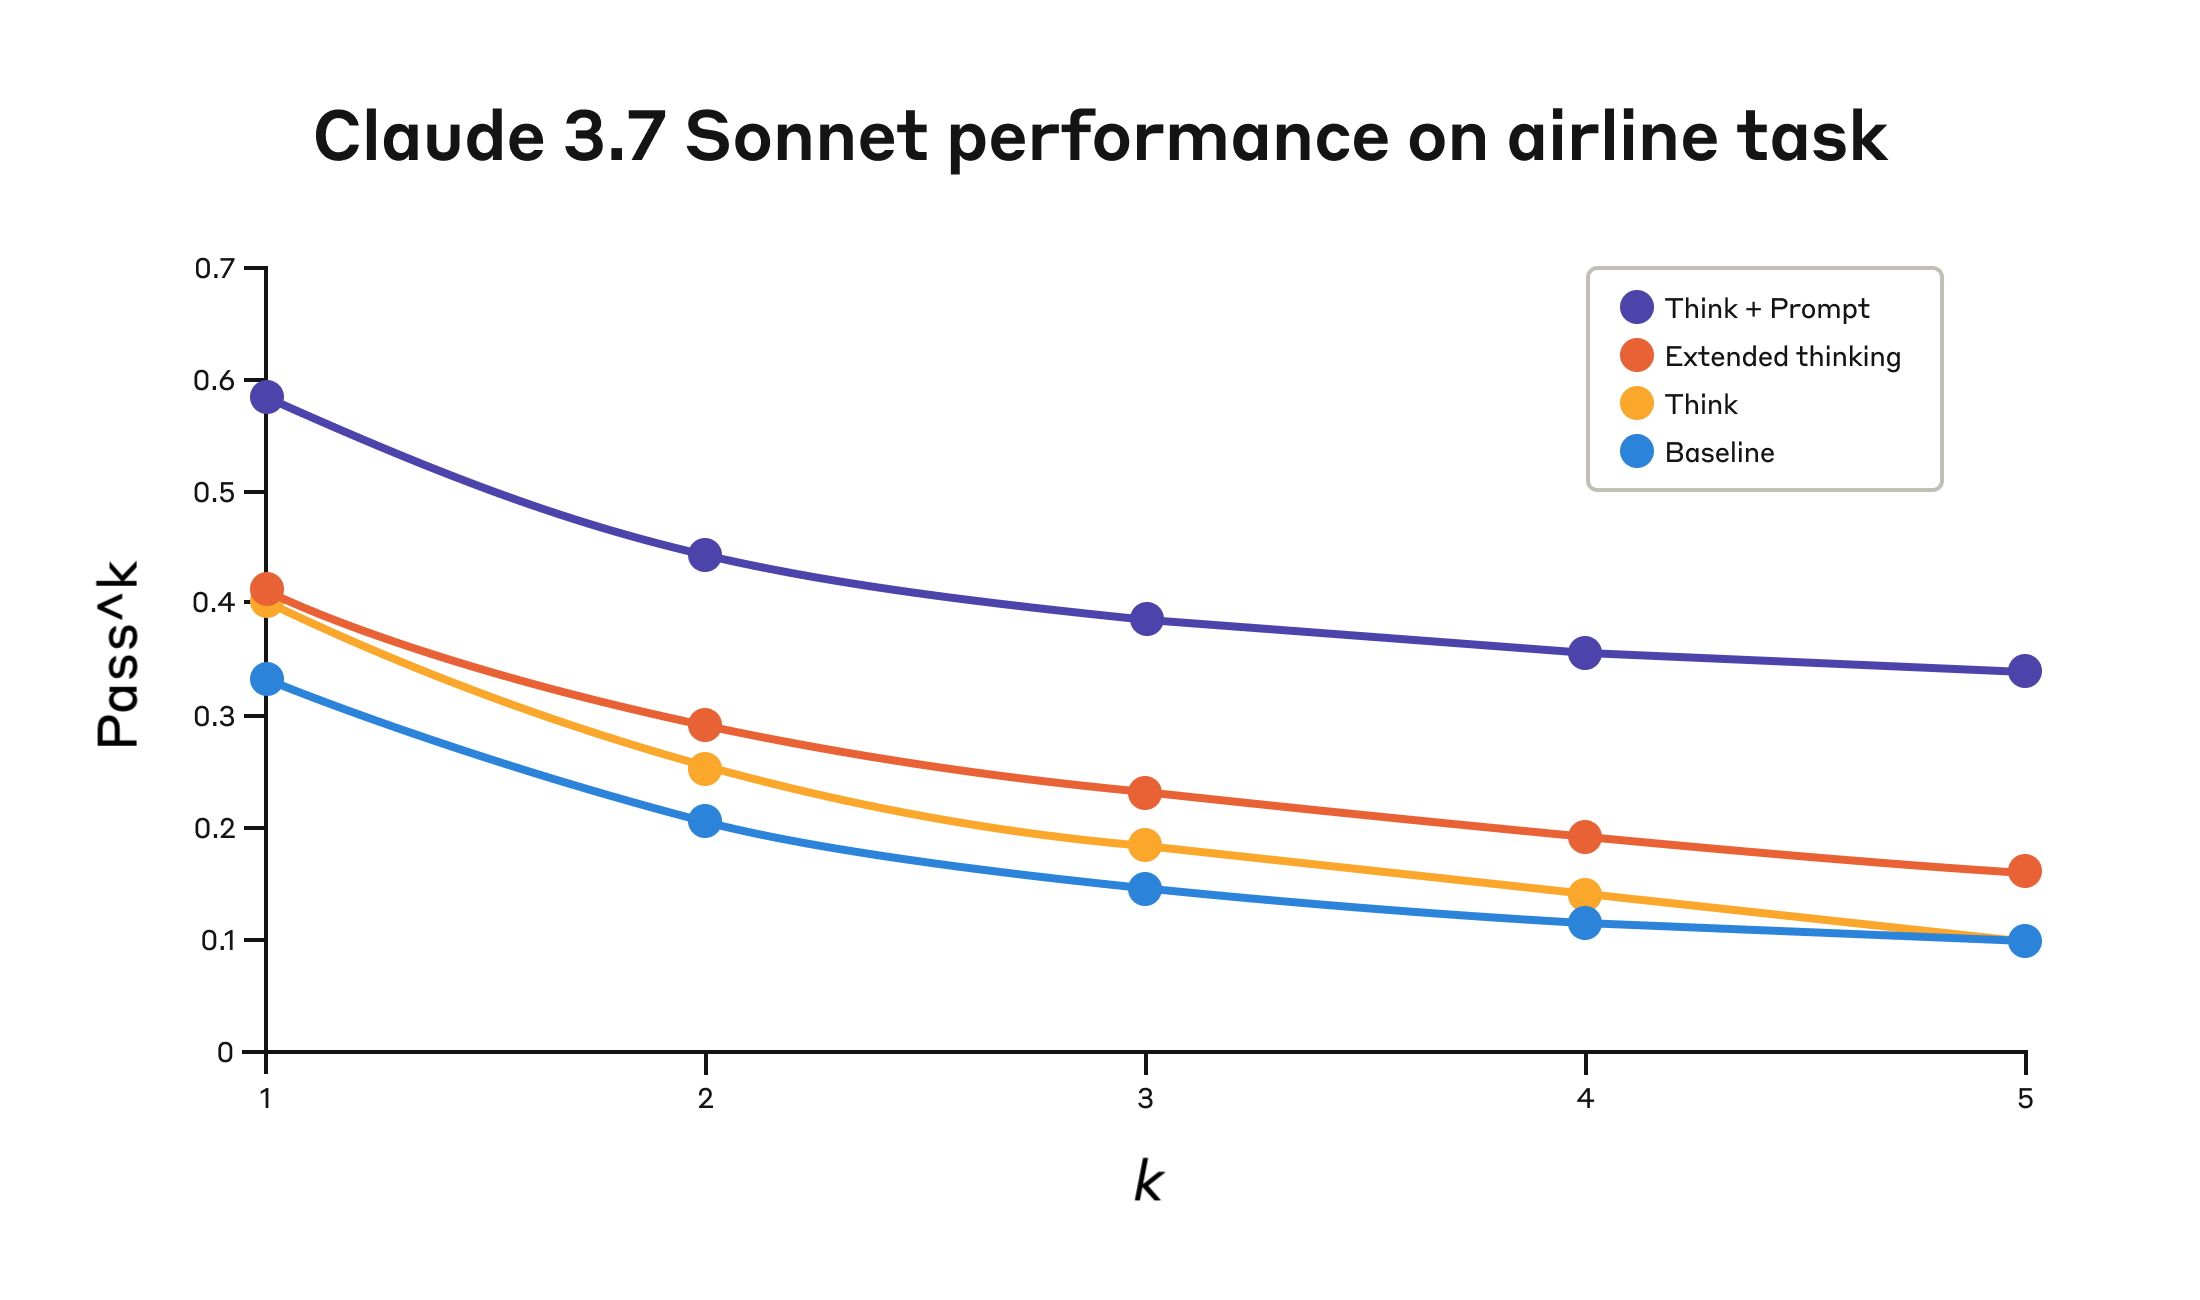
Claude 3.7 Sonnet 在 Tau-Bench 评测“航空”业务场景中的表现
Claude 3.7 Sonnet's performance on the "Airline" domain of the Tau-Bench eval
四种不同配置的评测结果。分数以比例表示。
Evaluation results across four different configurations. Scores are proportions.
在航空业务场景中,将“think”工具与优化后的提示词搭配使用,取得了最佳表现。这段提示词通过示例展示了分析客户请求时应采用的推理方式。下面是优化后提示词的一个示例:
The best performance in the airline domain was achieved by pairing the “think” tool with an optimized prompt that gives examples of the type of reasoning approaches to use when analyzing customer requests. Below is an example of the optimized prompt:
特别有意思的是不同方法之间的比较。“think”工具搭配优化后的提示词,明显优于扩展思考模式;扩展思考模式的表现则与不附加专门提示词的“think”工具相近。仅使用“think”工具而不添加专门提示词,也能超越基线,但仍不及优化后的方法。
What's particularly interesting is how the different approaches compared. Using the “think” tool with the optimized prompt achieved significantly better results over extended thinking mode (which showed similar performance to the unprompted “think” tool). Using the "think" tool alone (without prompting) improved performance over baseline, but still fell short of the optimized approach.
“think”工具与优化提示词的组合,以明显优势取得了最强表现。这可能是因为基准测试中的航空业务规则十分复杂,因此模型在获得如何“思考”的示例后,受益最大。
The combination of the "think" tool with optimized prompting delivered the strongest performance by a significant margin, likely due to the high complexity of the airline policy part of the benchmark, where the model benefitted the most from being given examples of how to “think.”
在零售业务场景中,我们也测试了多种配置,以了解各个方法的具体影响。
In the retail domain, we also tested various configurations to understand the specific impact of each approach
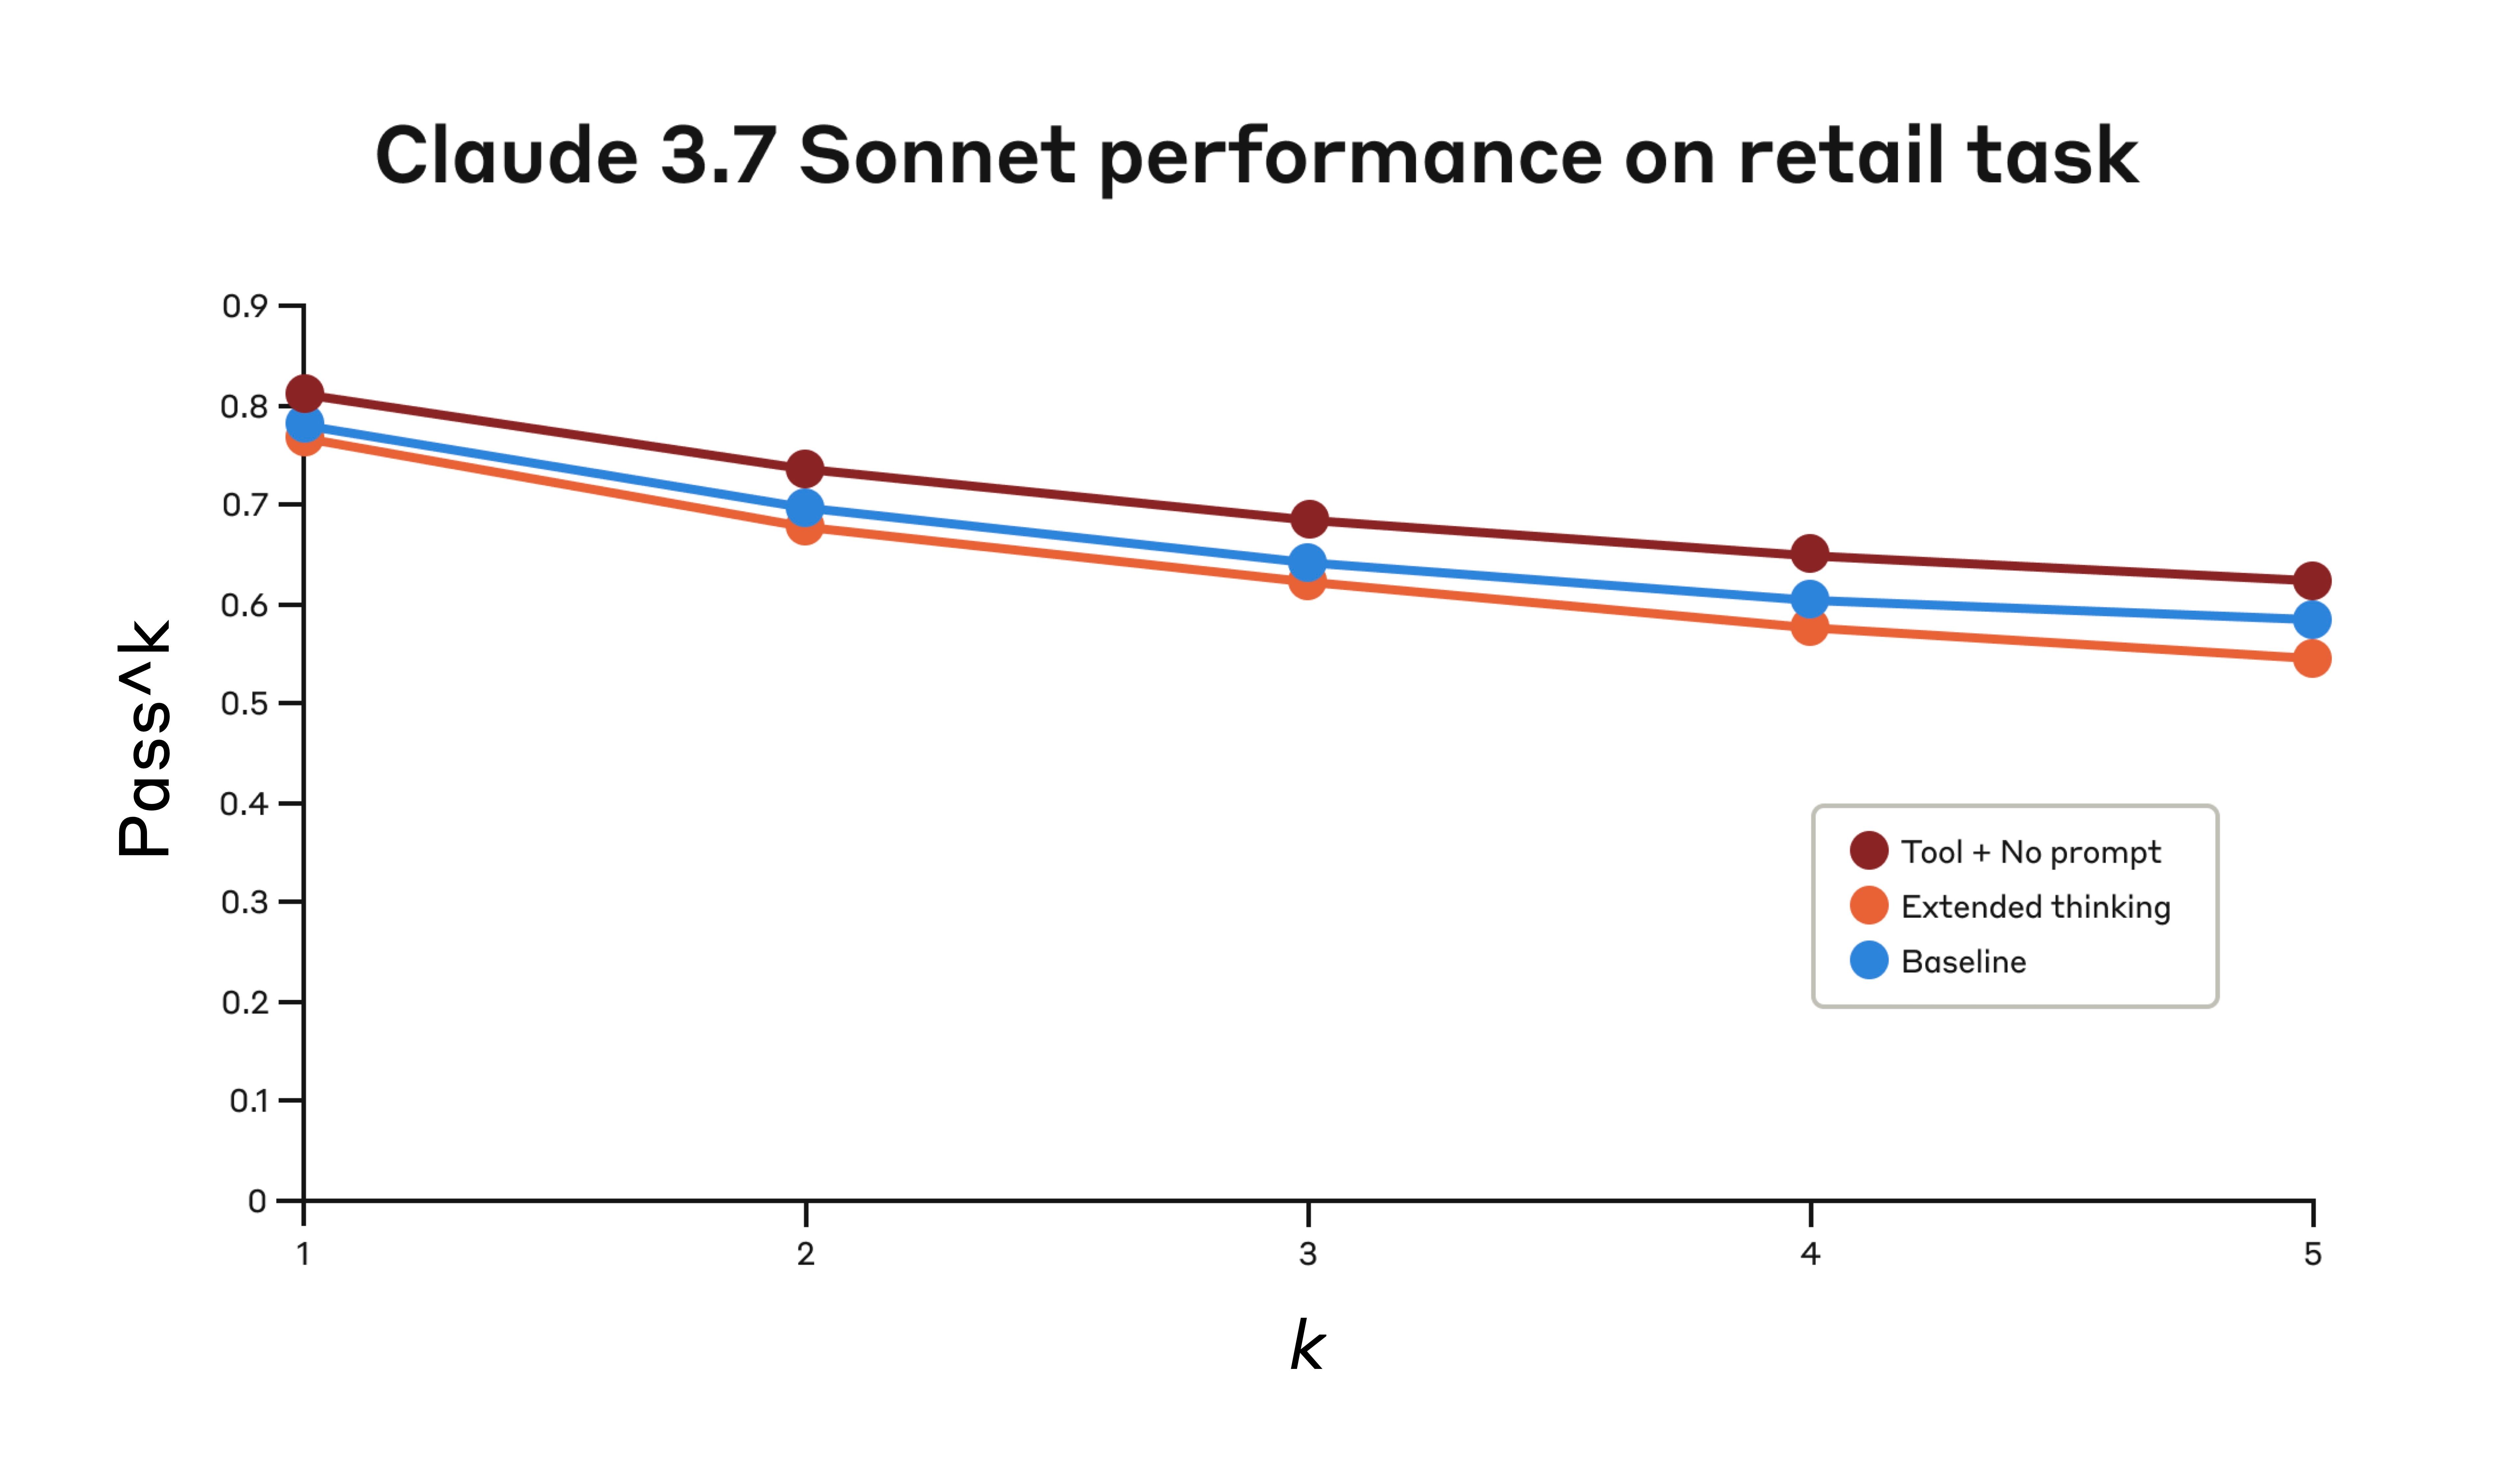
Claude 3.7 Sonnet 在 Tau-Bench 评测“零售”业务场景中的表现
Claude 3.7 Sonnet's performance on the "Retail" domain of the Tau-Bench eval
三种不同配置的评测结果。分数以比例表示。
Evaluation results across three different configurations. Scores are proportions.
即使没有额外提示词,“think”工具也取得了最高的 pass^1 分数 0.812。与航空业务场景相比,零售业务规则明显更容易处理,Claude 只要拥有思考空间,不需要进一步指导,就能取得提升。
The "think" tool achieved the highest pass^1 score of 0.812 even without additional prompting. The retail policy is noticeably easier to navigate compared to the airline domain, and Claude was able to improve just by having a space to think without further guidance.
τ-Bench 分析中的关键发现
Key Insights from τ-Bench Analysis
我们的详细分析揭示了几种规律,可以帮助你有效实现“think”工具:
Our detailed analysis revealed several patterns that can help you implement the "think" tool effectively:
- 在困难场景中,提示词的影响很大。仅仅提供“think”工具,可能就会带来一些性能提升,但在困难场景中,将其与优化提示词搭配使用,结果会显著更好。对于较简单的场景,只需能够使用“think”就可能受益。
- 各次尝试的一致性得到改善。使用“think”带来的提升,在 pass^k 指标的 k 增大到 5 时仍然保持,这说明该工具帮助 Claude 更有效地处理了边界情况和异常场景。
- Prompting matters significantly on difficult domains. Simply making the "think" tool available might improve performance somewhat, but pairing it with optimized prompting yielded dramatically better results for difficult domains. However, easier domains may benefit from simply having access to “think.”
- Improved consistency across trials. The improvements from using “think” were maintained for pass^k up to k=5, indicating that the tool helped Claude handle edge cases and unusual scenarios more effectively.
在 SWE-Bench 上的表现
Performance on SWE-Bench
评估 Claude 3.7 Sonnet 时,我们也在 SWE-bench 配置中加入了一个类似的“think”工具,为取得当时最先进的 0.623 分成绩作出了贡献。调整后的“think”工具定义如下:
A similar “think” tool was added to our SWE-bench setup when evaluating Claude 3.7 Sonnet, contributing to the achieved state-of-the-art score of 0.623. The adapted “think” tool definition is given below:
我们的实验中,使用“think”工具的样本数为 n=30,不使用该工具的样本数为 n=144。实验显示,单独加入这个工具的效果,是使性能平均提升 1.6%(Welch t 检验:t(38.89) = 6.71,p < .001,d = 1.47)。
Our experiments (n=30 samples with "think" tool, n=144 samples without) showed the isolated effects of including this tool improved performance by 1.6% on average (Welch's t-test: t(38.89) = 6.71, p < .001, d = 1.47).
何时使用“think”工具
When to use the "think" tool
根据这些评测结果,我们确定了 Claude 使用“think”工具时受益最大的几种具体场景:
Based on these evaluation results, we've identified specific scenarios where Claude benefits most from the "think" tool:
- 分析工具输出。Claude 需要在行动前仔细处理此前工具调用的输出,而且可能需要回头调整方法;
- 规则繁多的环境。Claude 需要遵循详细指导要求,并核实是否符合规则;以及
- 序贯决策。每个动作都建立在之前动作的基础上,且出错代价很高,这在多步骤场景中很常见。
- Tool output analysis. When Claude needs to carefully process the output of previous tool calls before acting and might need to backtrack in its approach;
- Policy-heavy environments. When Claude needs to follow detailed guidelines and verify compliance; and
- Sequential decision making. When each action builds on previous ones and mistakes are costly (often found in multi-step domains).
实现最佳实践
Implementation best practices
为充分发挥 Claude 使用“think”工具的效果,我们根据 τ-bench 实验,推荐以下实现做法。
To get the most out of the "think" tool with Claude, we recommend the following implementation practices based on our τ-bench experiments.
1. 使用领域专属示例,有针对性地编写提示词
1. Strategic prompting with domain-specific examples
最有效的方法,是明确说明何时以及如何使用“think”工具,例如我们在 τ-bench 航空业务场景中采用的提示词。提供针对具体用例的示例,可以显著提高模型使用“think”工具的有效性。这些示例应说明:
The most effective approach is to provide clear instructions on when and how to use the "think" tool, such as the one used for the τ-bench airline domain. Providing examples tailored to your specific use case significantly improves how effectively the model uses the "think" tool:
- 推理过程预期达到的详细程度;
- 如何将复杂指令拆解为可执行步骤;
- 处理常见场景的决策树;以及
- 如何检查是否已经收集到全部必要信息。
- The level of detail expected in the reasoning process;
- How to break down complex instructions into actionable steps;
- Decision trees for handling common scenarios; and
- How to check if all necessary information has been collected.
2. 将复杂指导放入系统提示词
2. Place complex guidance in the system prompt
我们发现,当关于“think”工具的说明较长或较复杂时,将其放在系统提示词中,比放在工具描述本身更有效。这种做法提供了更广泛的上下文,帮助模型把思考过程更好地融入整体行为。
We found that, when they were long and/or complex, including instructions about the "think" tool in the system prompt was more effective than placing them in the tool description itself. This approach provides broader context and helps the model better integrate the thinking process into its overall behavior.
何时不应使用“think”工具
When not to use the "think" tool
虽然“think”工具能带来显著提升,但它并不适用于所有工具使用场景,而且会增加提示词长度与输出 token。具体来说,我们发现,在以下用例中,“think”工具没有带来任何改善:
Whereas the “think” tool can offer substantial improvements, it is not applicable to all tool use use cases, and does come at the cost of increased prompt length and output tokens. Specifically, we have found the “think” tool does not offer any improvements in the following use cases:
- 不依赖先后顺序的工具调用。如果 Claude 只需进行一次工具调用,或多次并行调用就能完成任务,那么加入“think”不太可能带来改善。
- 简单的指令遵循。当 Claude 需要遵守的约束不多,而默认行为已经足够好时,额外使用“think”来思考不太可能带来收益。
- Non-sequential tool calls. If Claude only needs to make a single tool call or multiple parallel calls to complete a task, there is unlikely to be any improvements from adding in “think.”
- Simple instruction following. When there are not many constraints to which Claude needs to adhere, and its default behaviour is good enough, there are unlikely to be gains from additional “think”-ing.
开始使用
Getting started
将“think”工具加入 Claude 应用很简单,只需几个步骤,就可能带来有意义的改善:
The "think" tool is a straightforward addition to your Claude implementation that can yield meaningful improvements in just a few steps:
- 在 Agent 工具使用场景中测试。从具有挑战性的用例入手,例如 Claude 目前在长工具调用链中难以遵守业务规则或完成复杂推理的情况。
- 添加工具定义。实现一个针对你的领域定制的“think”工具。它只需少量代码,却能支持更有结构的推理。同时,可以考虑在系统提示词中加入何时以及如何使用该工具的说明,并提供与你的领域相关的示例。
- 监测并改进。观察 Claude 在实际运行中如何使用该工具,并调整提示词,鼓励更有效的思考模式。
- Test with agentic tool use scenarios. Start with challenging use cases—ones where Claude currently struggles with policy compliance or complex reasoning in long tool call chains.
- Add the tool definition. Implement a "think" tool customized to your domain. It requires minimal code but enables more structured reasoning. Also consider including instructions on when and how to use the tool, with examples relevant to your domain to the system prompt.
- Monitor and refine. Watch how Claude uses the tool in practice, and adjust your prompts to encourage more effective thinking patterns.
最有利的一点是,从实际性能结果来看,加入这个工具几乎没有负面影响。除非 Claude 决定使用它,否则它不会改变外部行为,也不会干扰现有工具或工作流。
The best part is that adding this tool has minimal downside in terms of performance outcomes. It doesn't change external behavior unless Claude decides to use it, and doesn't interfere with your existing tools or workflows.
结语
Conclusion
我们的研究表明,对于需要遵守业务规则、并在长工具调用链中进行推理的复杂任务,“think”工具可以显著提升 Claude 3.7 Sonnet 的性能1。“think”并不是适合所有情况的通用解法,但在恰当的用例中,它能以很低的实现复杂度带来显著收益。
Our research has demonstrated that the "think" tool can significantly enhance Claude 3.7 Sonnet's performance1 on complex tasks requiring policy adherence and reasoning in long chains of tool calls. “Think” is not a one-size-fits-all solution, but it offers substantial benefits for the correct use cases, all with minimal implementation complexity.
我们期待看到你如何使用“think”工具,与 Claude 一起构建能力更强、更可靠、更透明的 AI 系统。
We look forward to seeing how you'll use the "think" tool to build more capable, reliable, and transparent AI systems with Claude.
1. 虽然 τ-Bench 的结果聚焦于“think”工具对 Claude 3.7 Sonnet 的改进,但我们的实验表明,Claude 3.5 Sonnet(New)采用与 3.7 Sonnet 相同的配置,也能取得性能提升,这说明此项改进同样可以推广到其他 Claude 模型。
1. While our τ-Bench results focused on the improvement of Claude 3.7 Sonnet with the “think” tool, our experiments show Claude 3.5 Sonnet (New) is also able to achieve performance gains with the same configuration as 3.7 Sonnet, indicating that this improvement generalizes to other Claude models as well.
— 全文完 —
原文来自 Anthropic,中文为非官方学习译文。
查看原始出处 ↗